
BIOL-207 · Lesson 12 of 12 · 35 min
Molecular techniques II and capstone: sequencing, genome editing and an investigation
Lesson 11 showed how to cut, copy and clone DNA. This final lesson covers the two technologies that have most changed biology and medicine in the twenty-first century: reading DNA at scale, and rewriting it precisely. It explains Sanger sequencing and the high-throughput methods that followed, the mathematics of sequencing coverage, how RNA sequencing measures gene expression, how CRISPR–Cas9 edits genomes, and how mRNA vaccines turned molecular biology into a medicine given to billions of people. It closes with the rules that govern recombinant DNA work in Canada and the United States, and an invented investigation that brings the course together.
Sanger sequencing
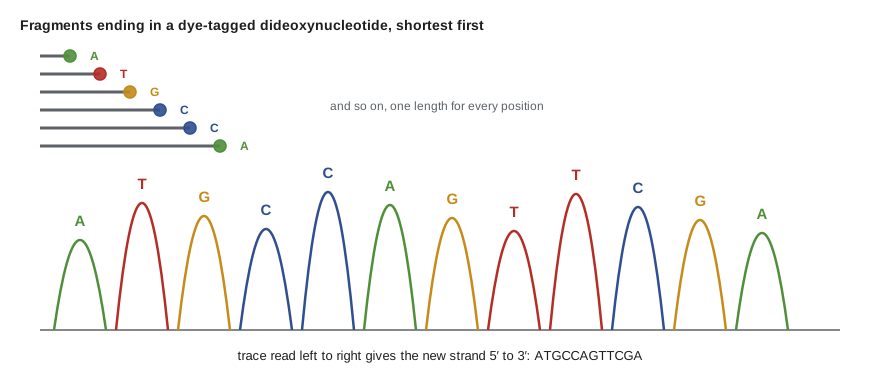
In 1977 Frederick Sanger, at Cambridge, published the dideoxy chain-termination method, which earned him his second Nobel Prize in Chemistry (1980), the first having been for sequencing insulin. The method copies a template with DNA polymerase from a primer, in the presence of the four normal dNTPs and a small amount of dideoxynucleotides (ddNTPs). A ddNTP lacks the 3′-OH group as well as the 2′-OH, so once it is added, no further nucleotide can join: the chain terminates. Because ddNTPs are added only occasionally, the reaction produces a set of fragments ending at every position, each ending with a ddNTP that identifies the base at that position.
In modern Sanger sequencing, each of the four ddNTPs carries a different fluorescent dye, all four are in one reaction, and the fragments are separated by size in a thin capillary filled with polymer. A laser excites the dyes as fragments pass a detector, smallest first, and the sequence is read from the order of colours. Reads of 700 to 1,000 bases are typical, with very high accuracy, so Sanger sequencing remains the standard for checking cloned plasmids, PCR products and specific mutations.
import random
random.seed(207)
COMP = str.maketrans("ACGT", "TGCA")

template_3to5 = "TACGGTCAAGCTTAGGCTA"            # template strand written 3'->5'
new_strand = template_3to5.translate(COMP)     # strand synthesized 5'->3' from the primer

# Simulate many polymerase copies; each position has a small chance of ddNTP termination
fragments = set()
for _ in range(3000):
    for length, base in enumerate(new_strand, start=1):
        if random.random() < 0.08:
            fragments.add((length, base))
            break

read = "".join(base for length, base in sorted(fragments))
print("fragment lengths observed:", len(fragments), "of", len(new_strand))
print("base calls (shortest first):", read)
print("matches the complement of the template:", read == new_strand)fragment lengths observed: 19 of 19 base calls (shortest first): ATGCCAGTTCGAATCCGAT matches the complement of the template: True
High-throughput sequencing
The Human Genome Project, completed in 2003 at a cost of about US$3 billion, relied on Sanger sequencing. Since about 2007, high-throughput or next-generation methods have reduced the cost of a human genome to a few hundred US dollars. The most widely used, sequencing by synthesis (developed by the company Illumina, from technology invented at Cambridge), attaches millions of short DNA fragments to a glass surface, amplifies each into a cluster, and then reads them all in parallel by adding fluorescently labelled, reversibly terminated nucleotides one cycle at a time and imaging the surface after each. Reads are short, typically 100 to 300 bases, but billions are produced per run.
Long-read methods read single molecules over tens of thousands of bases. Pacific Biosciences watches a single polymerase incorporating labelled nucleotides in a tiny well. Oxford Nanopore threads DNA through a protein pore in a membrane and identifies bases from changes in electric current; its sequencers can be as small as a USB stick and have been used in the field during outbreaks. Long reads span repetitive regions that short reads cannot resolve. In 2022 the Telomere-to-Telomere consortium used long reads to publish the first truly complete sequence of a human genome, filling the roughly 8 per cent left unresolved since 2003, mostly centromeres and other repeats.
| Method | Read length | Main strengths | Typical uses |
|---|---|---|---|
| Sanger (dye terminator) | 700–1,000 bases | Very accurate single reads | Checking clones, PCR products, single mutations |
| Short-read sequencing by synthesis | 100–300 bases | Billions of reads, low cost per base | Whole genomes, exomes, RNA-seq, cancer panels |
| Single-molecule real-time (PacBio) | 10,000–25,000 bases | Long and, in current versions, highly accurate reads | Genome assembly, structural variants |
| Nanopore | Thousands to over 1 million bases | Very long reads; portable; reads native DNA and RNA | Assembly, outbreak surveillance, direct detection of methylation |
Coverage
Short reads must be assembled or mapped to a reference genome, and because reads land at random, some positions are covered many times and some not at all. Eric Lander and Michael Waterman showed in 1988 that if N reads of length L are drawn at random from a genome of size G, the average coverage C, the number of times each base is read on average, and the expected fraction of bases never covered follow simple formulas. The number of reads covering a position is approximately Poisson distributed.
Worked problem
Planning a sequencing run
You plan to sequence a 3.1 Gb human genome with 150-base reads to an average coverage of 30×. How many reads are needed, and what fraction of bases is expected to have zero coverage?
Show solution
- N = C × G / L = 30 × 3.1 × 10⁹ / 150 = 6.2 × 10⁸ reads.
- Fraction uncovered = e^(−30) ≈ 9 × 10⁻¹⁴, effectively zero.
- In practice, coverage is uneven: GC-rich and repetitive regions are under-represented, so real runs have more gaps than the Poisson model predicts.
Answer: About 620 million reads. With random reads the model predicts essentially no uncovered bases at 30× coverage, but real data show gaps in difficult regions.
import numpy as np
rng = np.random.default_rng(207)

G, L = 100_000, 150          # a small genome, so the simulation runs quickly
for C in (1, 3, 5, 10):
    N = int(C * G / L)
    starts = rng.integers(0, G - L, N)
    depth = np.zeros(G, dtype=int)
    for s in starts:
        depth[s:s+L] += 1
    print(f"coverage {C:2d}x: {N:6,d} reads, uncovered {np.mean(depth == 0):.4f} "
f"(Poisson predicts {np.exp(-C):.4f}), mean depth {depth.mean():.2f}")coverage 1x: 666 reads, uncovered 0.3646 (Poisson predicts 0.3679), mean depth 1.00 coverage 3x: 2,000 reads, uncovered 0.0511 (Poisson predicts 0.0498), mean depth 3.00 coverage 5x: 3,333 reads, uncovered 0.0073 (Poisson predicts 0.0067), mean depth 5.00 coverage 10x: 6,666 reads, uncovered 0.0006 (Poisson predicts 0.0000), mean depth 10.00
RNA sequencing
Sequencing cDNA made from a cell’s RNA (RNA-seq) measures the expression of every gene at once. The number of reads that map to a gene reflects how much of its mRNA was present, but raw counts must be normalized. Deeper sequencing gives more reads overall, so counts are scaled to counts per million mapped reads (CPM). Longer transcripts produce more fragments per molecule, so comparisons between genes use measures such as transcripts per million (TPM), which divide by length first. Rigorous comparisons between conditions use statistical models of count data and replicates, a topic for BIOL-410. Single-cell RNA-seq now measures expression in thousands of individual cells, revealing cell types and states that bulk measurements average away.
import numpy as np

genes = ["GAPDH", "ACTB", "MYC", "INS", "TINY1"]
length_kb = np.array([1.4, 1.8, 2.4, 0.5, 0.3])          # transcript lengths (illustrative)
counts = {"sample A": np.array([52000, 61000, 3100, 12, 900]),
          "sample B": np.array([98000, 120000, 14500, 30, 1650])}

for name, c in counts.items():
    cpm = c / c.sum() * 1e6
    rpk = c / length_kb
    tpm = rpk / rpk.sum() * 1e6
    print(name, f"(total {c.sum():,d} reads)")
    for g, x, t in zip(genes, cpm, tpm):
print(f" {g:6s} CPM {x:10,.0f} TPM {t:10,.0f}")sample A (total 117,012 reads) GAPDH CPM 444,399 TPM 492,955 ACTB CPM 521,314 TPM 449,768 MYC CPM 26,493 TPM 17,143 INS CPM 103 TPM 319 TINY1 CPM 7,692 TPM 39,816 sample B (total 234,180 reads) GAPDH CPM 418,482 TPM 472,117 ACTB CPM 512,426 TPM 449,635 MYC CPM 61,918 TPM 40,748 INS CPM 128 TPM 405 TINY1 CPM 7,046 TPM 37,095
Sample B has nearly twice as many reads as sample A, so its raw counts are higher for every gene, but after normalization the housekeeping genes look similar while MYC is clearly higher in B. TPM also reveals that the short TINY1 transcript is relatively more abundant than its raw count suggests, because short transcripts give fewer fragments per molecule.
Genome editing with CRISPR–Cas9
Lesson 9 introduced CRISPR as a bacterial immune system. In the engineered version, the Cas9 protein from Streptococcus pyogenes is combined with a single guide RNA (sgRNA) whose first 20 nucleotides match the DNA target. Cas9 scans DNA for a short protospacer-adjacent motif (PAM), 5′-NGG-3′ for this enzyme, where N is any base. At each PAM it tests whether the adjacent 20 nucleotides pair with the guide; if they do, it cuts both strands about 3 bp upstream of the PAM, making a blunt double-strand break. The requirement for a PAM is part of how bacteria avoid cutting their own CRISPR arrays.
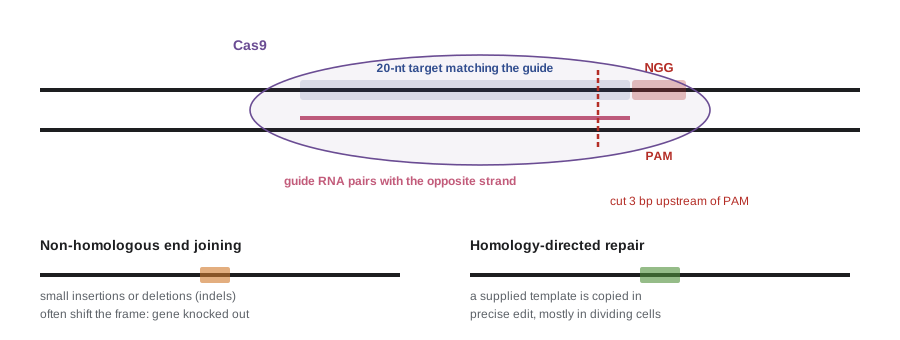
The cell repairs the break, and the repair pathway determines the outcome. Non-homologous end joining (NHEJ), the main pathway in most cells, rejoins the ends but often adds or removes a few bases. In a coding sequence, such insertions or deletions (indels) usually shift the reading frame (lesson 7) and knock out the gene. If a DNA template with homology to the sequences around the cut is supplied, homology-directed repair (HDR) can copy it into the genome, introducing a chosen change, although HDR is inefficient in non-dividing cells. Newer tools avoid double-strand breaks altogether. Base editors fuse a disabled Cas9 to an enzyme that chemically converts one base to another, C to T or A to G, at the target. Prime editors use a Cas9 nickase fused to a reverse transcriptase and an extended guide RNA that carries the desired edit as a template.
COMP = str.maketrans("ACGT", "TGCA")
def rc(s): return s.translate(COMP)[::-1]

def find_guides(dna):
    """Find 20-nt protospacers followed by NGG on either strand; return (strand, position, guide, PAM)."""
    hits = []
    for strand, seq in (("+", dna), ("-", rc(dna))):
        for i in range(20, len(seq) - 2):
            pam = seq[i:i+3]
            if pam[1:] == "GG":
                guide = seq[i-20:i]
                gc = (guide.count("G") + guide.count("C")) / 20
                hits.append((strand, i - 20, guide, pam, gc))
    return hits

exon = "ATGGACTTCCTGCAGTACAAGCTGGAGCGCATCGCCAACGGTGAGTTC"   # invented exon sequence
for strand, pos, guide, pam, gc in find_guides(exon):
    flag = "" if 0.40 <= gc <= 0.70 else "  (GC outside 40-70%)"
print(f"{strand} pos {pos:2d} guide {guide} PAM {pam} GC {gc:.0%}{flag}")+ pos 2 guide GGACTTCCTGCAGTACAAGC PAM TGG GC 55% + pos 18 guide AAGCTGGAGCGCATCGCCAA PAM CGG GC 60% - pos 17 guide TGCGCTCCAGCTTGTACTGC PAM AGG GC 60%
In practice, guide design software also scores each candidate for likely activity and, crucially, searches the whole genome for off-target sites that differ from the guide by only a few mismatches, since cutting elsewhere could disrupt other genes. Choosing guides near the start of the coding sequence, in exons shared by all isoforms (lesson 6), makes a knockout more likely.
CRISPR editing has moved into medicine. Casgevy, approved in the United Kingdom, the United States, Canada and elsewhere in 2023 and 2024, edits a patient’s own blood stem cells to disrupt an enhancer of the BCL11A gene, which normally represses fetal hemoglobin; the cells are returned after chemotherapy and produce fetal hemoglobin that compensates for defective adult hemoglobin in sickle cell disease and β-thalassemia (BIOL-201 lesson 5). In 2025 a team in Philadelphia reported the first personalized base-editing treatment, designed in months for a single infant with a rare liver enzyme deficiency. Heritable editing of human embryos for reproduction remains prohibited in Canada under the Assisted Human Reproduction Act and is blocked in the United States by restrictions on the Food and Drug Administration (BIOL-201 lesson 12).
mRNA vaccines
For decades, using mRNA as a medicine seemed impractical because injected RNA triggers inflammation and is degraded quickly. Katalin Karikó and Drew Weissman, at the University of Pennsylvania, found in 2005 that replacing uridine with modified nucleosides, such as pseudouridine (later N1-methylpseudouridine), allows mRNA to avoid much of the innate immune response and be translated efficiently. They received the 2023 Nobel Prize in Physiology or Medicine. The other key ingredient is delivery: lipid nanoparticles, tiny fat droplets that protect the mRNA and carry it into cells, were developed over many years by researchers including Pieter Cullis at the University of British Columbia and companies in Vancouver.
An mRNA vaccine contains a capped, polyadenylated mRNA (lesson 6) encoding a viral protein, for COVID-19 the spike protein. Cells near the injection site and in lymph nodes translate it (lesson 7), display the protein, and the immune system learns to recognize it (BIOL-380). The mRNA is degraded within days and does not enter the nucleus or alter DNA. Billions of doses were given during the COVID-19 pandemic. Policy on mRNA research has since diverged. In August 2025 the US Department of Health and Human Services cancelled about US$500 million in mRNA vaccine development projects funded through its Biomedical Advanced Research and Development Authority, while in Canada, a Moderna facility in Laval, Quebec, built under an agreement with the federal government, produced the first Canadian-made doses of its COVID-19 vaccine in September 2025, part of a strategy to rebuild domestic vaccine production. Scientists continue to develop mRNA approaches for influenza, cancer immunotherapy and rare diseases.
Rules for recombinant DNA work
In Canada, laboratory work with human and animal pathogens and toxins, including many recombinant organisms, is governed by the Human Pathogens and Toxins Act and its regulations, administered by the Public Health Agency of Canada (PHAC). Facilities need a licence for most such work and must follow the Canadian Biosafety Standard, now in its third edition (2022), which sets physical containment levels from CL1 to CL4 and operational practices, together with a biosecurity addendum. Institutions appoint biological safety officers and biosafety committees to review projects, including recombinant DNA work that could change a microorganism’s risk. Work with genetically modified plants and animals released into the environment, or used in food, falls under the Canadian Food Inspection Agency, Health Canada and Environment and Climate Change Canada.
| Topic | Canada | United States |
|---|---|---|
| Main laboratory law or policy | Human Pathogens and Toxins Act; Canadian Biosafety Standard (3rd ed., 2022) | NIH Guidelines (condition of NIH funding); BMBL 6th ed. |
| Review body | Institutional biosafety committee and biological safety officer; PHAC licence | Institutional Biosafety Committee (IBC) |
| Containment levels | CL1–CL4 | BSL-1–BSL-4 |
| Dangerous agents | Security-sensitive biological agents under the Act | Federal Select Agent Program |
| Environmental release | CFIA, Health Canada, Environment and Climate Change Canada | USDA, EPA and FDA under the Coordinated Framework |
| Heritable human genome editing | Prohibited (Assisted Human Reproduction Act) | Blocked by appropriations restriction on FDA review |
Beyond formal rules, molecular biologists face questions of dual use: knowledge or methods developed for beneficial purposes that could be misused. Professional norms, such as screening orders for synthetic DNA against databases of dangerous sequences, now practised by most commercial providers, complement regulation.
Capstone: an invented investigation
A research group studies a gene, here called RLX1, that they suspect helps cultured human liver cells respond to stress. The data below are invented for teaching. Their plan uses methods from across the course: design guides to knock out the gene, confirm the edit by sequencing, and measure the effect on a downstream gene by RT-qPCR.
Step 1 is guide design. They choose a 20-nucleotide guide in exon 2, shared by all splice isoforms, next to an AGG PAM, with 55 per cent GC and no close matches elsewhere in the genome according to off-target software. Step 2 is editing and verification. They deliver Cas9 and the guide as a ribonucleoprotein complex, grow single-cell clones, amplify the target region by PCR and sequence the amplicons with short reads. Step 3 is expression analysis: in a knockout clone and in unedited control cells, they treat with a stress agent and measure a target gene, STR2, relative to a reference gene.
import random
from collections import Counter
random.seed(207)

ref = "GACTTCCTGCAGTACAAGCTGGAGCGCATC"    # amplicon region around the cut site (invented)
cut = 15                                  # cut position within the amplicon

def read_from(allele):
    if allele == "wt":
        return ref
    if allele == "del4":
        return ref[:cut-2] + ref[cut+2:]
    if allele == "ins1":
        return ref[:cut] + "A" + ref[cut:]

# A clone that is compound heterozygous for two edits, plus a little sequencing noise
reads = [read_from(random.choice(["del4", "ins1"])) for _ in range(2000)]
reads += [ref for _ in range(30)]          # small contamination with unedited cells
calls = Counter("wt" if r == ref else f"indel {len(r) - len(ref):+d} bp" for r in reads)
total = sum(calls.values())
for allele, n in calls.most_common():
    print(f"{allele:12s} {n:5d} reads  {n/total:6.1%}")
frameshift = sum(n for a, n in calls.items() if a != "wt" and int(a.split()[1]) % 3 != 0)
print(f"reads with frameshift indels: {frameshift/total:.1%}")indel -4 bp 1003 reads 49.4% indel +1 bp 997 reads 49.1% wt 30 reads 1.5% reads with frameshift indels: 98.5%
The clone carries two different edits, a 4 bp deletion on one allele and a 1 bp insertion on the other, both shifting the reading frame, with a trace of unedited reads that most likely come from a few contaminating cells. Neither indel is a multiple of three, so both alleles should produce truncated proteins, and the mRNAs are likely targets for nonsense-mediated decay (lesson 6). The group confirms loss of the protein by Western blot.
Worked problem
Analysing the expression result
After stress treatment, STR2 has Ct 24.1 and the reference gene Ct 17.9 in control cells; in the knockout, STR2 has Ct 26.6 and the reference Ct 18.0. What is the fold change in STR2 in the knockout, and what does it suggest?
Show solution
- ΔCt control = 24.1 − 17.9 = 6.2; ΔCt knockout = 26.6 − 18.0 = 8.6.
- ΔΔCt = 8.6 − 6.2 = 2.4.
- Fold change = 2^(−2.4) ≈ 0.19.
Answer: STR2 expression in the knockout is about one fifth of the control, suggesting that RLX1 is needed for full induction of STR2 under stress. Before concluding, the group would test more clones and a second guide to rule out off-target effects, and restore RLX1 from a cloned copy (a rescue experiment) to show the effect is due to its loss.
Good practice runs through the whole design: independent clones and guides, biological replicates, a rescue experiment, and transparent reporting of methods. The work also requires biosafety review. Editing human cell lines with Cas9 delivered as protein is low-risk laboratory work in both countries, but the group must register it with their institutional committee, and work with lentiviral vectors to deliver Cas9 would raise the containment level.
Looking back
From Griffith’s mice to base editing, this course has followed one idea: heredity is chemistry. The double helix stores information, polymerases copy it, transcription and translation express it, and regulatory proteins and RNAs decide which parts are used. The same molecules that make this possible have become tools that let us read and rewrite genomes. BIOL-410 continues with genomics and bioinformatics, BIOC-340 with the biochemistry of nucleic acids, BIOL-470 with biotechnology and BIOL-450 with cancer, where many of these mechanisms go wrong.
Common mistakes
MistakeA dideoxynucleotide terminates synthesis because it lacks a base.
InsteadIt has a base but lacks the 3′-OH needed to add the next nucleotide.
Mistake30× coverage means each base is read exactly 30 times.
Instead30× is the average; coverage at individual positions varies roughly as a Poisson distribution.
MistakeRaw RNA-seq read counts can be compared directly between samples and genes.
InsteadCounts must be normalized for sequencing depth (CPM) and, between genes, for transcript length (TPM).
MistakeCas9 cuts any 20-nucleotide sequence matching the guide.
InsteadThe target must sit next to a PAM (NGG for S. pyogenes Cas9).
MistakemRNA vaccines change the recipient’s DNA.
InsteadThe mRNA stays in the cytoplasm, is translated and is degraded; it does not enter the nucleus or alter DNA.
Summary and key terms
- Sanger sequencing uses chain-terminating ddNTPs and reads fragments by size; it remains the standard for checking specific sequences.
- Short-read sequencing produces billions of reads cheaply; long-read methods resolve repeats and completed the human genome in 2022.
- Coverage C = NL/G; the fraction of uncovered bases is about e^(−C), though real coverage is uneven.
- RNA-seq measures expression; counts are normalized as CPM for depth and TPM for transcript length.
- Cas9 with a guide RNA cuts next to an NGG PAM; NHEJ makes knockout indels, HDR makes precise edits; base and prime editors avoid breaks.
- mRNA vaccines combine modified nucleosides and lipid nanoparticles; the mRNA is translated and degraded without altering DNA.
- Recombinant DNA work is overseen by PHAC and the Canadian Biosafety Standard in Canada and by the NIH Guidelines, IBCs and BMBL in the United States.
- dideoxynucleotide (ddNTP)
- A nucleotide lacking a 3′-OH that terminates DNA synthesis when incorporated.
- read
- The sequence obtained from one DNA fragment in a sequencing run.
- coverage
- The average number of times each base in a genome is sequenced.
- RNA-seq
- Sequencing of cDNA made from RNA to measure gene expression.
- transcripts per million (TPM)
- An expression measure normalized for transcript length and sequencing depth.
- guide RNA
- An RNA that directs Cas9 to a matching DNA target.
- protospacer-adjacent motif (PAM)
- A short sequence next to the target, NGG for SpCas9, required for cutting.
- non-homologous end joining
- Repair of a double-strand break by direct rejoining, often leaving small indels.
- base editing
- Chemical conversion of one base to another at a target site without a double-strand break.
- lipid nanoparticle
- A small lipid particle that protects and delivers nucleic acids into cells.
Practice problems
Work each problem on paper first, then reveal the answer to check.
Why does a ddNTP stop chain growth?
Show answer
It lacks the 3′-OH group needed to form the next phosphodiester bond.
In dye-terminator sequencing, which fragments reach the detector first?
Show answer
The shortest fragments.
How many 150-base reads give 40× coverage of a 5 Mb bacterial genome?
Show answer
40 × 5 × 10⁶ / 150 ≈ 1.33 million reads.
At 3× coverage, what fraction of bases is expected to be uncovered?
Show answer
e^(−3) ≈ 5 per cent.
Why is TPM better than raw counts for comparing two genes in one sample?
Show answer
It corrects for transcript length, since longer transcripts produce more fragments per molecule.
What PAM does SpCas9 require, and where does it cut?
Show answer
NGG; about 3 bp upstream of the PAM, leaving a blunt break.
Why do indels usually knock out a gene?
Show answer
Indels that are not multiples of three shift the reading frame, producing premature stop codons.
What advantage do base editors have over standard Cas9 editing?
Show answer
They make precise base changes without double-strand breaks.
What two innovations made mRNA vaccines practical?
Show answer
Modified nucleosides that reduce innate immune activation, and lipid nanoparticle delivery.
Name the bodies that review recombinant DNA work at institutions in Canada and in the United States.
Show answer
Institutional biosafety committees (with PHAC licensing) in Canada; Institutional Biosafety Committees under the NIH Guidelines in the US.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.