
AI-350 · Lesson 11 of 12 · 26 min
Vision-language models and document understanding
Lesson 7 introduced CLIP, which learns a shared embedding space for images and text from hundreds of millions of image-caption pairs. That idea has grown into a family of vision-language systems: models that describe images, answer questions about them, read text in photographs and documents, find objects named in free text, and, as multimodal large language models, reason about charts, screenshots, diagrams and video in conversation. This lesson explains how these systems are built, from open-vocabulary detection to multimodal language models, covers optical character recognition and document understanding, one of the most commercially important applications of computer vision, and discusses how vision-language systems are evaluated and where they fail.
Tasks that connect vision and language
| Task | Input | Output | Example use |
|---|---|---|---|
| Image captioning | image | descriptive sentence | alt text for accessibility, photo search |
| Visual question answering (VQA) | image and question | answer | "How many people are wearing hard hats?" |
| Image-text retrieval | text or image | ranked images or texts | searching a photo library by description |
| Visual grounding | image and phrase | box or mask for the phrase | "the red forklift on the left" |
| Open-vocabulary detection | image and list of class names | boxes for any named class | detecting new product types without retraining |
| OCR and document understanding | scanned or photographed document | text, layout, fields, tables | invoice processing, forms, archives |
| Multimodal chat | images, video and text | free-form text | explaining a chart, debugging a screenshot |
Open-vocabulary detection and grounding
Classical detectors (Lessons 5 and 6) recognize only the fixed set of classes they were trained on. Open-vocabulary detectors replace the final classification layer with a comparison between region features and text embeddings of class names, in the style of CLIP, so they can detect any class that can be described in words. Models such as OWL-ViT and Grounding DINO are trained on detection datasets plus large collections of image-text pairs and grounding data, in which phrases in captions are linked to boxes. Given the prompt "hard hat. safety vest. ladder.", they return boxes for each phrase. Combined with promptable segmentation (SAM, Lesson 6), they produce masks for objects described in text. Open-vocabulary detectors are less accurate than specialized detectors on any given class, but they let a team prototype a new detection task in minutes and generate candidate labels for annotators to correct.
Multimodal large language models
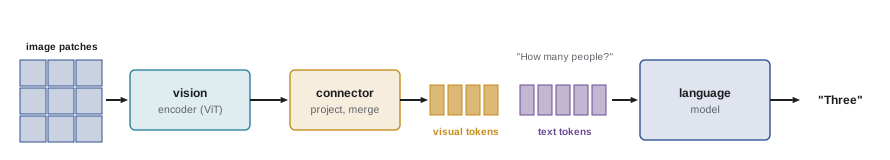
A multimodal large language model (MLLM) connects a vision encoder to a language model so that the language model can "see". The common architecture has three parts:
- A vision encoder, usually a ViT pretrained contrastively (Lesson 7), which turns an image into a grid of patch embeddings.
- A connector, such as a small multilayer perceptron or a cross-attention module, which projects the patch embeddings into the language model's embedding space, often merging neighboring patches to reduce their number. The resulting vectors act as visual tokens.
- A large language model (AI-340, Lesson 8), which receives the visual tokens interleaved with text tokens and generates text.
Training proceeds in stages: first aligning the connector on image-caption pairs with the encoder and language model frozen, then instruction tuning the whole system on varied visual tasks phrased as conversations (describe, answer, read, compare, reason), and finally preference optimization to reduce errors and improve helpfulness. Some recent models are trained natively on interleaved image and text data from the start.
import math

# Visual tokens: how many tokens an image becomes in a multimodal model, and what that costs
def tokens(w, h, patch=14, merge=2, tile=None):
    if tile:                                            # split large images into tiles of tile x tile pixels plus a thumbnail
        n_tiles = math.ceil(w / tile) * math.ceil(h / tile)
        per = (tile // patch // merge) ** 2
        return n_tiles * per + per
    return math.ceil(w / patch / merge) * math.ceil(h / patch / merge)

for name, w, h in (("phone photo resized to 1024 px", 1024, 768), ("full HD screenshot", 1920, 1080), ("A4 page scanned at 150 dpi", 1240, 1754)):
    t = tokens(w, h)
    print(f"{name:32s}: {t:5d} visual tokens at native resolution; with 448 px tiles: {tokens(w, h, tile=448):5d}")
# Compare with a short prompt and the cost of a long video at 1 frame per second
frame = tokens(448, 448)
print(f"one 448 x 448 frame: {frame} tokens; a 10-minute video at 1 frame/s: {frame * 600:,} tokens")phone photo resized to 1024 px : 1036 visual tokens at native resolution; with 448 px tiles: 1792 full HD screenshot : 2691 visual tokens at native resolution; with 448 px tiles: 4096 A4 page scanned at 150 dpi : 2835 visual tokens at native resolution; with 448 px tiles: 3328 one 448 x 448 frame: 256 tokens; a 10-minute video at 1 frame/s: 153,600 tokens
An image becomes hundreds to thousands of visual tokens, depending on its resolution. Fine detail, such as small text in a document or a dense chart, needs high resolution, which models obtain by processing the image as several tiles plus a low-resolution overview; this multiplies the token count and so the cost and latency. Video is far more expensive: at one frame per second, a ten-minute clip becomes over 150,000 tokens, so video models sample frames sparsely, compress tokens across time, or use specialized long-context methods. Choosing the input resolution is therefore a practical trade-off between accuracy on fine details and cost.
Optical character recognition
Optical character recognition (OCR) converts images of text into machine-readable characters. Modern OCR systems have two stages:
- Text detection finds regions containing text, words or lines, in documents or in natural scenes (signs, labels, license plates), using segmentation-style networks that handle curved and rotated text.
- Text recognition reads each region as a sequence. A CNN or ViT extracts features along the text line, and either a recurrent or transformer decoder generates characters, or a CTC (connectionist temporal classification) layer aligns per-column predictions with the character sequence without needing character positions in the training data.
Scene text is much harder than scanned documents because of perspective, unusual fonts, blur, lighting and clutter. Handwriting recognition adds great variability between writers, and historical documents add faded ink, unusual scripts and abbreviations. OCR accuracy is measured with the character error rate and word error rate, computed from the edit distance (the minimum number of insertions, deletions and substitutions) between the output and the ground truth, divided by the length of the ground truth:
# OCR evaluation: character error rate (CER) and word error rate (WER) from edit distance
def edit_distance(a, b):
    prev = list(range(len(b) + 1))
    for i, x in enumerate(a, 1):
        cur = [i]
        for j, y in enumerate(b, 1):
            cur.append(min(prev[j] + 1, cur[j - 1] + 1, prev[j - 1] + (x != y)))
        prev = cur
    return prev[-1]

truth = "INVOICE 4471 TOTAL DUE 1,284.50 CAD BY 2026-11-30"
outputs = {
    "good scan": "INVOICE 4471 TOTAL DUE 1,284.50 CAD BY 2026-11-30",
    "blurry photo": "INV0ICE 4471 TOTAL DUE 1,284.5O CAD BY 2026-11-3O",
    "skewed, low light": "INVOCE 447 TOTAL DUE 1.284,50 CAO BY 2026-1130",
}
for name, out in outputs.items():
    cer = edit_distance(out, truth) / len(truth)
    wer = edit_distance(out.split(), truth.split()) / len(truth.split())
print(f"{name:18s}: CER {cer:5.1%}, WER {wer:5.1%}")good scan : CER 0.0%, WER 0.0% blurry photo : CER 6.1%, WER 37.5% skewed, low light : CER 12.2%, WER 62.5%
A few confusions of the letter O with the digit zero give a character error rate of only 6%, but because they fall in three different words, the word error rate is 38%, and the total amount and due date are both wrong. For business documents, the errors that matter are in key fields, so evaluation should focus on field-level accuracy of amounts, dates and identifiers, with validation rules (checksums, totals that add up, valid dates) to catch errors automatically, as discussed for information extraction in AI-340, Lesson 11.
Document understanding
Documents carry meaning in their layout as well as their text: a number is a total because of its position next to the word "Total" at the bottom of a column; a table's cells are related by rows and columns; a form's fields are defined by boxes and labels. Document AI systems therefore combine text, position and appearance:
- Layout analysis segments pages into regions: titles, paragraphs, tables, figures, headers and footers, and determines reading order, which is essential for multi-column pages.
- Table recognition finds table structure (rows, columns, spanning cells) and extracts cell contents, still one of the hardest problems, especially for borderless and complex tables.
- Key information extraction identifies fields such as invoice number, vendor, dates and amounts. Layout-aware transformers (for example the LayoutLM family) take text tokens together with their bounding box coordinates and image features, so they learn that the word after "Invoice #" near the top right is the invoice number.
- OCR-free models read the document image directly and output structured text or JSON, and multimodal LLMs can now extract fields, summarize documents and answer questions about them from a prompt, without task-specific training.
Worked problem
Choosing a document pipeline
An insurer receives 40,000 claim forms a month, in about 25 standard layouts, plus free-form supporting letters. It needs 15 fields from each form, at 99% field accuracy for automated processing, with the rest reviewed by staff. Compare a fine-tuned layout model with prompting a multimodal LLM.
Show solution
- A layout-aware model fine-tuned on a few hundred labeled forms per layout is fast and cheap per page and very accurate on known layouts, but needs labeled data and retraining for new layouts.
- A multimodal LLM handles new layouts and free-form letters from a prompt and a JSON schema, but costs more per page, is slower, and may hallucinate plausible values not on the page.
- Both need validation rules (policy number formats, dates, totals) and confidence thresholds to route uncertain documents to staff, and field-level accuracy measured on a labeled sample each month.
Answer: A practical design uses the fine-tuned model for the standard forms, which are most of the volume, and a multimodal LLM for unusual layouts and letters, with validation and human review of low-confidence cases. Measuring field accuracy, not just OCR error rates, shows whether the 99% target is met.
Evaluating vision-language models
Vision-language models are evaluated on benchmarks for captioning (comparing generated captions with references, using metrics such as CIDEr), visual question answering, chart and document understanding, OCR, mathematical reasoning with diagrams, and multi-discipline exams with images. Because benchmark images and questions can leak into training data, and because models can exploit language priors (answering "yes" or "2" frequently because those are common answers) without looking carefully at the image, results should be interpreted with care and supplemented by evaluation on the target task.
A particular failure mode is object hallucination: describing objects, text or details that are not in the image, often because they commonly co-occur with what is present (a "keyboard" next to a computer monitor, a "fork" next to a plate). Benchmarks probe this by asking yes-or-no questions about absent objects. Other weaknesses include counting, precise spatial relations ("left of", "behind"), reading small or rotated text, fine-grained measurement, and reasoning over many images or long videos. In safety-critical uses, such as reading medical images, inspecting infrastructure or monitoring workplaces, outputs must be verified, and specialized models validated for the task usually remain necessary.
Applications and responsible use
Vision-language systems power image search, automatic alt text that makes images accessible to blind and low-vision users, visual assistants that describe surroundings, document automation in finance, insurance, government and health care, retail product recognition, robotics that follows instructions such as "pick up the blue mug", and analysis of screenshots and user interfaces for software agents. They also raise concerns: identifying people in images (face recognition, discussed in Lesson 5, is subject to strict privacy rules in Canada, as the federal Privacy Commissioner's 2021 findings against Clearview AI showed), inferring sensitive attributes, processing documents that contain personal information, and producing confident but wrong descriptions that users trust. Documents processed by cloud services may cross borders, which matters for Canadian public bodies and health custodians subject to data residency rules. Responsible deployment includes minimizing personal data, evaluating accuracy across user groups and document types, disclosing automated processing, and keeping humans in the loop for consequential decisions.
Common mistakes
MistakeAssuming an open-vocabulary detector matches a specialized detector on a critical class.
InsteadUse it to prototype and pre-label, then fine-tune and validate.
MistakeSending documents at low resolution to save tokens.
InsteadUse enough resolution or tiling for small text; balance cost against accuracy.
MistakeEvaluating OCR only by character error rate.
InsteadMeasure field-level accuracy on key fields with validation rules.
MistakeTrusting multimodal model descriptions without verification.
InsteadCheck for hallucinated objects, counts and text in important uses.
MistakeIgnoring privacy when processing images and documents.
InsteadMinimize personal data, respect residency rules and obtain consent where needed.
Summary and key terms
- Vision-language tasks include captioning, VQA, retrieval, grounding, open-vocabulary detection, OCR and multimodal chat.
- Open-vocabulary detectors compare region features with text embeddings to find any named class.
- Multimodal LLMs connect a vision encoder through a connector to a language model, trained in stages.
- Images become hundreds to thousands of visual tokens; resolution and tiling trade accuracy against cost.
- OCR detects and recognizes text; CER and WER measure it, but field-level accuracy matters for documents.
- Document AI combines text, layout and appearance; layout-aware models and multimodal LLMs extract fields.
- Benchmarks can mislead; hallucination, counting and spatial reasoning remain weaknesses; privacy needs care.
- Visual question answering
- Answering natural-language questions about images.
- Visual grounding
- Locating the image region referred to by a phrase.
- Open-vocabulary detection
- Detecting objects of any class named in text.
- Multimodal LLM
- A language model that accepts images and other modalities as input.
- Connector
- A module projecting vision features into a language model's embedding space.
- Visual token
- An embedding representing part of an image in a multimodal model's input.
- OCR
- Optical character recognition, converting images of text to characters.
- CTC
- Connectionist temporal classification, aligning predictions to sequences without positions.
- Character error rate
- Edit distance divided by the number of characters in the reference.
- Object hallucination
- Describing objects that are not present in an image.
Practice problems
Work each problem on paper first, then reveal the answer to check.
How does an open-vocabulary detector classify regions?
Show answer
By comparing region features with text embeddings of class names.
Name the three parts of a typical MLLM.
Show answer
Vision encoder, connector, language model.
Visual tokens for a 896 × 896 image with 14-pixel patches merged 2 × 2?
Show answer
\(32 \times 32 = 1{,}024\).
Why do models tile large images?
Show answer
To preserve fine detail such as small text.
What are the two stages of OCR?
Show answer
Text detection and text recognition.
CER for 3 errors in a 60-character reference?
Show answer
5%.
Why can CER be low while WER is high?
Show answer
A few character errors spread over many words make each word wrong.
What extra input do layout-aware models use?
Show answer
Bounding box positions of text, and image features.
What is object hallucination?
Show answer
Describing objects not present in the image.
Name one privacy concern with vision-language systems.
Show answer
Face identification, sensitive attributes, personal data in documents, cross-border processing.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.