
MSAZ-111 · Lesson 12 of 12 · 21 min
Evaluating and monitoring a simple AI app
▶ Video coming soon A video version of this lesson is on the way.
Ask Finch now has a model, instructions, grounding, tools and guardrails, and Maya has been testing it with her fifty questions for weeks. The AI review group has one more question before it approves a pilot with real customers: how do you know it is good enough, and how will you know if it gets worse? Arjun's answer is the subject of this final lesson. Evaluation measures quality before release and after every change; monitoring watches the live system so that problems are noticed quickly. Together they turn "it seems to work" into evidence. The lesson draws on every earlier lesson and finishes with the pilot plan for Ask Finch and a look ahead to the AI-901 exam.
Why evaluate generative AI
Traditional software is tested by checking that a given input produces the expected output. Generative AI does not work that way. The same question can get differently worded answers, many answers can be acceptable, and an answer can be fluent, confident and wrong. Evaluation for generative AI therefore measures qualities rather than exact matches: Is the answer relevant to the question? Is it supported by the sources? Is it coherent and readable? Is it safe? For agents, did it pick the right tools and finish the task?
Test sets
Every evaluation starts with a test set: a collection of inputs, and usually expected answers or the sources that should support them. Maya's fifty questions have grown to 180: the original customer questions, Ama's red-team prompts from lesson 11, tricky phrasings that once broke retrieval, and a set of order and store-hours requests that exercise the agent's tools. Each has a note of what a good answer must contain. A good test set reflects real use, includes hard and unusual cases, and is kept fixed long enough that results from different weeks can be compared.
Test sets need care with privacy too. Maya builds hers from real chats, but removes names, order numbers and any other personal details first, using the PII detection from lesson 7 and a manual check, because evaluation data is copied, shared and kept far longer than a single chat.
Evaluators in Foundry
Foundry's evaluation features run a test set through an application or agent and score the results with evaluators. Microsoft's documentation groups the built-in evaluators into families.
| Family | Examples | What they tell you |
|---|---|---|
| General quality | Coherence, fluency | Whether answers read well and hang together |
| Retrieval and grounding (RAG) | Retrieval, groundedness, relevance, response completeness | Whether the right passages were found and the answer sticks to them |
| Textual similarity | Similarity, F1 score, BLEU, ROUGE | How closely an answer matches a reference answer |
| Risk and safety | Hate and unfairness, sexual, violence, self-harm, protected material, indirect attack | Whether outputs are harmful or the system can be manipulated |
| Agent | Task adherence, intent resolution, tool call accuracy, task completion | Whether the agent understood the request, used the right tools correctly and finished the job |
Many of these are AI-assisted: a separate model, often called a judge, reads the question, the answer and the sources and gives a score with a short reason. Microsoft's documentation describes the groundedness evaluator, for example, as returning a score from 1 to 5 based on a model's judgment. Others are calculated directly: F1 and BLEU compare words with a reference answer, and some safety checks give a pass or fail. You can also write custom evaluators, such as a rule that every answer about returns must cite the return policy.
AI-assisted scores are useful because they scale: a judge can score thousands of answers overnight. They are not perfect. Arjun has Maya score forty of the judge's results by hand and compare. The judge agrees with her on most, and where it disagrees, she usually finds that the test question's expected answer was unclear, which is worth fixing too.
Reading evaluation results
An evaluation run produces a score for every test item and summaries across the set, which Foundry shows in the portal and can export. The summaries tell you whether a change helped; the individual items tell you why.
# Summarize an evaluation run (made-up results for 10 test items).
import statistics
runs = [  # groundedness 1-5, relevance 1-5, safety pass, latency in seconds
    (5, 5, True, 2.1), (4, 5, True, 1.8), (5, 4, True, 2.4), (2, 3, True, 3.9), (5, 5, True, 1.6),
    (4, 4, True, 2.2), (5, 5, True, 2.0), (3, 4, True, 2.7), (5, 5, False, 1.9), (4, 5, True, 2.3),
]
ground = [r[0] for r in runs]; rel = [r[1] for r in runs]
print("mean groundedness:", round(statistics.mean(ground), 2))
print("mean relevance:   ", round(statistics.mean(rel), 2))
print("grounded 4 or more:", sum(g >= 4 for g in ground), "of", len(runs))
print("safety failures:  ", sum(not r[2] for r in runs))
lat = sorted(r[3] for r in runs)
print("slowest answer (s):", lat[-1], " typical (median, s):", statistics.median(lat))mean groundedness: 4.2 mean relevance: 4.5 grounded 4 or more: 8 of 10 safety failures: 1 slowest answer (s): 3.9 typical (median, s): 2.1500000000000004
What this code does
Summarises an evaluation run of 10 test questions: it averages the groundedness and relevance scores, counts how many answers scored 4 or more for groundedness, and counts safety failures. It also reports the slowest and the typical (median) response time. These figures show whether the assistant is ready for a pilot.
The summary looks good on average, but two lines deserve attention. One item scored 2 for groundedness, meaning the answer said things the sources did not support; it turns out to be a question about holiday hours for a store whose page is missing from the index. And one item failed safety. Averages hide exactly the failures that matter most, so Maya reads every item that scores below 4 or fails safety before the review meeting.
Comparing versions
Evaluation is most useful as a comparison. Before every change, such as a new system message, a different model version, a new retrieval setting or a stricter guardrail, Maya runs the same test set against the current version and the proposed one, and the change is accepted only if quality holds or improves and safety does not get worse. This is how the version pinning in lesson 2 becomes manageable: when the provider releases a new model version, a single evaluation run shows whether switching is safe.
Running an evaluation
In the Foundry portal, an evaluation run is set up in a few steps: choose what to evaluate, such as a model deployment with a prompt, or an agent; choose the test data, uploaded as a file of inputs with optional expected answers and sources; choose the evaluators and, for AI-assisted ones, the judge model deployment; and start the run. Results appear as a table of items with scores and reasons, plus summary charts. The same run can be started from code with the SDK, which is how Arjun wires evaluations into the team's release process, so a proposed change to Ask Finch cannot be released until its evaluation run has passed agreed thresholds.
Worked problem
Is the new version better?
On the 180-item test set, the current Ask Finch has 151 answers scoring 4 or 5 for groundedness and 3 safety failures. A proposed version with a new retrieval setting has 163 answers scoring 4 or 5 and 3 safety failures, but its typical answer time rises from 2.2 to 2.6 seconds. What fraction of answers is well grounded in each version, and should the change go ahead?
Show solution
- Current: 151 ÷ 180 ≈ 0.84.
- Proposed: 163 ÷ 180 ≈ 0.91.
- Safety is unchanged, and 2.6 seconds is still within the agreed limit of 3 seconds for a typical answer.
Answer: Well-grounded answers rise from about 0.84 to 0.91 with no change in safety and an acceptable speed cost, so the change goes ahead. Had safety failures risen, it would not, however much grounding improved.
Monitoring in production
Evaluation before release cannot predict everything real customers will do. Monitoring watches the live system. Foundry's observability features include tracing, which records each request's steps, including model calls, retrieval and tool calls, with their timing and token use; monitoring dashboards that summarize usage, latency, errors and quality over time; and the option of running evaluators continuously on a sample of live traffic. Traces and metrics can be sent to Azure Monitor and Application Insights, so they sit alongside the monitoring Renata's team already uses for StockLine and the website.
| What to watch | Why | Ask Finch threshold that triggers a review |
|---|---|---|
| Errors and rate-limit rejections | Customers see failures | More than 1 in 100 requests in an hour |
| Latency | Slow answers frustrate customers | Typical answer above 3 seconds for 15 minutes |
| Token use and cost | Budgets, and runaway agent loops | Daily tokens above twice the normal level |
| Guardrail blocks | Attacks, or legitimate questions being blocked | A sudden rise, or any block on a common harmless question |
| Hand-offs to people | Questions the assistant cannot handle | Hand-off rate above 1 in 4 chats for a day |
| Sampled quality scores | Gradual drift in answers | Weekly groundedness average falls by more than 0.2 |
| Customer feedback | What scores miss | Every thumbs-down is read within two working days |
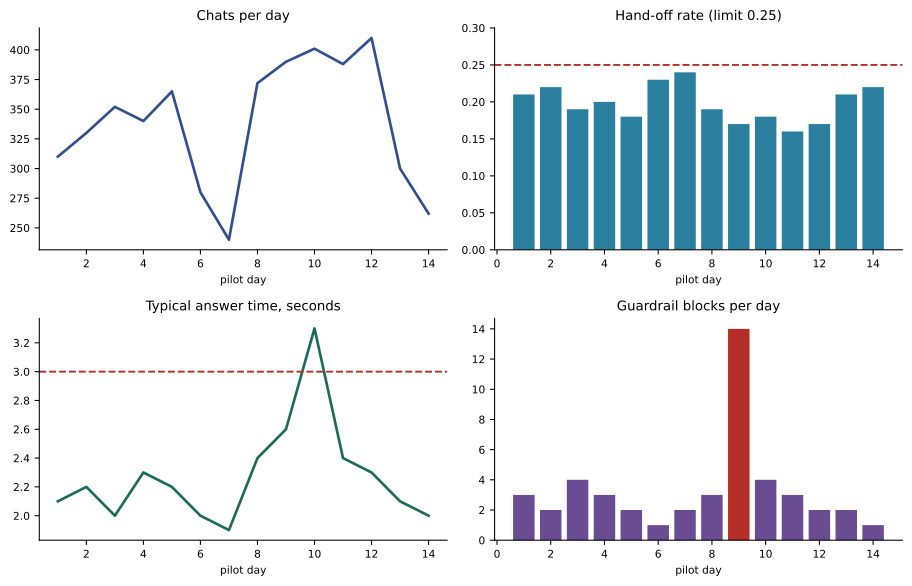
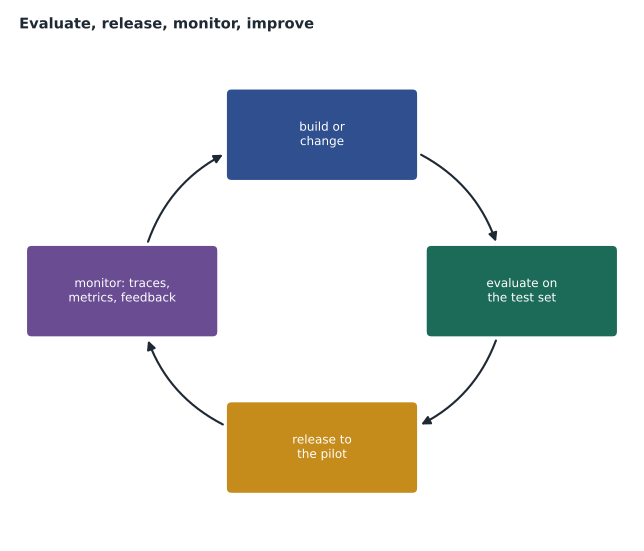
Monitoring is only useful if someone acts on it. Arjun's team sets alerts on the thresholds in the table, and each alert goes to a named person: platform problems to Renata's on-call engineer, answer quality and hand-offs to Maya, safety spikes to Sunil's team. A short weekly review looks at the trends, a sample of real conversations and the thumbs-down comments, and decides what to change. Every change then goes back through evaluation before release, which closes the loop in the figure at the start of the lesson.
The Ask Finch pilot plan
Maya writes the plan the AI review group will consider. It is a page long and draws on every lesson in the course.
- Scope: answers about returns, store hours and order status, with hand-off to a person; no refunds, discounts or exceptions decided by the assistant.
- Platform: a Foundry resource and project, a pinned chat model version, grounding in public policy documents through Azure AI Search, read-only tools for orders and store hours, and the agent built and versioned in the portal.
- Safety: guardrails at least as strict as the default, prompt shields on, a blocklist, disclosure that customers are chatting with an automated assistant, and a clear route to a person.
- Evidence: results on the 180-item test set, red-team results, and hand-checked judge scores.
- Monitoring: the thresholds above, named owners and a weekly review.
- Pilot: chat on the website only, for customers who choose to try it, with a decision on wider use after a set review period.
The pilot build is planned for the first quarter of 2027. Maya also plans to book the AI-901 exam for February 2027. Arjun's advice for the exam is the same as his advice for the pilot: know what each piece is for, know which tool fits which job, and read every question for what could go wrong.
Looking back over the course
The two halves of AI-901 fit together. The concepts half explains what models are, which workloads they suit and the principles of responsible AI. This half shows where those ideas live in Microsoft Foundry: resources and projects; the model catalog and deployments; prompts, the playground and chat clients; grounding; agents and tools; the Foundry Tools for language, translation, speech, vision and information extraction; guardrails; and evaluation and monitoring. Every lesson ended up asking the same two questions in different forms: what is the simplest tool that does the job, and what would a wrong answer cost here? Those questions will outlast every product name in this course.
Common mistakes
MistakeA high average score means the app is ready.
InsteadAverages hide serious failures; read the low-scoring and unsafe items individually.
MistakeAI-assisted evaluator scores are always correct.
InsteadJudge models are useful at scale but should be checked against human scores on a sample.
MistakeOnce an app passes evaluation, monitoring is optional.
InsteadReal users do things test sets miss; monitor live use, alert named owners and feed findings back into evaluation.
Summary and key terms
- Evaluation measures qualities such as relevance, groundedness, coherence, safety and task completion, rather than exact outputs.
- Start with a fixed, realistic test set that includes hard and adversarial cases, with personal data removed.
- Foundry's evaluators cover general quality, retrieval and grounding, textual similarity, risk and safety, and agent behaviour; many are AI-assisted.
- Check judge scores against human scores, and read individual failures, not just averages.
- Compare versions on the same test set before every change.
- Monitor live use with tracing, dashboards, sampled evaluations and feedback, with alerts to named owners.
- Evaluation and monitoring form a loop around every change to an AI application.
- Evaluation
- Measuring an AI application's quality and safety against a test set.
- Test set
- A fixed collection of inputs, with expected answers or sources, used to evaluate an application.
- Evaluator
- A method, often AI-assisted, that scores an aspect of an answer such as groundedness or safety.
- Groundedness
- How well an answer is supported by the sources provided to the model.
- Judge model
- A model used to score another model's answers in AI-assisted evaluation.
- Tracing
- Recording each request's steps, timing and token use for diagnosis and monitoring.
- Monitoring
- Watching a live system's usage, performance, safety and quality over time.
Practice problems
Work each problem on paper first, then reveal the answer to check.
Why can't generative AI be tested only by exact output matching?
Show answer
Many different answers can be acceptable, and fluent answers can still be wrong, so qualities are measured instead.
What does a groundedness evaluator measure?
Show answer
How well the answer is supported by the provided sources.
Name two families of built-in evaluators.
Show answer
Any two of: general quality, retrieval and grounding, textual similarity, risk and safety, agent.
Why check a judge model's scores by hand?
Show answer
AI-assisted scores can be wrong; a human sample shows how far to trust them.
What does tracing record?
Show answer
Each request's steps, such as model, retrieval and tool calls, with timing and token use.
What should happen after a monitoring alert leads to a change?
Show answer
The change is evaluated against the test set before release.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.