
JS-250 · Lesson 11 of 12 · 26 min
Performance budgets and monitoring
▶ Video coming soon A video version of this lesson is on the way.
On Tuesday, September 26, Gareth tells Mira a story from an earlier client. The studio once spent a month making a shop's site fast, celebrated, and moved on. Eight months later the site was slower than before the work started. Nobody had done anything wrong: a marketing script here, a bigger photo there, a new font for a campaign, each change reasonable on its own. Performance is not something a site has; it is something a site keeps. Today's lesson is about the two tools that keep it: budgets, which stop the site getting slower in the first place, and monitoring, which shows what real visitors experience and notices when it changes.
Performance budgets
A performance budget is a limit the team agrees not to exceed, checked automatically on every change. Budgets come in three kinds, and the studio uses all three because each catches different problems.
| Kind | Example for the Food Hub | Checked by |
|---|---|---|
| Quantity | Home page: at most 400 kB in total and 100 kB of JavaScript after compression | The build, counting files |
| Timing (lab) | Phone profile: LCP at most 2.5 s, Total Blocking Time at most 200 ms | The scripted Playwright test in CI |
| Timing (field) | Home page on phones: LCP, INP and CLS good at the 75th percentile | The studio's own field data, weekly |
| Rule-based | Lighthouse performance score of at least 90 on the phone profile | A Lighthouse run in CI, as a smoke alarm |
Quantity budgets are the easiest to enforce, because they are measured in the build without a browser and never vary between runs. They are also the closest to the cause: if the JavaScript budget fails, the change that broke it is in the pull request that failed. Timing budgets are closer to what visitors feel but noisier, so the studio checks them with a margin and with the median of several runs. Field budgets are the truth but arrive days later. The portal already had one budget from JS-220: 120 kB of gzip JavaScript for its first screen.
Mira writes the quantity check as a small function first, against a build manifest listing every output file with its type and compressed size.
// Check a build's compressed sizes against per-type budgets (kB after gzip).
const budgets = { js: 100, css: 30, font: 60, image: 220, total: 400 };

const build = [
  { file: 'index.html', type: 'html', kb: 6 },
  { file: 'css/site-9c0e11.css', type: 'css', kb: 13 },
  { file: 'js/home-91be07.js', type: 'js', kb: 38 },
  { file: 'js/calendar-2d4410.js', type: 'js', kb: 71 },
  { file: 'fonts/merriweather-latin-700.woff2', type: 'font', kb: 24 },
  { file: 'fonts/opensans-var-latin.woff2', type: 'font', kb: 47 },
  { file: 'photos/hamper-800.avif', type: 'image', kb: 52 },
  { file: 'img/logo.svg', type: 'image', kb: 3 },
];

function checkBudgets(files, limits) {
  const totals = { total: 0 };
  for (const f of files) {
    totals[f.type] = (totals[f.type] ?? 0) + f.kb;
    totals.total += f.kb;
  }
  return Object.entries(limits).map(([type, limit]) => {
    const used = totals[type] ?? 0;
    return `${used <= limit ? 'pass' : 'FAIL'}  ${type.padEnd(6)} ${String(used).padStart(4)} kB of ${limit} kB`;
  });
}

console.log(checkBudgets(build, budgets).join('\n'));FAIL js 109 kB of 100 kB pass css 13 kB of 30 kB FAIL font 71 kB of 60 kB pass image 55 kB of 220 kB pass total 254 kB of 400 kB
What this code does
The function adds up the compressed size of each type of file and the total, then compares each with its limit and reports pass or FAIL for every budget, so one run shows everything that is over. The calendar script has crept back up to 71 kB and pushes JavaScript over its 100 kB budget, while the page as a whole is still comfortably under 400 kB. A failure like this blocks the pull request until someone either trims the script or makes a deliberate decision to change the budget.
Fonts also fail, at 71 kB against 60 kB, because the variable Open Sans file includes every weight from light to extra bold. Sana decides that the site only needs regular and bold, and the build now produces a variable font limited to that range, which brings fonts back under budget. That conversation, a designer and a developer agreeing what the site needs, is the real value of a budget: it turns 'the site feels slower' into a specific decision about a specific file.
Budgets in continuous integration
In JS-210 the studio set up GitHub Actions to run tests on every pull request. The budget check becomes another step in that workflow. The script below is what runs: it measures the compressed size of every file the build produced and exits with a failure code when a budget is exceeded, which marks the pull request's check as failed. Gareth runs it on the cut-down portal from lesson 5 with deliberately tight limits to show both outcomes.
$ node check-budget.mjs; echo "exit code $?"
pass  first screen 385 B gzip (budget 400 B)
FAIL  total        1092 B gzip (budget 1000 B)
exit code 1
What this code does
The script walks the dist folder, compresses each file with gzip to measure it as it will travel, and adds up the files the first screen needs and the whole build. The first screen is within its budget, but the build as a whole is 92 bytes over, so the script prints FAIL and sets the exit code to 1. In GitHub Actions a non-zero exit code fails the step and shows a red cross on the pull request.
# .github/workflows/performance.yml (part of the studio's CI from JS-210)
name: performance
on: pull_request
jobs:
  budgets:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v5
      - uses: actions/setup-node@v5
        with: { node-version: 24 }
      - run: npm ci
      - run: npm run build
      - run: node scripts/check-budget.mjs          # quantity budgets
      - run: npx playwright install --with-deps chromium
      - run: node scripts/measure-lab.mjs --runs 5   # LCP and TBT on the phone profile
What this code does
The workflow runs on every pull request, builds the site and runs the quantity check, which is fast and exact. It then installs Chromium and runs the lab measurement script from lesson 2 five times on the phone profile, failing if the median LCP or Total Blocking Time is over budget. Any failed step blocks the merge until it is fixed or the budget is deliberately changed.
Real user monitoring
Budgets protect against regressions the team can measure in the lab. Real user monitoring (RUM) measures what actually happens on visitors' devices. In lesson 3 Mira added the web-vitals library to the site, sending each page view's LCP, INP and CLS to an endpoint with navigator.sendBeacon(). Theo adds the endpoint to his server: it accepts the small JSON reports, drops anything malformed, and writes one row per metric to a table that a nightly job turns into percentiles.
Gareth insists on privacy rules before a single report is stored, because performance data does not need to know who anyone is. The reports contain the page path without its query string, the metric, its value and rating, a rough device class (phone or desktop, from the screen width) and the connection type where the browser reports it. They do not contain IP addresses, which the endpoint discards, or user agent strings, cookies, names or volunteer ids. Reports are kept for 90 days and only the aggregates after that. Lucy's privacy notice for the site already covers anonymous usage measurements, and Mira adds a sentence about performance measurement to it.
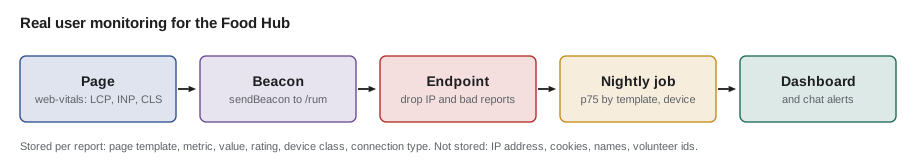
The nightly job does the same work as the code below: group the reports by page and device, take the 75th percentile of each metric and rate it.
// Aggregate RUM beacons: the 75th percentile per page, device and metric.
const beacons = [
  ['/', 'phone', 'LCP', 2300], ['/', 'phone', 'LCP', 1900], ['/', 'phone', 'LCP', 3100], ['/', 'phone', 'LCP', 2200],
  ['/', 'desktop', 'LCP', 1200], ['/', 'desktop', 'LCP', 1400],
  ['/', 'phone', 'INP', 120], ['/', 'phone', 'INP', 96], ['/', 'phone', 'INP', 240], ['/', 'phone', 'INP', 150],
  ['/', 'phone', 'CLS', 0.02], ['/', 'phone', 'CLS', 0.05], ['/', 'phone', 'CLS', 0.12], ['/', 'phone', 'CLS', 0.01],
  ['/recipes/lentil-soup', 'phone', 'LCP', 2600], ['/recipes/lentil-soup', 'phone', 'LCP', 2900], ['/recipes/lentil-soup', 'phone', 'LCP', 2100],
];
const GOOD = { LCP: 2500, INP: 200, CLS: 0.1 }, POOR = { LCP: 4000, INP: 500, CLS: 0.25 };

function p75(values) {
  const s = [...values].sort((a, b) => a - b);
  return s[Math.ceil(0.75 * s.length) - 1];
}

const groups = new Map();
for (const [page, device, metric, value] of beacons) {
  const key = `${page} | ${device} | ${metric}`;
  groups.set(key, [...(groups.get(key) ?? []), value]);
}
for (const [key, values] of groups) {
  const metric = key.split(' | ')[2];
  const v = p75(values);
  const rating = v <= GOOD[metric] ? 'good' : v <= POOR[metric] ? 'needs improvement' : 'poor';
  console.log(`${key.padEnd(34)} n=${values.length}  p75 ${String(v).padStart(5)}  ${rating}`);
}/ | phone | LCP n=4 p75 2300 good / | desktop | LCP n=2 p75 1400 good / | phone | INP n=4 p75 150 good / | phone | CLS n=4 p75 0.05 good /recipes/lentil-soup | phone | LCP n=3 p75 2900 needs improvement
What this code does
Each beacon is filed under a key made of its page, device class and metric, so a Map collects the values for every combination. The 75th percentile of each group is rated with the same thresholds as the Core Web Vitals assessment, separately for phones and desktops as Google does. In real data the groups have hundreds of values; groups with very few, like the recipe page here, are shown but not trusted until they grow.
Low traffic is a real limit for the Food Hub. The home page gets a few thousand page views a week, enough for stable percentiles, but a single recipe page may get thirty. The dashboard therefore shows recipe pages as one group, using the page template rather than the path as the key, and marks any group with fewer than 100 reports in the period as too small to judge. The studio does not sample the home page either: with so few visits, every report counts.
- Group by template, not only by URL. All recipe pages share the same template and the same problems, so grouping them gives enough data to see trends.
- Report the number of samples. A 75th percentile from twelve visits can swing wildly from week to week.
- Separate phones and desktops. Their numbers are so different that a combined percentile describes neither.
- Keep attribution. The web-vitals attribution build adds which element was the LCP element and which interaction was slowest, which turns a bad number into a place to look.
Noticing regressions
Monitoring is only useful if someone notices when the numbers change. Nobody at the studio wants to read a dashboard every morning, so the nightly job compares each group's 75th percentile for the last seven days with the seven days before and sends a message to the studio's chat channel when something gets meaningfully worse. Meaningfully matters: small groups bounce around naturally, so the job ignores changes smaller than a tolerance and groups with too few reports.
// Compare this week's p75 with last week's and flag real regressions.
const weeks = [
  // [group, metric, last week p75, this week p75, reports this week]
  ['home | phone', 'LCP', 2200, 2350, 2140],
  ['home | phone', 'INP', 150, 230, 1870],
  ['home | phone', 'CLS', 0.04, 0.05, 2110],
  ['recipe | phone', 'LCP', 2600, 3900, 64],
  ['portal shifts | phone', 'INP', 110, 180, 1320],
];
const TOLERANCE = { LCP: 0.1, INP: 0.15, CLS: 0.3 };    // allowed relative change
const MIN_REPORTS = 100;
const GOOD = { LCP: 2500, INP: 200, CLS: 0.1 };

for (const [group, metric, before, after, n] of weeks) {
  const change = (after - before) / before;
  let verdict;
  if (n < MIN_REPORTS) verdict = `too few reports (${n}) to judge`;
  else if (change > TOLERANCE[metric] && after > GOOD[metric]) verdict = 'REGRESSION, now over the good threshold';
  else if (change > TOLERANCE[metric]) verdict = 'worse, still good: watch';
  else verdict = 'steady';
  console.log(`${group.padEnd(22)} ${metric}  ${String(before).padStart(5)} -> ${String(after).padStart(5)}  (${change >= 0 ? '+' : ''}${(change * 100).toFixed(0)} in 100)  ${verdict}`);
}home | phone LCP 2200 -> 2350 (+7 in 100) steady home | phone INP 150 -> 230 (+53 in 100) REGRESSION, now over the good threshold home | phone CLS 0.04 -> 0.05 (+25 in 100) steady recipe | phone LCP 2600 -> 3900 (+50 in 100) too few reports (64) to judge portal shifts | phone INP 110 -> 180 (+64 in 100) worse, still good: watch
What this code does
The relative change is the difference divided by last week's value, and each metric has its own tolerance because some are noisier than others. Groups with fewer than 100 reports are not judged at all, which is why the recipe page's large jump is reported but not flagged. The home page's INP is the real alert: it rose by more than half and crossed the 200 ms good threshold, so the message goes to the chat channel with a link to the attribution data.
The INP alert in that example is not invented for the lesson. During the course, Dev added an embedded feed of the Food Hub's social media posts to the home page, and its script runs a long task whenever the page is tapped. The attribution data pointed at a tap on the menu button with a long input delay, the Performance panel showed the feed script's task, and the fix was a facade like the donation widget's from lesson 5: a still preview of the latest posts that loads the real feed only when tapped.
Sampling when traffic is high
The Food Hub's traffic is small enough to keep every report. Bigger sites often keep only a sample, for example one page view in ten, to save storage and processing. The decision must be made per page view, not per report, so that the LCP, INP and CLS of one visit are kept or dropped together, and it should not depend on anything that varies with performance, or the sample would be biased. A common technique is to hash the page view's random id and keep it if the hash falls in a range.
// Keep about 1 page view in 4, deciding from a hash of the page view id so all its metrics agree.
function fnv1a(text) {
  let h = 0x811c9dc5;
  for (const ch of text) { h ^= ch.charCodeAt(0); h = Math.imul(h, 0x01000193) >>> 0; }
  return h;
}
const keep = (pageViewId, rate) => fnv1a(pageViewId) / 2 ** 32 < rate;

const ids = Array.from({ length: 2000 }, (_, i) => `v5-${1717000000000 + i * 7919}-${i}`);
const kept = ids.filter((id) => keep(id, 0.25)).length;
console.log(`kept ${kept} of ${ids.length} page views (target 500)`);
console.log('same answer every time for one id:', keep(ids[42], 0.25), keep(ids[42], 0.25));kept 503 of 2000 page views (target 500) same answer every time for one id: false false
What this code does
fnv1a() is a small, fast hash that turns any string into a 32-bit number, and dividing by 2 to the power 32 gives a value between 0 and 1 that is effectively random for different ids but fixed for any one id. A page view is kept if that value is under the sampling rate, so its three metrics are always kept or dropped together. About a quarter of the 2,000 ids are kept, close to the target of 500.
Mira's dashboard
The last task of the session is a page on the studio's internal dashboard that Lucy, Dev and Paul can read without help. Gareth's advice is to show few numbers, in plain words, with the trend. The page shows, for the home page, recipe pages, the Donate page and the portal, whether each Core Web Vital is good on phones this week, the trend over twelve weeks as a small line, the number of visits behind each number, and the budgets' status from the last build. Nothing on it needs a performance engineer to interpret.
Worked problem
A budget for the hamper drive appeal
Dev wants to add a 40-second appeal video to the home page in November. The home page now has a 400 kB total budget and currently uses 230 kB. The video host's player costs 520 kB of JavaScript and the video's poster image 60 kB. With a facade that shows only the poster until it is tapped, how much does the home page cost on load, and is it within budget? Without the facade?
Show solution
- With the facade, only the poster loads at first: 230 + 60 = 290 kB.
- 290 kB is within the 400 kB budget, leaving 110 kB.
- Without the facade, the player loads too: 230 + 60 + 520 = 810 kB.
- 810 kB is more than twice the budget, and the player's script would also count against the 100 kB JavaScript budget.
Answer: With the facade the page costs 290 kB on load and stays within budget; without it, 810 kB, which the build would reject.
Common mistakes
MistakeSetting budgets once and never checking them.
InsteadCheck every budget automatically in CI on every pull request.
MistakeUsing only a Lighthouse score as a budget.
InsteadCombine quantity, lab timing and field budgets; use the score only as a smoke alarm.
MistakeStoring personal data with performance reports.
InsteadKeep only what the analysis needs: page template, metric, value, device class; drop IP addresses.
MistakeJudging groups with very few reports.
InsteadShow the number of samples and set a minimum before alerting.
MistakeSampling individual metric reports.
InsteadSample whole page views with a stable hash so a visit's metrics stay together.
Summary and key terms
- Performance must be kept, not just achieved.
- Budgets set limits on quantities (bytes, requests), lab timings (LCP, Total Blocking Time) and field timings (Core Web Vitals at the 75th percentile), plus rule-based checks such as a Lighthouse score.
- Quantity budgets are exact and checked in the build; timing budgets need medians and margins.
- A CI step that exits with a failure code blocks a pull request that breaks a budget.
- Real user monitoring collects the Core Web Vitals from real visits with web-vitals and sendBeacon, without personal data, and aggregates them into 75th percentiles per page or template and device class.
- Regression alerts compare periods with tolerances and minimum sample sizes, and attribution data points to the cause.
- High-traffic sites sample whole page views with a stable hash.
- Performance budget
- An agreed limit on a measure of performance, checked automatically, such as bytes of JavaScript or LCP.
- Quantity budget
- A budget on countable things such as file sizes or numbers of requests.
- Real user monitoring (RUM)
- Collecting performance measurements from real visitors' browsers.
- Beacon
- A small report sent from a page to a server, often with navigator.sendBeacon().
- Attribution
- Extra data saying what caused a metric's value, such as the LCP element or the slowest interaction.
- Regression
- A change that makes performance worse than it was.
- Sampling
- Keeping only a share of measurements, chosen so that the sample still represents the whole.
Practice problems
Work each problem on paper first, then reveal the answer to check.
Why are quantity budgets checked in the build rather than in a browser?
Show answer
They are exact, never vary between runs and point directly at the change that broke them.
Why does the RUM endpoint discard IP addresses?
Show answer
Performance analysis does not need to know who anyone is, so the studio keeps only what it needs and protects visitors' privacy.
Why are recipe pages grouped by template on the dashboard?
Show answer
Each recipe page gets too few visits for stable percentiles, but they share one template and its problems.
Why must sampling decide per page view?
Show answer
So that a visit's LCP, INP and CLS are kept or dropped together and the sample is not biased.
Try it yourself
Over budget
Complete overBudget(files, limits) where each file is { type, kb } and limits maps types to kilobytes. Return the names of the types whose total size is over their limit, in the order they appear in limits, each followed by how many kB over it is, such as 'js +9'.
Return an empty array when everything is within budget.
function overBudget(files, limits) {
  return [];
}

const files = [{ type: 'js', kb: 71 }, { type: 'js', kb: 38 }, { type: 'css', kb: 13 }, { type: 'font', kb: 71 }, { type: 'image', kb: 55 }];
console.log(JSON.stringify(overBudget(files, { js: 100, css: 30, font: 60, image: 220 })));
console.log(JSON.stringify(overBudget(files, { js: 120, font: 80 })));
Try it yourself
75th percentile by group
Complete p75ByGroup(reports) where each report is [group, value]. Return an object mapping each group to the 75th percentile of its values, using the nearest-rank method (sort ascending, take index Math.ceil(0.75 * n) - 1).
Keep the groups in the order they first appear.
function p75ByGroup(reports) {
  return {};
}

const reports = [['home', 2300], ['recipe', 2600], ['home', 1900], ['home', 3100], ['recipe', 2900], ['home', 2200], ['donate', 1700]];
console.log(JSON.stringify(p75ByGroup(reports)));
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.