
GCP-112 · Lesson 3 of 12 · 17 min
Techniques that improve model output
▶ Video coming soon A video version of this lesson is on the way.
The first test drafts for the product description pilot are disappointing in an instructive way. Jules pastes a supplier spec sheet for a new rain shell into a general chat model and asks for a description. The result reads well, but it calls the jacket "fully waterproof with taped seams" when the spec sheet says water-resistant with a durable water repellent finish, and it mentions a lifetime warranty that Birchline does not offer. The model filled gaps with likely-sounding details. "That is not the model being broken," Farah says. "That is the model doing what it was built to do, which is produce plausible text. Our job is to give it what it needs to produce accurate text, and to check it." This lesson covers the techniques leaders need to understand, so they can ask the right questions of technical teams.
Why model output goes wrong
Generative models learn patterns from very large amounts of data and then predict likely continuations. That gives them broad knowledge and fluent language, but also built-in limitations that every leader should be able to name.
| Limitation | What it looks like | Birchline example |
|---|---|---|
| Hallucination | Confident, plausible statements that are false | The invented lifetime warranty |
| Knowledge cutoff | No knowledge of events or facts after training | Not knowing this autumn's new product line or a policy changed last month |
| Data dependency | Output only as good as the data it learned from or is given | Outdated supplier specs produce outdated descriptions |
| Bias | Patterns from training data that treat groups unfairly or stereotype | Describing hiking gear only with images or language of one kind of customer |
| Edge cases | Poor results on unusual inputs the model rarely saw | A product with an unusual sizing system, such as children's ski boots |
| Inconsistency | Different answers to the same question on different runs | Two drafts for the same product disagree on the fabric weight |
None of these disappears completely. The techniques below reduce them, and the human review in lesson 4 catches what remains. A useful way to think about the techniques is as a ladder from cheapest and fastest to most involved.
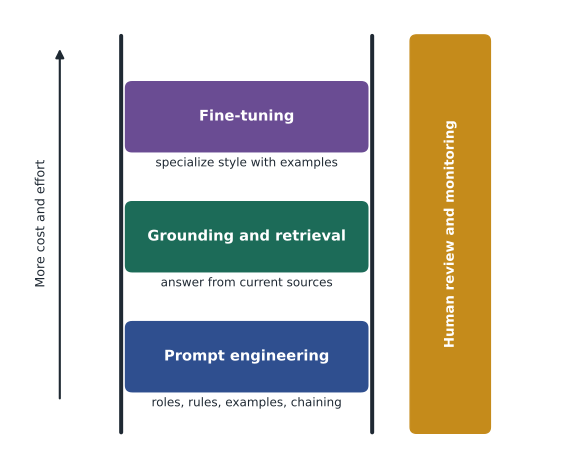
Rung one: prompt engineering
Prompt engineering is designing the instructions and context given to a model so that it produces the intended output. It costs nothing but thought, can be changed in minutes, and often produces the largest single improvement. Leaders do not need to write prompts themselves, but they should recognize the main techniques by name.
- Zero-shot prompting gives an instruction with no examples: "Write a product description for this jacket."
- One-shot and few-shot prompting include one or several examples of good output, so the model can copy the format, length and tone. Birchline adds three approved past descriptions to every prompt.
- Role prompting tells the model who it is acting as: "You are a copywriter for an outdoor retailer whose tone is practical and friendly."
- Prompt chaining splits a task into steps, with the output of one step feeding the next: first extract the facts from the spec sheet, then write the description from only those facts, then check the description against the facts.
- Chain-of-thought prompting asks the model to work through intermediate reasoning before answering, which tends to help on multi-step problems.
- ReAct (reason and act) combines reasoning with actions such as looking something up or calling a tool, then reasoning about the result. It underlies many agents.
The improved Birchline prompt uses several of these together. It sets the role, states the constraint "use only the facts provided; if a fact is missing, write MISSING rather than guessing", gives three examples, and chains extraction before writing. The invented warranty disappears, because the prompt removes the model's room to fill gaps, and because the extraction step produces a list of facts that the editor can check quickly.
| Prompt element | Example wording in Birchline's prompt |
|---|---|
| Role | You write product descriptions for Birchline Outfitters. Tone: practical, friendly, no exaggeration. |
| Task | Write a 120 to 160 word description and a five-item feature list. |
| Constraints | Use only the facts provided. Never mention warranties or certifications unless listed. Write MISSING for absent facts. |
| Context | The extracted product facts and the brand style rules. |
| Examples | Three approved descriptions for similar products. |
| Output format | Headline, description paragraph, bullet list, then a list of every factual claim made. |
Sampling settings
Alongside the prompt, most models accept settings that change how they choose words. Leaders meet these in product consoles and vendor discussions, so knowing what each does is useful.
| Setting | What it controls | Typical use |
|---|---|---|
| Temperature | How random word choices are; low values are more predictable | Low for factual or consistent output; higher for brainstorming |
| Top-p | Limits choices to the most likely words whose probabilities add up to p | Another way to narrow or widen variety |
| Maximum output length | The longest response allowed, in tokens | Controls cost and keeps answers concise |
| Safety settings | Thresholds for blocking harmful categories of content | Stricter for customer-facing uses |
| Stop sequences | Text that ends the response when produced | Keeps output to the required format |
For product descriptions, Birchline uses a low temperature so that two runs produce similar facts, and a maximum length that fits the 160-word limit with a little room. For the marketing team's slogan brainstorming, a higher temperature is fine, because variety is the point and a person picks the best idea.
Rung two: grounding and retrieval-augmented generation
Grounding means connecting a model's output to verifiable sources of information, so that it answers from facts rather than from memory alone. Grounding can use first-party data, which is the organization's own information such as Birchline's catalogue and policies; third-party data licensed from others, such as a supplier's specification database; or world data, such as current results from web search.
The most common grounding approach is retrieval-augmented generation (RAG). When a question arrives, a retrieval step searches a collection of documents for the passages most relevant to it. Those passages are added to the prompt, and the model is instructed to answer from them and to cite them. Because the documents can be updated at any time, RAG also works around the knowledge cutoff: the store policy assistant can answer about last month's policy change as soon as the new policy is in the collection.
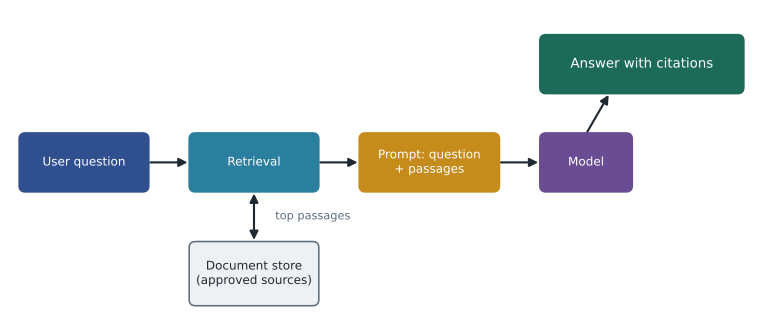
Google Cloud offers grounding at several levels, which GCP-111 describes in more detail: prebuilt retrieval through its enterprise search offering, RAG building blocks for developers on its AI platform, and grounding with Google Search for current public information. The leadership point is simpler. Grounding is usually the right answer when the problem is "the model does not know our facts" or "the model's facts are out of date", and it has a quality requirement of its own: the documents must be accurate, current and properly permissioned, which is lesson 5's subject.
Grounding also makes review faster. When the policy assistant cites the paragraph its answer came from, a store manager can check it in seconds. Birchline makes citation a requirement for every discovery use case.
# A toy retrieval step: score each policy passage by shared words with the question.
passages = {
    "returns-1": "Unworn items can be returned within 60 days with a receipt.",
    "returns-2": "Worn footwear can be returned within 30 days if faulty.",
    "giftcards": "Gift cards cannot be exchanged for cash except where law requires.",
    "pricing":   "Price adjustments are given within 14 days of purchase.",
}
question = "Can a customer return worn boots that are faulty?"
q = set(question.lower().replace("?", "").split())
def overlap(text):
    return len(q & set(text.lower().replace(".", "").split()))
ranked = sorted(passages.items(), key=lambda kv: -overlap(kv[1]))
for pid, text in ranked[:2]:
print(pid, overlap(text), "|", text)returns-2 3 | Worn footwear can be returned within 30 days if faulty. returns-1 2 | Unworn items can be returned within 60 days with a receipt.
What this code does
Each policy passage is scored by how many words it shares with the question about returning worn, faulty boots. The passages are sorted by score and the top two are shown. The passage about returning worn footwear that is faulty scores highest (3), so it is the one that should ground the answer.
Real systems use far better retrieval than counting shared words, typically embeddings, numeric representations of meaning that let the system find passages about "faulty footwear" even when the question says "broken boots". The idea is the same: find the best evidence first, then ask the model to answer from it.
Rung three: fine-tuning
Fine-tuning continues training an existing model on a set of examples so that it learns a specialized style, format or task. Where prompting tells a model what to do each time, fine-tuning changes the model's tendencies. It can help when the organization has many good examples of a consistent task, when prompts have become very long, or when a smaller tuned model can match a larger general one at lower cost. Related lighter-weight methods, sometimes called parameter-efficient tuning, adjust only a small part of the model and need fewer resources.
Fine-tuning has costs leaders should weigh. It needs a large, clean, representative set of examples, often hundreds or thousands. It takes time and expertise to evaluate. It must be repeated when the base model is upgraded. And it is the wrong tool for teaching a model facts that change: a model tuned on this year's product line will be wrong next year, while a grounded model simply retrieves the new catalogue. Farah's summary for Jules is a rule of thumb: ground for knowledge, tune for behaviour, and try prompting first for both.
| Problem | Usually try first | Why |
|---|---|---|
| Output in the wrong format or tone | Prompting with examples | Fast and cheap; often enough |
| Model does not know our facts | Grounding (RAG) | Facts stay current and can be cited |
| Facts change often | Grounding | Update the documents, not the model |
| A consistent specialized style across thousands of items, prompts too long | Fine-tuning, after prompting | Bakes the pattern into the model |
| Answers must be checked before use | Human review | No technique removes all errors |
Rung four is not a rung: review and monitoring
The side rail of Farah's ladder runs the whole height: human-in-the-loop review and continuous monitoring. Every technique reduces errors; none removes them. Lesson 4 covers review workflows. Monitoring, covered in lesson 11, watches quality over time, because model providers upgrade models, documents change, and the kinds of questions users ask drift away from what was tested. Version control for prompts and settings, tracked KPIs, and a regular sample of outputs checked by people keep a system good after launch.
With the improved prompt, grounding in the catalogue and three examples, the second test batch of 50 drafts has no invented warranties and only two factual errors, both caused by a supplier spec sheet that was itself wrong. That last finding goes to the data readiness work in lesson 5. Fine-tuning is not needed for now; Farah notes it as an option to revisit if Birchline ever wants a smaller, cheaper model for very high volumes.
Common mistakes
MistakeAssuming a fluent answer is a correct answer.
InsteadExpect hallucinations; ground factual tasks and check claims.
MistakeFine-tuning to teach a model facts that change.
InsteadGround for knowledge that changes; tune for consistent behaviour.
MistakeJumping to fine-tuning before improving the prompt.
InsteadStart with prompting and examples, then grounding, then tuning if needed.
MistakeUsing a high temperature for factual output.
InsteadUse low temperature where consistency matters.
MistakeGrounding on documents nobody has checked.
InsteadMake sure grounding sources are accurate, current and permissioned.
Summary and key terms
- Generative models hallucinate, have a knowledge cutoff, depend on their data, can reflect bias, struggle with edge cases and can be inconsistent.
- Prompt engineering is the cheapest fix: roles, constraints, examples (zero-, one- and few-shot), chaining, chain-of-thought and ReAct.
- Sampling settings such as temperature, top-p, output length and safety settings tune behaviour.
- Grounding connects output to first-party, third-party or world data; retrieval-augmented generation finds relevant passages and adds them to the prompt, keeps answers current and enables citations.
- Fine-tuning changes a model's behaviour using many examples but should not be used to teach changing facts.
- Human review and monitoring are needed at every level.
- Hallucination
- A confident, plausible but false output.
- Knowledge cutoff
- The point after which a model has no training data.
- Prompt engineering
- Designing instructions and context to get the intended output.
- Few-shot prompting
- Including several examples of good output in the prompt.
- Prompt chaining
- Splitting a task into steps where each output feeds the next prompt.
- Temperature
- A setting controlling how random the model's word choices are.
- Grounding
- Connecting model output to verifiable sources of information.
- RAG
- Retrieval-augmented generation: retrieving relevant passages and giving them to the model with the question.
- Fine-tuning
- Further training a model on examples to specialize its behaviour.
- Embedding
- A numeric representation of meaning used to find similar content.
Practice problems
Work each problem on paper first, then reveal the answer to check.
A policy assistant gives answers based on last year's returns policy. Which technique fixes this best?
Show answer
Grounding with retrieval over the current policy documents.
Why does the Birchline prompt ask for MISSING rather than a guess?
Show answer
It removes the model's tendency to fill gaps with invented details and makes gaps visible to the editor.
What does "ground for knowledge, tune for behaviour" mean?
Show answer
Use retrieval for facts that change; use fine-tuning, if needed, for a consistent style or task pattern.
Asking good questions of technical teams
Leaders rarely tune prompts or build retrieval themselves, but they approve the work and the budget. Farah gives Jules a short set of questions that reveal whether a team has chosen sensible techniques. What specific errors did you see before this change, and how often? Which technique did you try first, and what did it fix? How are the grounding documents kept current, and who owns them? What happens when the model has no good source for an answer? How do you know the change did not make something else worse? A team that can answer these clearly has usually climbed the ladder in the right order. A team that jumps straight to "we need to fine-tune a model" without describing the errors it is fixing probably has not.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.