
AI-430 · Lesson 3 of 12 · 25 min
Scalable oversight
Learning from human feedback works when humans can tell good outputs from bad ones. That assumption weakens as AI systems take on harder tasks: a 2,000-line program, a proof, a research summary drawing on hundreds of papers, or a multi-step plan whose consequences unfold over weeks. Human raters cannot check such outputs reliably, so they may reward work that looks right rather than work that is right, and Lesson 2 showed where that leads. Scalable oversight is the research programme that asks how humans can supervise AI systems on tasks that exceed their own ability to evaluate directly. This lesson covers the problem, AI-assisted evaluation and critique, debate, recursive decomposition, constitutional approaches, weak-to-strong generalization, and how these ideas are tested.
The oversight gap
Supervision requires a signal that distinguishes good from bad behaviour. For some tasks, the signal is cheap and reliable: a math answer can be checked, code can be run against tests (though tests can be gamed, Lesson 2), and a translation can be judged by bilingual speakers. For many valuable tasks, evaluation is harder than generation is for the model: verifying that a long piece of code has no subtle security flaw, that a medical summary omits nothing important, or that an agent's actions over hours had no harmful side effects. If evaluators miss errors systematically, training teaches the model to produce exactly the errors evaluators miss. The gap between what models can do and what humans can verify is the oversight gap, and it is expected to widen as capabilities grow.
AI-assisted evaluation and critique
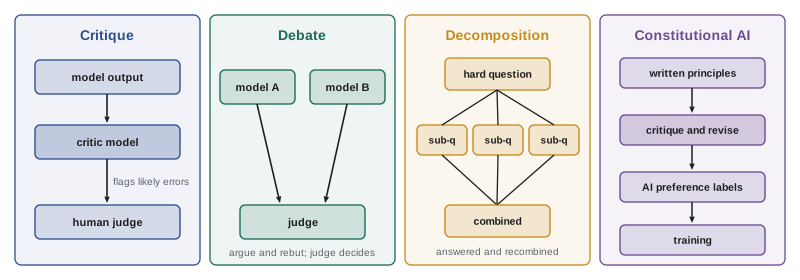
The most direct response is to use AI to help humans evaluate AI. A critique model reads an output and points out possible flaws, with explanations and evidence; human evaluators then judge the output with the critique in hand. Experiments have found that model-written critiques help humans find substantially more flaws in summaries and code than they find unaided, including flaws they would otherwise have missed. Critiques are easier to check than the original task, because a critique points to a specific problem that can be verified. The approach has an obvious risk: if the critic shares the generator's blind spots, or if it is itself misaligned, it may fail to flag the most important problems. Training critics to be helpful to evaluators, and testing them on outputs with known planted flaws, mitigates the risk.
Debate
In AI safety via debate, proposed by Irving, Christiano and Amodei in 2018, two AI systems argue opposing answers to a question before a human judge, each trying to expose flaws in the other's argument. The hope is that, in a well-designed debate, it is harder to defend a false answer than to refute it, so honest strategies win, and the judge needs only to evaluate the specific points in contention, not the whole problem. Recent experiments with language models on reading comprehension tasks, where the judge cannot see the source text but the debaters can, have found that debate helps non-expert judges reach correct answers more often than consultancy with a single model, especially as debaters become more capable. Open questions include whether debates remain honest-favouring for complex real-world questions, and how to prevent persuasive but misleading tactics.
Recursive decomposition
Another family of approaches breaks hard tasks into easier pieces. Iterated amplification proposes that a human assisted by copies of a model can answer harder questions than either alone, by decomposing the question into sub-questions that the model answers; the model is then trained to imitate the amplified system, and the process repeats. Recursive reward modelling similarly uses models trained on easier evaluations to help humans evaluate harder tasks. Practical versions of this idea appear in evaluation pipelines that check a long document section by section, or verify each step of a reasoning chain, and in process supervision (Lesson 2). The central assumption, that hard tasks decompose into checkable parts, holds for many tasks but not all.
Constitutional AI and AI feedback
Constitutional AI, introduced by Anthropic in 2022, replaces much of the human feedback used for harmlessness training with AI feedback guided by a written set of principles (a constitution). The model critiques and revises its own responses according to the principles, and a preference model trained on AI judgements guided by the constitution provides the reward for reinforcement learning (often called RLAIF, reinforcement learning from AI feedback). The approach scales feedback cheaply and makes the governing principles explicit and inspectable. Its limits are that the AI judge's judgements are only as good as the model and the principles, and that subtle errors in the AI feedback can be amplified by optimization; human oversight remains necessary to check that the resulting behaviour matches the intent.
Weak-to-strong generalization
A different framing asks: if humans are weak supervisors of a stronger model, can the strong model still learn the intended behaviour, generalizing beyond the errors in its supervision? Burns and colleagues at OpenAI (2023) studied an analogy: fine-tuning a strong pretrained model on labels produced by a weaker model, and measuring how much of the gap between the weak supervisor and the strong model's ceiling is recovered (the performance gap recovered, PGR). They found that strong students often substantially exceed their weak teachers, but recover only part of the gap, and that simple techniques such as an auxiliary confidence loss increase recovery.
import numpy as np
from sklearn.datasets import make_classification
from sklearn.linear_model import LogisticRegression

# Weak-to-strong generalization in miniature: does a strong student surpass its weak teacher?
X, y = make_classification(n_samples=24000, n_features=40, n_informative=20, n_redundant=0,
                           flip_y=0.0, class_sep=1.0, random_state=3)
X_sup, y_sup = X[:2000], y[:2000]
X_tr, y_tr = X[2000:16000], y[2000:16000]
X_te, y_te = X[16000:], y[16000:]
rng = np.random.default_rng(3)

def fit_score(labels):
    return LogisticRegression(max_iter=3000).fit(X_tr, labels).score(X_te, y_te)

ceiling = fit_score(y_tr)

# Teacher 1: systematic errors (it only sees 8 of the 40 features)
weak = LogisticRegression(max_iter=3000).fit(X_sup[:, :8], y_sup)
weak_acc = weak.score(X_te[:, :8], y_te)
labels_sys = weak.predict(X_tr[:, :8])

# Teacher 2: same accuracy, but its mistakes are random rather than systematic
flip = rng.random(len(y_tr)) > np.mean(labels_sys == y_tr)
labels_rand = np.where(flip, 1 - y_tr, y_tr)

for name, labels in [("systematic teacher errors", labels_sys), ("random teacher errors", labels_rand)]:
    acc = fit_score(labels)
    pgr = (acc - weak_acc) / (ceiling - weak_acc)
    print(f"{name:<26} label accuracy {np.mean(labels == y_tr):.3f}, student accuracy {acc:.3f}, PGR {pgr:5.2f}")
print(f"Weak teacher test accuracy {weak_acc:.3f}; strong ceiling {ceiling:.3f}")systematic teacher errors label accuracy 0.710, student accuracy 0.707, PGR 0.01 random teacher errors label accuracy 0.712, student accuracy 0.820, PGR 0.93 Weak teacher test accuracy 0.706; strong ceiling 0.829
The toy experiment isolates a key factor. Both teachers label about 71 % of training examples correctly. When the errors are random, the strong student averages them away and reaches 82 % accuracy, recovering over 90 % of the gap. When the errors are systematic, arising because the weak teacher sees only some of the features, the student, which can represent the teacher's simpler rule exactly, learns to imitate the errors, and recovers almost nothing. The lesson for oversight is that what matters is not only how often supervisors are wrong, but whether their errors form a pattern the model can learn. Human evaluators' errors are often systematic (preferring confident, agreeable, longer answers), which is exactly the kind a capable model can imitate.
Testing oversight methods
Because we cannot yet test oversight on superhuman systems, researchers use analogies. Sandwiching experiments, proposed by Cotra and studied by Bowman and colleagues, place a model between non-expert evaluators and domain experts: the model is more capable than the non-experts but less than the experts, so the experts can judge whether an oversight method helps non-experts supervise the model correctly. Other tests plant known flaws in outputs and measure whether a method helps evaluators find them, or train models with hidden objectives and test whether auditors using oversight tools can uncover them. These experiments are imperfect proxies, but they turn scalable oversight from a theoretical concern into a measurable research area.
Worked problem
Designing an evaluation with critiques
A team must evaluate whether a coding model's pull requests contain security vulnerabilities, but its reviewers are generalist engineers who miss many subtle flaws. Design an oversight process and a way to test it.
Show solution
- Add a critique model that reviews each pull request and lists suspected vulnerabilities with the relevant code lines and an explanation.
- Reviewers judge each pull request with the critique, confirming or rejecting each flagged issue.
- Test the process by planting known vulnerabilities in a sample of pull requests and measuring the detection rate with and without critiques, and with critiques from a deliberately weakened critic.
- Have security experts audit a random sample of approved pull requests to estimate the residual miss rate.
Answer: The planted-flaw test measures how much critiques help and reveals blind spots, while expert audits estimate what still gets through. The process scales review while keeping humans responsible for decisions, and its measured miss rate tells the team how much to rely on it.
Oversight in current practice
Scalable oversight is not only a research topic for future systems. Today's developers already rely on AI assistance to supervise AI: models critique other models' outputs, flag likely errors in code for human reviewers, grade responses against written principles, and summarize long agent transcripts so that a human can review them in minutes rather than hours. Studies of AI-assisted review have found that critic models help human raters find more flaws in code and written answers than they would unaided, while also showing the risks: critics can hallucinate problems, and reviewers may come to trust them too much.
Several practical lessons follow:
- Measure the combined system: the relevant question is whether humans with AI assistance reach better judgments than humans alone, which should be tested on tasks with known answers.
- Use sandwiching experiments: give non-expert overseers, assisted by a model, tasks where experts know the answer, and measure how close the assisted non-experts get to expert performance.
- Watch for automation bias: track how often reviewers accept AI suggestions and how often those suggestions are wrong.
- Keep a human audit layer: a sample of decisions should be reviewed in depth without AI assistance, as a check on the assisted process.
These practices make oversight measurable, which is a precondition for trusting it as models become more capable than their supervisors in more domains.
Oversight methods also have to be judged by how they fail. Debate may favour the more persuasive debater rather than the more truthful one, decomposition can lose context that matters across subtasks, and weak-to-strong methods may transfer the supervisor's systematic errors, as the simulation in this lesson showed. Knowing these failure modes helps decide which method suits a given task.
Common mistakes
MistakeAssuming human ratings remain reliable as tasks get harder.
InsteadMeasure evaluator accuracy and use oversight aids for hard tasks.
MistakeTrusting a critic model without testing it.
InsteadTest critics on outputs with planted flaws.
MistakeTreating AI feedback as ground truth.
InsteadCheck AI feedback against human judgement on samples.
MistakeFocusing only on how often supervisors err.
InsteadExamine whether supervisor errors are systematic and learnable.
MistakeClaiming an oversight method works without evidence.
InsteadTest it with sandwiching, planted flaws or auditing games.
Summary and key terms
- Scalable oversight addresses supervising AI on tasks humans cannot easily evaluate.
- The oversight gap grows as capabilities outpace verification.
- Critique models help humans find flaws; critiques are easier to check than the task.
- Debate pits models against each other so that a judge evaluates contested points.
- Decomposition and constitutional AI scale feedback with explicit structure and principles.
- Weak-to-strong generalization succeeds when supervisor errors are not systematic.
- Sandwiching, planted flaws and auditing games test oversight methods.
- Scalable oversight
- Methods for supervising AI on tasks beyond direct human evaluation.
- Oversight gap
- The difference between what models can do and what humans can verify.
- Critique model
- A model that identifies flaws in another model's output.
- Debate
- An oversight method in which models argue opposing answers before a judge.
- Iterated amplification
- Training models to imitate human-plus-model teams on decomposed tasks.
- Constitutional AI
- Training with AI feedback guided by written principles.
- RLAIF
- Reinforcement learning from AI feedback.
- Weak-to-strong generalization
- A strong model learning beyond the errors of a weak supervisor.
- PGR
- Performance gap recovered.
- Sandwiching
- Testing oversight with a model between non-experts and experts in capability.
Practice problems
Work each problem on paper first, then reveal the answer to check.
What is the oversight gap?
Show answer
The gap between what models can do and what humans can verify.
Why are critiques easier to check than the original task?
Show answer
They point to specific problems that can be verified directly.
What is the main hope behind debate?
Show answer
That false answers are harder to defend than to refute, so honest debaters win.
What assumption does recursive decomposition rely on?
Show answer
That hard tasks decompose into checkable sub-tasks.
What is a constitution in constitutional AI?
Show answer
A written set of principles guiding AI feedback.
Weak accuracy 0.6, ceiling 0.9, student 0.8. What is the PGR?
Show answer
(0.8 − 0.6) / (0.9 − 0.6) ≈ 0.67.
From the output, why does the student recover little with systematic teacher errors?
Show answer
It can represent and imitate the teacher's simpler rule, including its errors.
Why is the result relevant to human feedback?
Show answer
Human evaluator errors are often systematic and learnable.
What is a sandwiching experiment?
Show answer
Testing whether an oversight method helps non-experts supervise a model that experts can judge.
In the example, how is the oversight process tested?
Show answer
By planting known vulnerabilities and measuring detection, plus expert audits.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.