
MSAZ-282 · Lesson 12 of 12 · 22 min
A database operations runbook
▶ Video coming soon A video version of this lesson is on the way.
On the last evening of the clinic's autumn series, Elena gives Walt a task instead of a lesson. "Your binder has served this company for seventeen years," she says. "By the end of 2027 it will describe servers that no longer exist. Write the new one: the runbook that someone else could pick up at three in the morning and use to keep the Azure estate healthy." This lesson follows Walt as he assembles the Harrow & Finch database operations runbook from the pieces built in this course: automated tasks and their owners, alerts and who answers them, recovery tiers and designs, backup and retention policies, and the tests that prove them. It is also a review of the course, and of the skills the DP-300 outline groups under automation and high availability and disaster recovery.
What a runbook is for
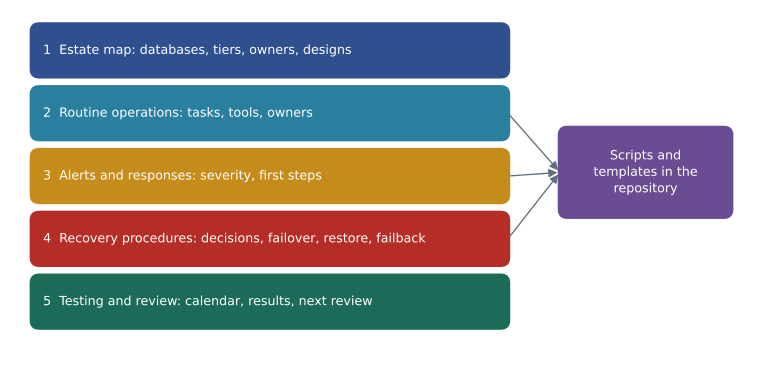
A runbook is a set of written procedures for operating a system: what happens routinely, what to do when something goes wrong, and who decides. A good runbook is written for the reader who knows the technology but not this estate, at the worst possible moment. It is short where it can be, exact where it must be, kept in a place everyone can reach even when Azure is having a bad day, and reviewed on a schedule. Walt's runbook has five parts: an estate map, routine operations, alerts and responses, recovery procedures, and testing and review. Each part links to the scripts and templates in the team's repository rather than copying them, so there is one version of each.
Part 1: the estate map
The first page lists every database with its owner, recovery tier, objectives, design and where its recovery procedure is. It is the page a responder reads first, because it answers the question that decides everything else: how much does this database matter, and what has been built for it?
| Database | Tier | RPO / RTO | Platform | HA | DR | Backups and retention |
|---|---|---|---|---|---|---|
| StockLine, Pricing | 1 | 5 min / 1 h | Business Critical managed instance | Zone redundant | Failover group to East US 2, customer-managed | PITR 14 days; LTR 8W/12M/7Y; monthly COPY_ONLY |
| Finch Rewards | 2 | 1 h / 4 h | General Purpose SQL Database | Zone redundant | Failover group, customer-managed | PITR 14 days; LTR 4W/12M/3Y |
| Store scheduling (23) | 2 | 1 h / 4 h | Elastic pool | Zone redundant | Failover group for the pool's databases | PITR 7 days; LTR 6M |
| SalesHistory | 3 | 24 h / 24 h | Hyperscale | One HA replica | Geo-restore | PITR 7 days; LTR 7Y |
| Warehouse WMS | Vendor | 15 min / 2 h | SQL Server 2022 on VMs | AG across two zones | Async AG replica in the paired region | Azure Backup, logs every 15 min |
| Finance (HF-SQL02, until 2027) | 3 | 1 h / 24 h | On premises, Arc-enabled | None | Log shipping to Azure storage | Native backups; 7 years on archive tier |
Part 2: routine operations
The routine section lists every scheduled task with its frequency, tool, owner and the way a failure would be noticed, so that a missing run is as visible as a failed one. It brings together the Agent jobs and elastic jobs from lesson 1, the runbooks from lesson 2 and the alerts from lesson 3. Walt adds one daily human task: the on-call DBA reads the overnight summary at 07:30 and signs it off in the operations log. Automation reports, but a person confirms.
| Frequency | Task | Tool | Failure noticed by |
|---|---|---|---|
| Nightly | StockLine statistics and index maintenance | Agent on Managed Instance | Job notification; overnight summary |
| Nightly | Store scheduling purge | Elastic job on the pool | Log alert if fewer than 23 targets succeeded |
| Daily 07:30 | Read and sign off the overnight summary | Person, on call | Escalation if not signed by 09:00 |
| Weekly | Compare Agent jobs and logins on primary and secondary instances | Automation runbook | Runbook alert; differences emailed |
| Monthly | Restore test of one database, with DBCC CHECKDB | Runbook and Agent job | Alert on failure or 20 in 100 slower |
| Monthly | COPY_ONLY backup of StockLine for the auditors | Agent job | Job notification |
| Quarterly | Copy Finch Rewards to test and mask it | Automation runbook | Runbook alert; Teams post on success |
| Twice a year | Production failover drill and tabletop exercise | People, with runbooks | Test report |
| Each spring | Scale StockLine up and down | Scheduled runbooks | Runbook alert |
Part 3: alerts and responses
Every alert rule has a runbook entry with its meaning, its severity, its action group and the first three things to check. The entries are written as questions, because a responder at three in the morning thinks in questions. For example, for the alert "Replication lag above 30 seconds for 10 minutes, Finch Rewards": Is the primary running a large batch or rebuild? Is the secondary the same size as the primary? Is the replication link healthy? Each entry ends with when to escalate and to whom. Walt keeps severities honest: severity 0 means customers are affected now and someone must act within 15 minutes; severity 1 means they will be soon; anything else waits until working hours.
Part 4: recovery procedures
The recovery section starts with decision rules, because lesson 4 showed that deciding is the slowest step. The rules say who may declare a disaster for each tier, what evidence is enough, and what to do if the decision-maker cannot be reached within 10 minutes. For tier 1, the on-call DBA and the duty manager together may declare a disaster and force the StockLine failover if the primary region has been unavailable for 15 minutes and Azure Service Health confirms a regional incident; if the duty manager cannot be reached, the data platform lead may decide alone. Then each procedure lists its steps with commands, expected results and checks, for failover, restore and failback.
Worked problem
Choosing the right recovery
At 10:20 on a Saturday, three things are reported at once. (1) StockLine's managed instance had a 20-second disconnect at 10:12 and is now working. (2) A buyer says that 600 product prices were overwritten by a bad import at 10:05. (3) Azure Service Health reports degraded storage in one availability zone of Central US. Which recovery procedure, if any, does each need?
Show solution
- (1) A 20-second disconnect followed by normal running is a high-availability failover inside the region; the built-in architecture worked. No procedure is needed beyond checking that applications reconnected.
- (2) Overwritten prices are data errors that the replicas copied. The procedure is a point-in-time restore of Pricing to a new database at 10:04, comparing and copying back the 600 rows, as in lesson 9.
- (3) A degraded zone is what zone redundancy is for. The procedure is to watch: confirm the instance is healthy in the other zones, and prepare, but not start, the failover group procedure in case the incident spreads.
- None of the three is a regional disaster, so the failover group is not failed over.
Answer: Only the price problem needs a recovery procedure, a point-in-time restore to a new database. The disconnect and the zone incident are handled by built-in high availability and need monitoring, not failover.
Failback deserves its own page. After a forced failover, the team will run in the secondary region for hours or days. The failback page lists the conditions for returning (the primary region declared healthy, the old primary resynchronized as secondary, a quiet period agreed with the business), the planned failover command, and the checks afterwards. It also says that failing back is optional: if the secondary region is serving well, the team may stay there until the next drill.
Part 5: testing and review
The last section holds the test calendar from lesson 11, the results of the most recent tests with their achieved RTO and RPO, and the list of improvements still open. It also sets a review date. Walt's runbook is reviewed every six months, after every real incident or production drill, and whenever the estate changes: a new database, a new tier, a change of region. Each review checks that the names, scripts and contacts are still right, which is where most runbooks quietly go wrong.
Worked problem
Checking the tier 1 recovery budget after the drill
In the planned StockLine drill, the team expects these times for a forced failover: detection 5 minutes, reaching the decision-makers and deciding 10 minutes under the new rules, the failover command and DNS changes 4 minutes, tills and services reconnecting 12 minutes, and checks 9 minutes. The previous estimate, from lesson 4, was 45 minutes. What is the new total, how much margin is left in the 1-hour RTO, and which step changed most?
Show solution
- New total: 5 + 10 + 4 + 12 + 9 = 40 minutes.
- Margin: 60 − 40 = 20 minutes.
- Compared with lesson 4: decision fell from 15 to 10 minutes (−5), failover from 5 to 4 (−1), reconnecting rose from 10 to 12 (+2), checks fell from 10 to 9 (−1), so the total fell by 5 minutes.
- The decision rules saved the most time.
Answer: The estimate is now 40 minutes, leaving 20 minutes of margin. The clearer decision rules made the biggest difference; the drill will show whether the reconnect estimate is realistic.
Python example
Walt wants the runbook's estate map to warn him automatically when a design no longer meets its tier. He writes a small check that compares each database's tested RTO and RPO with its objectives, and plans to run it after every test.
estate = [
    # name, RPO objective (min), RTO objective (min), last tested RPO (min), last tested RTO (min)
    ("StockLine",      5,   60,    0.2,  40),
    ("Finch Rewards", 60,  240,    0.1,  25),
    ("SalesHistory", 1440, 1440,  37,    66),
    ("Warehouse WMS", 15,  120,    0.5, 135),
]
for name, rpo, rto, t_rpo, t_rto in estate:
    problems = []
    if t_rpo > rpo: problems.append(f"RPO {t_rpo} > {rpo}")
    if t_rto > rto: problems.append(f"RTO {t_rto} > {rto}")
    status = "meets its tier" if not problems else "REVIEW: " + ", ".join(problems)
print(f"{name:14s} {status}")StockLine meets its tier Finch Rewards meets its tier SalesHistory meets its tier Warehouse WMS REVIEW: RTO 135 > 120
What this code does
The program holds a short list of databases, each with its agreed recovery point and recovery time objectives and the values measured in the latest test, all in minutes. For each database it checks whether the measured data loss or recovery time was larger than the objective. It prints either that the database meets its tier or which objective it missed. In this sample, the warehouse system's tested recovery time of 135 minutes is longer than its 2-hour objective, so it is flagged for review.
The output flags the warehouse system, whose last test in the vendor's lab took 135 minutes against a 2-hour objective. That is exactly the kind of finding the runbook's review exists to catch, and Walt adds it to the open improvements: rehearse the availability group failover with the vendor's engineers before the warehouse goes live.
Looking back over the course
Walt's runbook is also a map of what this course covered. Automation of tasks: Agent jobs and elastic jobs for work inside databases, PowerShell, the CLI, runbooks and templates for work on resources, and alerts and action groups so that every task's failure is noticed. High availability and disaster recovery: recovery objectives agreed with the business, the built-in availability of each service tier and zone redundancy, geo-replication and failover groups across regions, availability groups, failover cluster instances and log shipping on virtual machines, point-in-time and long-term backups, and tests that turn a plan into evidence. MSAZ-281 covers the security, monitoring and tuning that keep the same databases safe and fast, and MSAZ-289 brings all three courses together for the exam.
Common mistakes
MistakeA runbook should copy every script so it is self-contained.
InsteadLink to one version of each script or template in the repository, so the runbook never drifts from the code.
MistakeEvery incident affecting a database needs the disaster-recovery procedure.
InsteadMost incidents are handled by built-in high availability or a point-in-time restore; regional failover is for regional disasters.
MistakeFailback must happen as soon as the primary region recovers.
InsteadFailback is optional and should be a planned failover at a quiet time.
MistakeA runbook is finished once it is written.
InsteadReview it on a schedule and after every incident, drill or estate change.
Summary and key terms
- A runbook lets someone who knows the technology but not the estate operate it at the worst moment.
- Walt's runbook has an estate map, routine operations, alerts and responses, recovery procedures, and testing and review.
- Every routine task has a tool, an owner and a way its failure or absence is noticed.
- Recovery procedures begin with decision rules, then list commands, expected results and checks, including failback.
- Match each incident to the right response: built-in HA, point-in-time restore or regional failover.
- Review the runbook regularly and compare tested RPO and RTO with each tier's objectives.
- Runbook
- A set of written procedures for operating a system, including routine work, responses and recovery.
- Estate map
- A list of every database with its owner, tier, objectives and design.
- Decision rule
- A written rule for who may declare a disaster and on what evidence.
- Failback
- Returning the primary role to the original region after a failover.
- Escalation
- Passing an incident to a more senior or specialist person when first steps do not resolve it.
- Open improvement
- A finding from a test or review that has not yet been fixed.
Practice problems
Work each problem on paper first, then reveal the answer to check.
What are the five parts of Walt's runbook?
Show answer
Estate map, routine operations, alerts and responses, recovery procedures, and testing and review.
Why does the runbook link to scripts instead of copying them?
Show answer
So there is only one version of each script or template.
Which incident needs a point-in-time restore rather than a failover?
Show answer
A data error such as overwritten prices, because replicas copy it.
When should failback happen?
Show answer
When the business agrees, as a planned failover at a quiet time; it is optional.
Which database did the Python check flag?
Show answer
The warehouse system, whose tested RTO was longer than its objective.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.