
AI-101 · Lesson 10 of 12 · 29 min
AI in practice: from idea to deployed system
Most of the effort in real AI projects goes not into inventing algorithms but into everything around them: choosing the right problem, collecting and cleaning data, deciding how to measure success, integrating the model into a product or process, and keeping it working after launch. Surveys of organizations repeatedly find that many AI projects never reach production or fail to deliver value, usually for practical rather than technical reasons. This lesson walks through the life cycle of an applied AI system, using examples from industry, health care and data center operations, and explains the decisions that separate useful systems from expensive experiments. It also covers the newer pattern of building applications on top of general-purpose AI models.
Start with the problem, not the technology
A good AI project starts with a clear problem and a decision or action that a better prediction would improve. Useful questions to ask:
- What decision will the system support or automate, and who makes it today?
- What does a mistake cost? Are false positives or false negatives worse?
- Is there enough relevant data, and is it legally and ethically usable?
- How will success be measured, in business or human terms, not just model accuracy?
- Would a simpler approach (a rule, a dashboard, a process change) solve most of the problem?
Many promising ideas fail these questions. A model that predicts equipment failure one hour ahead is useless if repairs take a day to arrange; a model with 95% accuracy is useless if 99% of cases are negative and a trivial rule already achieves 99% (Lesson 5).
Worked problem
Is the model worth it?
A data center has 2,000 cooling fans. About 2% fail per year, and each unplanned failure costs $3,000 in emergency work and risk. A predictive model would flag 70% of failures a week in advance, allowing planned replacement at $500 each, but it also produces 60 false alarms a year, each costing $200 in inspection time. The model costs $15,000 a year to run. Is it worth deploying?
Show solution
- Failures per year: \(0.02 \times 2000 = 40\). Without the model: \(40 \times 3000 = \$120{,}000\).
- With the model: caught \(0.7 \times 40 = 28\) at $500 = $14,000; missed 12 at $3,000 = $36,000; false alarms \(60 \times 200 = \$12{,}000\); running cost $15,000.
- Total with the model: \(14{,}000 + 36{,}000 + 12{,}000 + 15{,}000 = \$77{,}000\).
Answer: The model saves about $43,000 a year ($120,000 versus $77,000). The analysis also shows which levers matter: catching a higher share of failures saves the most, while false alarms and running costs eat into the benefit. Framing value this way, before building, is how successful teams choose projects.
The AI project life cycle
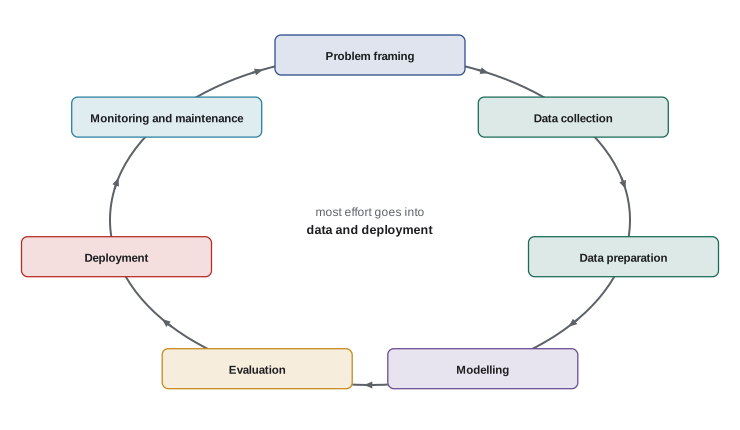
Applied AI projects follow a recognizable cycle, often iterated many times:
1. Problem framing: define the decision, users, constraints and success metrics.
2. Data collection: gather historical data and, where needed, labels; check consent, ownership and privacy.
3. Data preparation: clean errors, handle missing values, join sources, and split data into training, validation and test sets.
4. Modeling: start with a simple baseline, then try more complex models; tune and compare them on validation data.
5. Evaluation: test on held-out data that resembles real use, including subgroups and edge cases; involve domain experts.
6. Deployment: integrate the model into software and workflows, with user interfaces, alerts and fallbacks.
7. Monitoring and maintenance: track performance, data drift and incidents, and retrain or retire the model as needed.
Data: the largest share of the work
Practitioners often say that most of their time goes into data. Typical problems include missing values, inconsistent formats, duplicate records, sensor errors, labels that are wrong or inconsistent between annotators, and data that does not represent the people or situations the system will face. Data must also be split carefully: if information about the test examples leaks into training (for example, records of the same patient in both sets, or features that are only known after the outcome), the model will look much better in testing than in reality. This data leakage is one of the most common causes of disappointing deployments.
Worked problem
Detecting leakage
A model predicting which customers will cancel a subscription reaches 99% accuracy. One of its input features is "number of days since last login, measured at the end of the month". Cancellations happen during the month. What might be wrong?
Show solution
- Customers who canceled stop logging in, so their "days since last login" at month end is large.
- The feature therefore encodes the outcome itself, information not available at prediction time.
Answer: The feature leaks the answer. At prediction time, before customers cancel, the model would not have this information and its accuracy would collapse. Every feature should be checked against the question: would we know this at the moment we need the prediction?
Evaluation that reflects reality
Good evaluation goes beyond a single accuracy number. Teams compare models against a simple baseline (such as predicting the most common class or using last year's value), report metrics that match the costs of errors (precision, recall, false alarm rate), check performance for different groups and conditions, and test on data from a later time period than the training data, because the future often differs from the past. For high-stakes uses, prospective trials (testing the system on new cases as they occur, alongside existing practice) give the strongest evidence. In medicine, regulators require such evidence before approving AI software as a medical device.
Deployment and people
A model only creates value when it changes what people or systems do. Deployment decisions include whether the model acts automatically or advises a person, how its output is presented, what happens when it is uncertain or unavailable, and how users can give feedback or override it. Human factors matter: people may over-trust a system that is usually right (automation bias) or ignore one that raises too many false alarms (alarm fatigue). Explaining the basis of a prediction, showing confidence, and designing clear escalation paths help users rely on the system appropriately.
Monitoring, drift and maintenance
Unlike ordinary software, AI systems can degrade without any code changing, because the world changes. Data drift occurs when the inputs change (a new sensor model, a new customer group, a pandemic changing behavior); concept drift occurs when the relationship between inputs and outcomes changes (fraudsters adopting new tactics). Production systems therefore monitor input distributions, prediction distributions and, when outcomes become known, actual accuracy, and they schedule retraining. They also log decisions for audit and investigation. The engineering discipline of running machine learning in production is called MLOps (AI-420).
Worked problem
Spotting drift
A model predicting server failures was trained when the average inlet temperature was 22 °C. After a cooling change, inputs now average 26 °C, and the share of servers flagged has risen from 1% to 6% while actual failures are unchanged. What is happening, and what should the team do?
Show solution
- The inputs have shifted (data drift): the model has rarely seen 26 °C and associates high temperature with failure.
- Flags rose sixfold with no change in failures, so precision has collapsed.
Answer: The model is reacting to the new normal rather than to real risk. The team should investigate, retrain on recent data that reflects the new operating conditions, and add drift monitoring so similar shifts trigger alerts before users lose trust.
Building on foundation models
Since 2023, many AI applications are built not by training models from scratch but by using a general-purpose foundation model, such as a large language model, through an API or as an open-weight model run locally. Developers write instructions (prompts), supply relevant documents through retrieval-augmented generation, connect the model to tools and databases, and sometimes fine-tune it on examples (Lesson 9 and AI-410). This greatly lowers the cost of building prototypes, but the same life cycle still applies: define success, build evaluation sets of realistic inputs and expected outputs, test for errors and harmful outputs, monitor in production, and manage cost, since every request consumes paid computing.
| Approach | Data needed | Strengths | Weaknesses |
|---|---|---|---|
| Rules and conventional software | Expert knowledge | Predictable, explainable | Brittle, hard to scale to fuzzy tasks |
| Classical machine learning | Hundreds to millions of labeled rows | Efficient, well understood | Needs feature engineering and labels |
| Deep learning from scratch | Large labeled datasets | Best for perception at scale | Expensive, data-hungry |
| Foundation model with prompts and retrieval | Few examples plus documents | Fast to build, flexible | Cost per use, errors, dependency on provider |
| Fine-tuned foundation model | Hundreds to thousands of examples | Tailored behavior | More effort, must be maintained |
Case studies
- Medical imaging: AI tools that flag possible findings on scans have been cleared by regulators for many uses; the most successful deployments support radiologists, prioritizing urgent cases rather than replacing them, and were validated on data from the hospitals that use them.
- Data center operations: machine learning predicts cooling needs, detects failing equipment, forecasts capacity and optimizes energy use; operators typically keep humans in the loop for control actions on critical infrastructure.
- Customer service: assistants built on language models answer routine questions and draft responses for human agents; studies have reported productivity gains, especially for less experienced staff, alongside risks of incorrect answers that must be managed.
- Software development: AI coding assistants are now widely used to write and review code, with organizations adding tests and review processes to catch errors and security issues.
Privacy and data rights
AI projects often use personal information, and privacy law applies whether or not the law mentions AI. Teams should identify the legal basis for using each dataset, collect only what is needed, protect it with access controls and encryption, remove or mask identifying details where possible, and set retention limits. Using data collected for one purpose to train a model for another may require new consent.
In the United States, there is no single federal privacy law; sector laws such as HIPAA (health) and the Fair Credit Reporting Act (credit) apply, along with comprehensive privacy laws in a growing number of states, such as California's Consumer Privacy Act, some of which give rights related to automated decision-making. The Federal Trade Commission has acted against companies that used data deceptively to train AI models, in some cases requiring them to delete the models.
Privacy-enhancing techniques can help: training on de-identified or synthetic data, federated learning (training across devices or organizations without pooling raw data), and differential privacy (adding carefully calibrated noise so that no individual's data can be inferred from the model).
Governance in organizations
Organizations deploying AI increasingly adopt governance processes: an inventory of AI systems, risk assessments before deployment, documentation of data and models (often in "model cards" and "datasheets"), privacy reviews, testing for bias, human oversight for consequential decisions, incident reporting, and periodic audits. Frameworks such as the NIST AI Risk Management Framework and the international standard ISO/IEC 42001 for AI management systems give structure to this work and are used in both Canada and the United States, alongside the laws discussed in Lesson 11.
Common mistakes
MistakeStarting with a technology and looking for a problem.
InsteadStart with a decision and the value of improving it.
MistakeSkipping a simple baseline.
InsteadCompare every model with a simple rule or average.
MistakeIncluding features not available at prediction time.
InsteadCheck every feature for leakage.
MistakeAssuming a deployed model keeps working.
InsteadMonitor drift and performance and retrain as needed.
MistakeMeasuring only model accuracy.
InsteadMeasure the business or human outcome the system is meant to improve.
Summary and key terms
- Successful AI projects start from a decision, the cost of errors and measurable value.
- The life cycle runs from framing through data, modeling, evaluation, deployment and monitoring, repeatedly.
- Data preparation takes most of the effort; leakage inflates test results.
- Evaluation should use baselines, cost-aware metrics, subgroups and later data.
- Deployment design must address automation bias, alarm fatigue and fallbacks.
- Data and concept drift degrade models; MLOps monitors and retrains them.
- Foundation models speed development but still need evaluation, monitoring and cost control.
- Governance frameworks such as the NIST AI RMF and ISO/IEC 42001 structure responsible deployment.
- Baseline
- A simple method used as a point of comparison.
- Data leakage
- Information in training data that would not be available at prediction time.
- Validation set
- Data used to choose and tune models.
- Test set
- Held-out data used for a final, unbiased evaluation.
- Automation bias
- Over-reliance on automated recommendations.
- Alarm fatigue
- Ignoring alerts because too many are false.
- Data drift
- Change in the distribution of model inputs over time.
- Concept drift
- Change in the relationship between inputs and outcomes.
- MLOps
- Practices for deploying and maintaining machine learning in production.
- Model card
- A document describing a model's purpose, data, performance and limits.
Practice problems
Work each problem on paper first, then reveal the answer to check.
Name three questions to ask before starting an AI project.
Show answer
What decision, cost of mistakes, data availability, success measure, simpler alternatives.
500 failures a year at $1,000 each; a model catches 60% for $200 each and costs $50,000. Net saving?
Show answer
Without: $500,000. With: 300 × 200 + 200 × 1000 + 50,000 = $310,000. Saving $190,000.
List the stages of the AI project life cycle.
Show answer
Framing, data collection, preparation, modeling, evaluation, deployment, monitoring.
Why test on data from a later time period?
Show answer
The future may differ from the past; it reveals drift.
What is data leakage? Give an example.
Show answer
Using information unavailable at prediction time, e.g. a feature recorded after the outcome.
What is automation bias?
Show answer
Over-trusting a system's recommendations.
Distinguish data drift from concept drift.
Show answer
Inputs change versus the input-outcome relationship changes.
Why still build evaluation sets when using a foundation model?
Show answer
To measure accuracy, catch errors and compare prompts or models.
Name two governance frameworks for AI.
Show answer
NIST AI RMF and ISO/IEC 42001.
What does a model card document?
Show answer
Purpose, data, performance, limitations and intended use.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.