
PHIL-330 · Lesson 5 of 12 · 20 min
Algorithmic fairness
▶ Video coming soon A video version of this lesson is on the way.
Kwame arrives at the fifth session with a printout. A credit union in Riverton, Lakeside Credit Union, uses a model to score loan applications, and he has been asked to help audit it. The model does not use race, sex or age. Yet approval rates differ sharply between neighborhoods, and the neighborhoods with lower approval rates are ones where many newcomers and racialized residents live. 'The vendor says the model is fair because it's equally accurate for everyone,' Kwame says. 'The community group says it's unfair because it approves fewer people from their neighborhoods. I've checked, and they're both right. That's what I don't understand.'
Varga says Kwame has walked into one of the central results of the field: there are several reasonable definitions of fairness for a predictive model, and in most real situations they cannot all be satisfied at once. This lesson explains where unfairness in algorithms comes from, how it is measured, why the measures conflict and how philosophy can help choose among them.
Where algorithmic bias comes from
An algorithm can treat groups unequally even when no one intends it to and even when protected characteristics are not used. Researchers have described several sources of bias that can enter at different stages of building a system.
- Historical bias: the data accurately reflects a world shaped by past discrimination. A model trained on past hiring decisions in a field dominated by men can learn to prefer men.
- Representation bias: some groups are under-represented in the training data, so the model learns less about them and makes more errors.
- Measurement bias: the thing the model predicts, or the features it uses, measure different things for different groups. Arrests, for example, measure crime and also where police patrol.
- Aggregation bias: a single model is used for groups whose patterns differ, so it fits the majority well and others poorly.
- Deployment bias: a model is used in a setting or for a purpose different from the one it was built for, or people act on its outputs in uneven ways.
A widely discussed example of measurement bias came from health care. In 2019, Ziad Obermeyer and colleagues studied an algorithm used by health systems in the United States to identify patients who would benefit from extra care management. The algorithm predicted future health care costs as a stand-in for health need. Because less money had historically been spent on Black patients with the same level of illness, often because of unequal access to care, the algorithm judged Black patients to be healthier than equally sick white patients. At a given risk score, Black patients were considerably sicker. When the researchers changed the target from cost to direct measures of health, the share of Black patients selected for extra help rose substantially. The model had no variable for race; the bias came from the choice of what to predict.
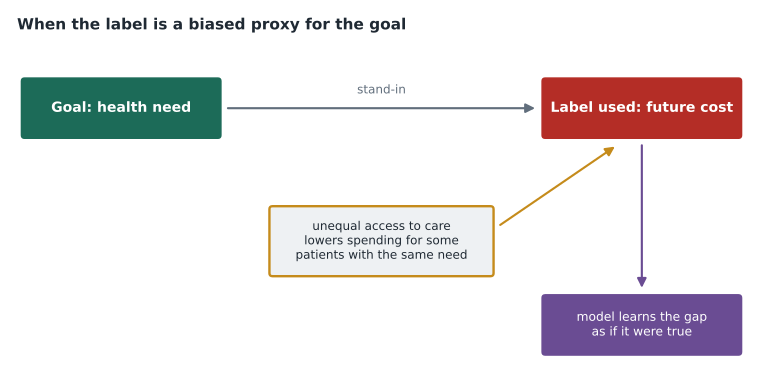
Raúl notes that Pathfinder is trained to predict whether a patient will be admitted to intensive care, and asks whether admission has the same problem. Kwame says it might: if some patients were less likely to be admitted for reasons other than how sick they were, the model will learn that pattern too.
Fairness through unawareness
The simplest proposal for fairness is to leave protected characteristics out of the model. Lakeside's vendor does this. But it rarely works, because other variables act as proxies. Postal code can stand in for race or ethnicity in segregated cities; first names can suggest sex and ethnicity; employment gaps can stand in for caregiving and so for sex; and combinations of many weak proxies can reconstruct a protected characteristic quite accurately. In 2018, it was widely reported that an experimental hiring tool at Amazon, trained on ten years of résumés submitted mostly by men, had learned to penalize résumés containing the word 'women's', as in 'women's chess club captain', and the graduates of two women's colleges. The company abandoned the tool.
Removing protected characteristics can even make it harder to detect and correct unfairness, because auditors then cannot measure outcomes by group. Many fairness researchers argue that protected characteristics should be collected, kept separate and used to test and adjust models, even if they are not used as inputs.
Measuring fairness
To measure the fairness of a classifier, such as a model that approves or denies loans, researchers compare outcomes between groups. The comparison starts with a confusion matrix for each group, which counts four outcomes: true positives (the model approves someone who repays), false positives (it approves someone who defaults), true negatives (it denies someone who would have defaulted) and false negatives (it denies someone who would have repaid). From these counts come several common definitions of fairness.
- Demographic parity, or statistical parity: each group is approved at the same rate.
- Equal opportunity: among people who would repay, each group is approved at the same rate; that is, the true positive rates are equal.
- Equalized odds: both the true positive rates and the false positive rates are equal across groups.
- Predictive parity: among people the model approves, the same share in each group actually repays; that is, a positive prediction means the same thing for everyone.
- Calibration: for every score, people with that score in each group have the same chance of the outcome. Calibration is a stronger version of predictive parity, applied at every score.
# Lakeside loan model: outcomes by group (illustrative counts)
groups = {
    "Group A": {"tp": 540, "fp": 60, "fn": 60, "tn": 340},
    "Group B": {"tp": 180, "fp": 20, "fn": 60, "tn": 240},
}
for g, c in groups.items():
    n = sum(c.values())
    approval = (c["tp"] + c["fp"]) / n
    tpr = c["tp"] / (c["tp"] + c["fn"])          # approved, among those who would repay
    fpr = c["fp"] / (c["fp"] + c["tn"])          # approved, among those who would default
    ppv = c["tp"] / (c["tp"] + c["fp"])          # repaid, among those approved
    base = (c["tp"] + c["fn"]) / n               # share who would repay
    print(g, "approval", round(approval, 2), "TPR", round(tpr, 2),
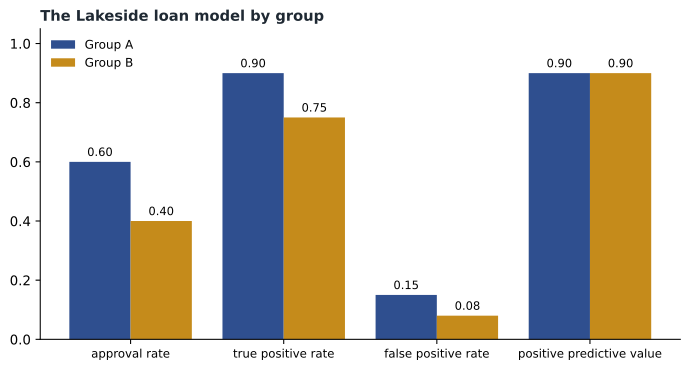
"FPR", round(fpr, 2), "PPV", round(ppv, 2), "base rate", round(base, 2))Group A approval 0.6 TPR 0.9 FPR 0.15 PPV 0.9 base rate 0.6 Group B approval 0.4 TPR 0.75 FPR 0.08 PPV 0.9 base rate 0.48
The output explains Kwame's puzzle. A positive prediction means the same thing in both groups: nine in ten approved applicants repay, so the model satisfies predictive parity, which is what the vendor meant by equally accurate. But Group B is approved much less often, and, more importantly, applicants in Group B who would have repaid are approved less often than equally creditworthy applicants in Group A: the true positive rate is 0.75 against 0.90. A creditworthy applicant in Group B has a noticeably higher chance of being wrongly denied. That is what the community group is objecting to.
Why the definitions conflict
In 2016 the news organization ProPublica analyzed COMPAS, a risk assessment tool used in some American courts to predict whether defendants would reoffend. It found that Black defendants who did not go on to reoffend were nearly twice as likely as white defendants to be labeled high risk: the false positive rates were unequal. The tool's developer responded that the scores were calibrated: a given score meant about the same likelihood of reoffending for Black and white defendants. Both claims were true.
Shortly afterward, Jon Kleinberg, Sendhil Mullainathan and Manish Raghavan, and separately Alexandra Chouldechova, proved that this was not a coincidence. When the base rate of the outcome differs between groups, a classifier that is not perfect cannot satisfy calibration and also have equal false positive and false negative rates across groups. Something has to give. The same is true of Lakeside: because the base rate of repayment differs between the groups in its data, it cannot have both predictive parity and equal error rates.
The impossibility results do not mean fairness is hopeless. They mean that choosing a fairness definition is a moral choice, not a technical one, and that the choice should be made openly by people who understand what each definition protects. They also direct attention to the base rates themselves: if the difference in repayment rates reflects unequal opportunity, the best response may lie outside the model, for example in how loans are designed or how credit history is measured.
Choosing among definitions: what philosophy offers
Varga asks what each definition is protecting. Predictive parity protects the meaning of a decision: an approval or a high-risk label means the same thing whoever receives it, which matters to lenders and to judges who rely on the score. Equal opportunity protects qualified individuals from being wrongly denied because of their group, which matters most to applicants. Demographic parity protects groups from exclusion, regardless of differences in the data, which may be appropriate when those differences are themselves the product of injustice.
Theories of equality of opportunity help. A formal view says people should be judged on relevant qualifications without regard to group membership; it tends to favor calibration and equal treatment of equally scored people. A substantive view, associated with Rawls's fair equality of opportunity, says that people with similar talents and willingness should have similar prospects regardless of their starting point; it pays attention to how qualifications were acquired and may favor equal opportunity or even demographic parity. Luck egalitarians argue that people should not be worse off because of circumstances they did not choose, such as where they were born.
Philosophers also ask what makes discrimination wrong in the first place. Deborah Hellman argues that discrimination is wrong when it demeans people, treating them as less worthy of concern. Sophia Moreau argues that it is wrong when it denies people the freedom to make choices without having to take irrelevant traits into account. Others focus on harm, or on the way discrimination entrenches social hierarchy. These accounts matter for algorithms because some unequal outcomes may be wrongful even when no one intended them, and some differences in treatment may be justified, for example extra outreach to under-served groups.
The law of discrimination in the United States
The Equal Protection Clause of the Fourteenth Amendment limits government discrimination, but it generally requires proof of intent. Federal statutes go further. Title VII of the Civil Rights Act of 1964 prohibits employment discrimination, and in Griggs v. Duke Power Co. (1971) the Supreme Court held that it covers disparate impact: a neutral practice that disproportionately excludes a protected group is unlawful unless the employer shows it is job-related and consistent with business necessity. The Equal Credit Opportunity Act and the Fair Housing Act prohibit discrimination in lending and housing, and regulators have applied disparate impact analysis under them, although the use of disparate impact in federal enforcement has been narrowed since 2025.
Sabine points out a tension. Anti-discrimination law has traditionally been suspicious of using protected characteristics in decisions, yet some fairness techniques adjust a model's thresholds or training by group. Whether such adjustments are lawful depends on the jurisdiction and the context, and lawyers, regulators and philosophers are still working out the answer.
What fairness work looks like in practice
Fairness is not achieved by choosing a metric once. It is a practice that runs through the life of a system. Teams define the decision and its stakes; consult the people affected; examine whether the target variable measures what matters; collect demographic data for testing; measure several fairness metrics on representative data; decide, with reasons, which disparities are acceptable; try mitigations, such as better data, different targets or adjusted thresholds; and monitor outcomes after deployment, because data and populations change. Documentation, such as datasheets for data sets and model cards for models, records these choices so others can scrutinize them.
Worked problem
Auditing Lakeside
Using the code example, advise Lakeside's board on what to do about the gap between Group A and Group B.
Show solution
- State the finding plainly: the model satisfies predictive parity but creditworthy applicants in Group B are wrongly denied at 25 in 100, against 10 in 100 in Group A.
- Investigate causes: check whether features such as length of credit history or postal code act as proxies that disadvantage newcomers, and whether the repayment data reflects unequal past access to credit.
- Weigh options: lowering the threshold for Group B would equalize true positive rates but break predictive parity and raise legal questions; changing features, for example using rent and utility payment history, might narrow the gap for everyone.
- Decide openly: the board should choose which fairness definition matters most for lending, with reasons, and record the trade-off it accepts.
- Monitor: track approval and error rates by group every quarter and review the model if gaps widen.
Answer: Prioritize reducing wrongful denials of creditworthy Group B applicants, start with better features and data, and be transparent about the remaining trade-off.
Common mistakes
MistakeLeaving out race and sex makes a model fair.
InsteadProxies can reconstruct protected characteristics; leaving them out also makes unfairness harder to measure.
MistakeThere is one correct measure of fairness.
InsteadSeveral reasonable definitions exist, and when base rates differ they cannot all be satisfied.
MistakeIf a model is accurate, it is fair.
InsteadA model can be equally accurate overall and still deny qualified members of one group more often.
MistakeBias comes only from biased data.
InsteadIt can also come from the choice of target, from aggregation and from how the model is deployed.
Summary and key terms
- Bias can be historical, representational, measurement, aggregation or deployment bias.
- Predicting a proxy such as cost instead of need can build an existing inequality into a model.
- Fairness through unawareness fails because other variables act as proxies.
- Demographic parity, equal opportunity, equalized odds, predictive parity and calibration are common fairness definitions.
- When base rates differ, calibration and equal error rates cannot all hold; choosing among them is a moral choice.
- Title VII and other federal statutes recognize disparate impact, as held in Griggs.
- Proxy variable
- A variable that correlates with a protected characteristic and can stand in for it.
- Demographic parity
- Equal rates of positive decisions across groups.
- Equal opportunity
- Equal true positive rates across groups.
- Predictive parity
- Equal positive predictive value across groups, so a positive prediction means the same thing for each.
- Calibration
- For every score, the same chance of the outcome in each group.
- Base rate
- The share of a group for whom the outcome actually occurs.
Practice problems
Work each problem on paper first, then reveal the answer to check.
What did Obermeyer and colleagues find about the health care algorithm?
Show answer
By predicting cost instead of need, it judged Black patients healthier than equally sick white patients.
What did ProPublica and the COMPAS developer each claim?
Show answer
ProPublica showed unequal false positive rates; the developer showed the scores were calibrated.
In the code example, what are the true positive rates for the two groups?
Show answer
0.90 for Group A and 0.75 for Group B.
Why can the Lakeside model not satisfy both predictive parity and equal error rates?
Show answer
Because the base rate of repayment differs between the groups and the model is not perfect.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.