
CMPUT-450 · Lesson 5 of 12 · 35 min
Distributed transactions
A transaction groups several operations so that they take effect together or not at all. CMPUT-291 (lesson 10) covered transactions inside a single database: the ACID properties, locking, two-phase locking for serializability, and write-ahead logging for recovery. A single database can provide atomicity because it controls one log: a transaction commits at the instant its commit record reaches stable storage. When a transaction spans several machines, each with its own log, there is no single instant at which all of them commit. If one machine commits and another aborts, the system is left half-changed. This lesson covers the protocols that make several machines commit or abort together, explains why the classic protocol can block, and describes the alternatives that large systems use.
Ledgerline meets the problem as soon as it is split into services. Recording a payment touches the ledger, which stores balances; the invoice service, which marks the invoice paid; and the notification service, which sends a receipt. If the ledger records the payment but the invoice service crashes before marking the invoice, the customer is chased for a debt already paid. If the invoice is marked paid but the ledger never records the money, the books do not balance.
Atomic commitment
The problem of making a set of participants agree to commit or abort a transaction is called atomic commitment. A correct protocol must guarantee that all participants reach the same decision; that the decision is commit only if every participant voted to commit; that if every participant votes commit and nothing fails, the decision is commit; and that once a participant has decided, it never changes its decision. The participants are the resource managers holding the data, and one process, often the one that started the transaction, acts as coordinator.
Two-phase commit
Two-phase commit (2PC), formalized by Jim Gray in 1978 and used ever since in databases, transaction monitors and the X/Open XA standard, solves atomic commitment in two rounds of messages. In the prepare phase, the coordinator asks every participant whether it can commit. A participant that can commit makes its changes durable, holds its locks, writes a prepared record to its log, and replies YES; a participant that cannot replies NO and aborts locally. In the commit phase, the coordinator decides: COMMIT if every vote was YES, ABORT otherwise. It writes the decision to its own log, which is the instant the transaction's fate is sealed, and then sends the decision to every participant, which applies it, releases its locks and acknowledges.
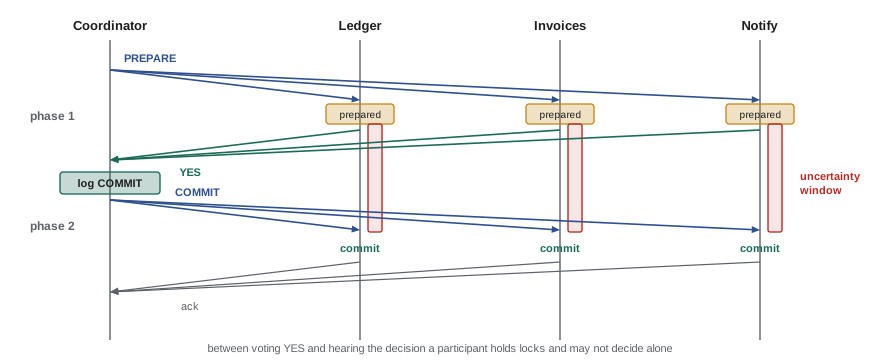
The crucial point is what a YES vote means. By voting YES a participant gives up its right to abort on its own: it has promised to commit if told to, even after a crash and restart, which is why it must write its changes and the prepared record to stable storage before replying. Between voting YES and hearing the decision, the participant is uncertain: it does not know whether the transaction will commit, and it may not unilaterally do either. If it aborted on its own, other participants might already have committed; if it committed on its own, the coordinator might have decided to abort because someone else voted NO.
# Two-phase commit, including the case that makes it a blocking protocol.
class Participant:
    def __init__(self, name, can_commit=True):
        self.name, self.can_commit, self.state = name, can_commit, "INIT"
    def prepare(self):
        # A YES vote is a promise: the participant must be able to commit later,
        # so it writes its changes and the vote to its log before replying.
        self.state = "PREPARED" if self.can_commit else "ABORTED"
        return self.can_commit
    def decide(self, decision):
        self.state = decision

def two_pc(parts, crash_after_votes=False):
    log = []
    votes = {p.name: p.prepare() for p in parts}
    log.append(f"phase 1 votes: {votes}")
    if crash_after_votes:
        log.append("coordinator crashes after collecting votes, before sending the decision")
        return log
    decision = "COMMITTED" if all(votes.values()) else "ABORTED"
    log.append(f"coordinator logs decision {decision} and tells everyone")
    for p in parts:
        if p.state == "PREPARED" or decision == "ABORTED":
            p.decide(decision)
    return log

for scenario in ("all yes", "one no", "coordinator crash"):
    parts = [Participant("ledger"), Participant("invoices", scenario != "one no"), Participant("notify")]
    for line in two_pc(parts, crash_after_votes=(scenario == "coordinator crash")):
        print(f"[{scenario}] {line}")
    print(f"[{scenario}] final states:", {p.name: p.state for p in parts})
    if scenario == "coordinator crash":
        blocked = [p.name for p in parts if p.state == "PREPARED"]
print(f"[{scenario}] blocked participants (holding locks, cannot decide alone): {blocked}")[all yes] phase 1 votes: {'ledger': True, 'invoices': True, 'notify': True}
[all yes] coordinator logs decision COMMITTED and tells everyone
[all yes] final states: {'ledger': 'COMMITTED', 'invoices': 'COMMITTED', 'notify': 'COMMITTED'}
[one no] phase 1 votes: {'ledger': True, 'invoices': False, 'notify': True}
[one no] coordinator logs decision ABORTED and tells everyone
[one no] final states: {'ledger': 'ABORTED', 'invoices': 'ABORTED', 'notify': 'ABORTED'}
[coordinator crash] phase 1 votes: {'ledger': True, 'invoices': True, 'notify': True}
[coordinator crash] coordinator crashes after collecting votes, before sending the decision
[coordinator crash] final states: {'ledger': 'PREPARED', 'invoices': 'PREPARED', 'notify': 'PREPARED'}
[coordinator crash] blocked participants (holding locks, cannot decide alone): ['ledger', 'invoices', 'notify']Why two-phase commit blocks
The third scenario shows the weakness of 2PC. If the coordinator crashes after participants have voted YES but before they learn the decision, the participants are stuck. Each one holds its locks, so other transactions that need the same rows wait too. A participant may ask the others what they know, and this helps in some cases: if any participant received COMMIT or ABORT, it can share it, and if any participant voted NO, everyone can abort. But if all participants voted YES and none heard the decision, they cannot proceed, because the coordinator may have logged COMMIT and told someone who has since crashed as well, or may have logged ABORT. They must wait for the coordinator to recover and read its log. This is why 2PC is called a blocking protocol.
In practice the blocking window is usually short, since coordinators restart quickly, but when it happens it is painful: locked rows can make a whole application stall, and database administrators sometimes have to resolve in-doubt transactions by hand, choosing commit or abort and accepting the risk of inconsistency. 2PC also has a performance cost: two round trips, several forced log writes, and locks held across the network for the whole protocol, so a slow participant slows everyone.
| Coordinator fails... | What participants know | Can they decide without the coordinator? |
|---|---|---|
| Before sending any PREPARE | Nothing; no one has voted | Yes: abort, because the transaction never prepared |
| After some votes, before a decision is logged | Some voted YES; maybe one voted NO | Only if someone voted NO (abort) or has not yet voted (it can vote NO) |
| After logging the decision, before sending it to all | Some may have received it | Only if a participant that received the decision is reachable |
| After sending the decision to everyone | All know the outcome | Yes; nothing is blocked |
Three-phase commit and its limits
Three-phase commit (3PC), proposed by Dale Skeen in 1981, adds a pre-commit round between the vote and the commit, so that no participant can commit until every participant knows that everyone voted YES. With that extra knowledge, survivors of a coordinator crash can always decide among themselves without blocking. The catch is its assumptions: 3PC is non-blocking only if the network is synchronous and failures are crashes that can be detected accurately. Under a network partition, two groups can reach different decisions, which violates atomicity, the one property no commit protocol may give up. Because real networks partition, 3PC is rarely used. The more robust approach, which modern systems take, is to make the coordinator itself fault tolerant by replicating its decision with consensus, so that a coordinator crash is survived by its replicas. Gray and Lamport described this combination as Paxos Commit in 2006, and it is essentially what Spanner does.
Distributed transactions in modern databases
Several modern systems provide serializable transactions across partitions and data centers. Google's Spanner (2012) runs two-phase commit across shards, but each shard is a Paxos-replicated group, so neither the coordinator nor any participant is a single machine that can block the protocol by crashing; TrueTime timestamps, from lesson 3, order transactions globally. Google's earlier Percolator (2010), built on Bigtable for incremental web indexing, implemented snapshot-isolation transactions with a client-driven two-phase commit, storing locks and write records as extra columns and using a timestamp oracle; TiDB adopted a similar design. CockroachDB and YugabyteDB, open-source descendants of Spanner's ideas, run transaction protocols over Raft-replicated ranges with hybrid logical clocks. The lesson these systems teach is that distributed transactions are practical when every component is itself replicated, so a single failure can delay a transaction but cannot block it indefinitely.
Sagas: giving up isolation for availability
Distributed transactions with locks held across services are unpopular in microservice architectures: they couple services tightly, lengthen lock hold times, and require every service to support the same commit protocol. The common alternative is the saga, an idea from a 1987 paper by Hector Garcia-Molina and Kenneth Salem on long-lived transactions. A saga is a sequence of local transactions, each committed independently in one service. For every step there is a compensating transaction that semantically undoes it. If a step fails, the saga runs the compensations for the steps already completed, in reverse order.
# A saga: a sequence of local transactions, each with a compensating action.
import random

def run_saga(steps, fail_at=None):
    done = []
    for i, (name, action, compensate) in enumerate(steps):
        if i == fail_at:
            print(f"  step {name!r} FAILED")
            for cname, _, comp in reversed(done):        # undo completed steps in reverse
                print(f"  compensate {cname!r}: {comp}")
            return "rolled back by compensation"
        print(f"  step {name!r}: {action}")
        done.append((name, action, compensate))
    return "completed"

steps = [
    ("reserve funds",  "hold 250.00 on the customer's card", "release the hold"),
    ("record payment", "append payment p-901 to the ledger", "append refund r-901 (never delete p-901)"),
    ("mark invoice",   "set invoice 812 to PAID",           "set invoice 812 back to OPEN"),
    ("send receipt",   "email the receipt",                  "email a correction notice"),
]
print("happy path:");   print(" ->", run_saga(steps))
print("failure at step 4 (send receipt):"); print(" ->", run_saga(steps, fail_at=3))happy path: step 'reserve funds': hold 250.00 on the customer's card step 'record payment': append payment p-901 to the ledger step 'mark invoice': set invoice 812 to PAID step 'send receipt': email the receipt -> completed failure at step 4 (send receipt): step 'reserve funds': hold 250.00 on the customer's card step 'record payment': append payment p-901 to the ledger step 'mark invoice': set invoice 812 to PAID step 'send receipt' FAILED compensate 'mark invoice': set invoice 812 back to OPEN compensate 'record payment': append refund r-901 (never delete p-901) compensate 'reserve funds': release the hold -> rolled back by compensation
Sagas trade isolation for availability and loose coupling. Between steps, other transactions can see intermediate states, such as a payment recorded but an invoice still open, so the application must be designed to tolerate them, for example by marking records as pending. Compensations must be possible and themselves reliable: you cannot unsend an email, so the compensation sends a correction; and an accounting ledger never deletes entries, so the compensation appends a reversing entry. Sagas can be orchestrated, with a central coordinator telling each service what to do next and tracking progress durably, or choreographed, with each service reacting to events published by the previous one. Workflow engines such as Temporal, AWS Step Functions and Camunda are widely used to run orchestrated sagas reliably, persisting their progress so a crash of the orchestrator resumes rather than restarts the saga.
| Approach | Atomicity | Isolation | Availability during failures | Typical use |
|---|---|---|---|---|
| Two-phase commit (single coordinator) | Yes | Yes, with locks | Blocks if the coordinator fails at the wrong moment | XA transactions across databases or queues |
| 2PC over consensus-replicated groups | Yes | Yes (serializable or snapshot) | Survives minority failures in every group | Spanner, CockroachDB, YugabyteDB |
| Saga | Eventually, through compensation | No; intermediate states are visible | High; each step is local | Microservice workflows, bookings, payments |
| Single-partition design | Yes, locally | Yes, locally | High | Data modeled so each transaction touches one partition |
The transactional outbox
A related problem arises whenever a service must update its database and publish a message, for example recording a payment and emitting a PaymentRecorded event for other services. Doing the two separately risks one succeeding without the other, and putting both under 2PC requires the message broker to take part in the protocol. The transactional outbox pattern avoids this: the service writes the event into an outbox table in the same local transaction as the business change, and a separate relay process reads the outbox and publishes the events, retrying until the broker acknowledges. Delivery is at least once, so consumers deduplicate by event identifier, using the techniques of lesson 2. Change data capture tools such as Debezium implement the relay by reading the database's own log.
Avoiding distributed transactions
The best distributed transaction is often the one you do not need. Data can frequently be partitioned so that each transaction touches one partition: Ledgerline keeps all of a business's accounts, invoices and ledger entries in the same partition, keyed by business, so recording a payment is a local transaction. Operations can sometimes be restructured to be commutative, so replicas can apply them in any order (lesson 7). And many business processes already tolerate brief inconsistency, provided it is eventually resolved and never silently lost. Pat Helland's essay Life Beyond Distributed Transactions (2007) argued that very large systems must be designed around entities that are updated atomically one at a time, with messages and idempotent processing between them.
Worked examples
Worked problem
Who can decide?
Three participants P, Q and R and a coordinator run 2PC. P and Q voted YES; R has not yet received PREPARE. The coordinator crashes. What should P, Q and R do?
Show solution
- R has not voted, so it can still vote NO, or simply abort on its own.
- Because R has not voted YES, the coordinator cannot have decided COMMIT.
- P and Q, learning from R that it has not voted, can safely abort.
Answer: All three abort; blocking occurs only when every participant has voted YES and none knows the decision.
Worked problem
Counting the cost of 2PC
A transaction spans 4 participants in other data centers, each 30 ms round trip from the coordinator. Forced log writes take 2 ms. Estimate the commit latency, ignoring processing time.
Show solution
- Phase 1: send PREPARE and receive votes in parallel: one 30 ms round trip, plus each participant's forced prepared-record write (2 ms, in parallel).
- Coordinator forces its decision record: 2 ms.
- Phase 2: send the decision; the transaction is committed once the decision is logged, but locks are released only when participants receive it: about 15 ms one way.
- Total until the decision: \(30 + 2 + 2 = 34\) ms; until locks are released: about 49 ms.
Answer: About 34 ms to decide and roughly 49 ms of lock holding at the participants, every time, even with no failures.
Worked problem
Designing compensations
A Ledgerline saga: (1) reserve inventory, (2) charge the card, (3) create a shipping label, (4) send confirmation. Give a compensation for each and say which steps are hard to undo.
Show solution
- (1) Release the reserved inventory.
- (2) Refund the charge; this is a new transaction, not a deletion, and may take days to reach the customer.
- (3) Void the label with the carrier, if done before pickup; afterwards, a return process is needed.
- (4) Send a cancellation notice; an email cannot be unsent.
Answer: Each step needs a semantic undo; steps with external side effects (charges, shipments, emails) can only be offset, so order the saga to put hard-to-undo steps last.
Common mistakes
MistakeLet a participant abort on its own after voting YES because the coordinator is slow.
InsteadA YES vote is a promise; the participant must wait for, or find out, the decision.
MistakeUse 3PC to avoid blocking on real networks.
Instead3PC can violate atomicity under partitions; replicate the coordinator with consensus instead.
MistakeUpdate a database and publish an event as two independent steps.
InsteadUse a transactional outbox, or change data capture, so both happen or neither does.
MistakeImplement saga compensation by deleting records.
InsteadCompensate semantically, for example with a reversing ledger entry, keeping an audit trail.
MistakeAssume sagas provide isolation.
InsteadIntermediate states are visible; design for them with pending states and idempotent steps.
Summary and key terms
- Atomic commitment makes every participant in a transaction commit or abort together.
- Two-phase commit collects votes, then logs and distributes a decision; a YES vote is a durable promise to commit if told to.
- If the coordinator fails after all participants vote YES, 2PC blocks: participants hold locks until the decision is known.
- Three-phase commit avoids blocking only under synchronous, partition-free assumptions; modern systems replicate the coordinator with consensus instead.
- Spanner, CockroachDB and YugabyteDB run commit protocols over consensus-replicated groups, so single failures do not block transactions.
- Sagas replace one atomic transaction with local steps and compensations, trading isolation for availability and loose coupling.
- The transactional outbox ties a database change and a published event together; partitioning data well avoids many distributed transactions altogether.
- Atomic commitment
- The problem of getting all participants of a transaction to commit or all to abort.
- Two-phase commit
- An atomic commitment protocol with a voting phase and a decision phase.
- Coordinator
- The process that collects votes and decides the outcome in a commit protocol.
- Prepared state
- A participant's durable promise to commit if instructed, entered when it votes YES.
- Blocking protocol
- A protocol in which a failure can leave correct processes unable to proceed until it is repaired.
- In-doubt transaction
- A prepared transaction whose outcome a participant does not know.
- Three-phase commit
- A commit protocol with an extra pre-commit round that avoids blocking under synchronous assumptions.
- Saga
- A sequence of local transactions with compensating actions that undo completed steps on failure.
- Compensating transaction
- A transaction that semantically reverses the effect of an earlier one.
- Transactional outbox
- A pattern that records outgoing messages in the same local transaction as the business change.
Practice problems
Work each problem on paper first, then reveal the answer to check.
What must a participant do before replying YES in 2PC?
Show answer
Make its changes and a prepared record durable, and keep holding its locks.
At what moment is a 2PC transaction's outcome decided?
Show answer
When the coordinator writes the decision to its log.
All participants voted YES and the coordinator crashed. Why can they not simply commit?
Show answer
The coordinator may have decided ABORT, for example after a timeout, and told a participant that has since crashed.
Why is 3PC rarely used in practice?
Show answer
It assumes synchronous communication and accurate failure detection; under partitions it can violate atomicity.
How does Spanner avoid 2PC blocking?
Show answer
Each coordinator and participant is a Paxos-replicated group, so one machine's crash does not lose the decision.
What is a compensating transaction for "append payment p-901"?
Show answer
Append a reversing refund entry; never delete the original entry.
What is the difference between orchestrated and choreographed sagas?
Show answer
A central orchestrator directs orchestrated sagas; choreographed sagas proceed by services reacting to each other's events.
Why do consumers of an outbox relay need deduplication?
Show answer
The relay may publish an event more than once if it crashes after publishing and before marking it sent.
How can partitioning avoid distributed transactions?
Show answer
By placing all data a transaction needs, such as one business's records, in the same partition.
Which property do sagas give up?
Show answer
Isolation: intermediate states are visible to other transactions.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.