
AI-499 · Lesson 5 of 12 · 25 min
Baselines, experiment design and reproducibility
Once the problem is framed and the data split, the temptation is to reach straight for the most powerful model available. Experienced practitioners do the opposite: they build simple baselines first, set up a reliable experiment process, and only then add complexity, measuring at each step whether it helps. Baselines show how hard the problem is, catch bugs in data and evaluation code, and give context for later results: a sophisticated model that barely beats a majority-class predictor is not a success. This lesson covers the kinds of baselines to build, designing experiments that answer clear questions, ablation studies, hyperparameter search, comparing results with appropriate statistics, tracking experiments, and making results reproducible.
Kinds of baselines
A good baseline report includes several levels:
- Trivial baselines: predicting the majority class, the mean value, the most recent value for forecasting, or random ranking. These set the floor and often reveal how imbalanced or easy a task is.
- Heuristic and rule-based baselines: the current process, simple rules suggested by domain experts, keyword matching or regular expressions for text, or template matching for documents.
- Simple learned models: logistic or linear regression, decision trees, gradient-boosted trees on tabular data, or nearest-neighbor methods; for text, bag-of-words models; for images, a small pretrained network used as a fixed feature extractor.
- Off-the-shelf pretrained models: an existing model applied with no or minimal adaptation, such as a general-purpose large language model with a simple prompt, or an existing image classifier.
Each baseline should be run through the same evaluation code on the same splits as the final model. On tabular data, gradient-boosted trees are often hard to beat, and many projects find that the simplest well-tuned learned model gets most of the way to the best result.
Designing experiments
An experiment should answer a specific question, such as "does adding the supplier history features improve recall?" or "does fine-tuning beat prompting for this extraction task?". Write down the question, the hypothesis, what will be changed, what will be held fixed, the metric used to judge the result, and what result would change the team's plan, before running it. Changing several things at once makes results uninterpretable. Experiments should be ordered by expected value: those likely to produce large improvements cheaply first, and expensive speculative ideas later or as stretch goals.
Ablation studies
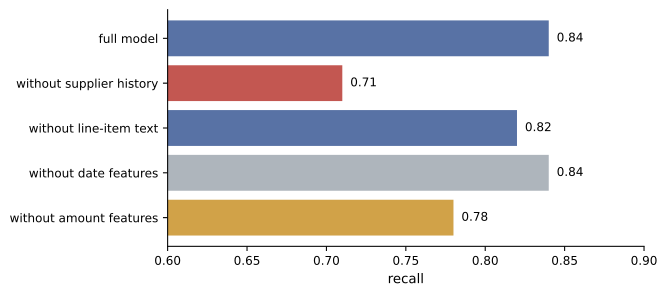
An ablation study removes or replaces one component of a system at a time to measure its contribution. If a model uses five feature groups, an ablation trains five variants, each without one group, and compares them with the full model. Ablations show which components matter, simplify systems by revealing parts that add nothing, and make results more convincing to reviewers. In language model systems, ablations might compare prompts with and without examples, retrieval with and without re-ranking, or different chunk sizes for documents.
| Variant | Recall | Precision | Interpretation |
|---|---|---|---|
| Full model | 0.84 | 0.61 | Reference |
| Without supplier history | 0.71 | 0.55 | History is the most important feature group |
| Without text of line items | 0.82 | 0.60 | Small contribution |
| Without date features | 0.84 | 0.61 | No contribution: candidate for removal |
| Without amount features | 0.78 | 0.58 | Moderate contribution |
Hyperparameter search
Hyperparameters, such as learning rate, regularization strength, tree depth or the number of retrieved documents, must be chosen using validation data. Grid search tries every combination of a few values and becomes expensive quickly; random search samples combinations and usually finds good settings faster, because only a few hyperparameters typically matter; and Bayesian optimization uses the results so far to choose promising settings next. Practical advice: tune the most important hyperparameters first, such as the learning rate for neural networks; use sensible ranges on logarithmic scales for rates and regularization; set a compute budget in advance; and give baselines a fair amount of tuning too, since comparing a heavily tuned new model with an untuned baseline exaggerates the gain.
Is the difference real?
Evaluation metrics are estimates with uncertainty, because they are computed on a finite sample. A difference of one or two percentage points between two models may be noise. Two complementary checks help. First, a confidence interval for the difference between models on the same test examples, which can be estimated with a paired bootstrap: resample the test examples with replacement many times, compute the difference each time, and take the middle 95 % of the results. Second, variation across training runs: neural networks trained with different random seeds give different results, so report the mean and spread over several seeds for the final comparison.
import numpy as np
# Comparing a model with a baseline using a paired bootstrap confidence interval
rng = np.random.default_rng(3)
n = 800
truth = rng.random(n) < 0.3
baseline = np.where(rng.random(n) < 0.78, truth, ~truth)   # about 78 % accurate
model = np.where(rng.random(n) < 0.82, truth, ~truth)      # about 82 % accurate
acc_b, acc_m = np.mean(baseline == truth), np.mean(model == truth)
diffs = []
for _ in range(5000):
    i = rng.integers(0, n, n)
    diffs.append(np.mean(model[i] == truth[i]) - np.mean(baseline[i] == truth[i]))
lo, hi = np.percentile(diffs, [2.5, 97.5])
print(f"baseline {acc_b:.3f}, model {acc_m:.3f}, difference {acc_m - acc_b:+.3f}")
print(f"95 % bootstrap interval for the difference: [{lo:+.3f}, {hi:+.3f}]")
print("improvement is", "reliable" if lo > 0 else "not yet distinguishable from noise")
# Seeds matter: the same training recipe run five times
runs = 0.80 + rng.normal(0, 0.012, 5)
print("five seeds:", np.round(runs, 3), f"mean {runs.mean():.3f} +/- {runs.std(ddof=1):.3f}")baseline 0.761, model 0.825, difference +0.064 95 % bootstrap interval for the difference: [+0.025, +0.105] improvement is reliable five seeds: [0.814 0.772 0.797 0.805 0.8 ] mean 0.798 +/- 0.016
Here the model improves on the baseline by about 6 points, and the bootstrap interval excludes zero, so the improvement is unlikely to be noise. The five-seed run shows a spread of about 1.6 points between identical training recipes, a reminder that differences smaller than the seed variation should not be reported as improvements. Lesson 8 covers statistical evaluation in more depth.
Tracking experiments
Over a term, a team may run hundreds of experiments. Without tracking, results are forgotten, duplicated or impossible to reproduce. Every run should record the code version (for example the Git commit), the data version and split, the configuration and hyperparameters, the random seed, the environment (library versions and hardware), the metrics on validation data and links to saved models and outputs. Experiment tracking tools, from a shared spreadsheet to open-source platforms such as MLflow, make this routine. A brief weekly summary of what was tried, what was learned and what comes next keeps the whole team aligned and becomes the raw material for the final report.
Reproducibility
A result is reproducible when someone else can run the same code on the same data and obtain the same result, within the expected random variation. Reproducibility requires fixed and recorded random seeds; pinned library versions, for example in a requirements file or container image; scripts rather than manual steps for data processing, training and evaluation; versioned data or documented data access steps; and a README explaining how to run everything from scratch. Some sources of non-determinism, such as parallel GPU operations, are hard to eliminate, so record the expected variation. Programs often require a final "fresh clone" test: a team member who did not write the code reproduces the main results following only the documentation.
Worked problem
Planning an experiment
A team building a support-ticket classifier has a TF-IDF and logistic regression baseline with macro F1 of 0.71. They want to try fine-tuning a small pretrained transformer. Write the experiment plan.
Show solution
- Question: does fine-tuning a small pretrained transformer improve macro F1 over the baseline on the validation set?
- Hypothesis: yes, by at least 5 points, because tickets contain paraphrases the bag-of-words model misses.
- Held fixed: data split, label set, evaluation script, maximum training budget of 4 GPU-hours.
- Varied: model (baseline vs transformer); tune learning rate over three values and run three seeds of the best.
- Decision rule: adopt the transformer if mean macro F1 improves by at least 3 points with a bootstrap interval excluding zero and latency stays under 100 ms; otherwise keep the baseline and improve features.
Answer: A plan with a question, hypothesis, fixed and varied factors, budget and a decision rule agreed before running.
Avoiding common traps
Several traps catch capstone teams. Comparing a new model on a different split or metric from the baseline makes results meaningless. Reporting the best of many runs, rather than the typical result, overstates performance. Tuning indefinitely on validation data overfits it, so a limited number of design iterations should be planned. Ignoring training and inference cost can lead to a model that is marginally better but too slow or expensive to deploy. And running experiments without writing down why makes the final report hard to write; the decision log from Lesson 1 should record every significant experiment and its conclusion.
Baselines for LLM projects
Projects using large language models need baselines too. Useful baselines include a simple keyword or rule-based system; a classical model such as logistic regression on TF-IDF features for classification tasks; a zero-shot prompt to a capable model with no examples or retrieval; and the same prompt with a smaller, cheaper model. Comparing against these shows whether added complexity, such as retrieval, few-shot examples, agents or fine-tuning, earns its cost. It is common to find that a well-written prompt to a strong model already performs well, and that the main remaining gains come from better retrieval or evaluation data rather than more elaborate prompting.
Budgeting compute
Compute is a finite resource for capstone teams, whether it comes from program clusters, cloud credits or API budgets. Estimate the cost of planned experiments in advance, such as GPU-hours for fine-tuning runs or tokens for evaluation sets, and track spending weekly. Use small-scale experiments to choose promising directions before scaling up, reuse cached results where possible, and stop runs that are clearly failing. Running out of budget in the final weeks is a common and avoidable crisis.
Collaborating on experiments
When several team members run experiments, coordination prevents duplicated or conflicting work. Assign owners to experiment directions, share results in a common tracker, review each other's configurations before long runs, and hold short weekly meetings to decide which directions to continue. A shared evaluation script, used by everyone and changed only through code review, ensures that results are comparable.
Reading results critically
When an experiment produces a result, ask several questions before accepting it. Is the evaluation code correct, and was it run on the right split? Is the improvement larger than run-to-run variation? Does it hold across slices, or only overall? Could the change have introduced leakage, for example through a new feature? Is the gain worth its cost in complexity, latency or compute? A short written answer to these questions for each significant experiment makes the final report much easier to write and much more convincing to reviewers.
Simple baselines that surprise
Simple baselines regularly turn out to be strong. In text classification, a linear model on word counts often comes within a few points of a fine-tuned transformer. In forecasting, predicting the same value as last week or last year is often hard to beat. In recommendation, recommending the most popular items performs surprisingly well. These results are not failures; they tell the team where the real difficulty lies and protect against overclaiming.
Common mistakes
MistakeStarting with the most complex model.
InsteadBuild trivial, heuristic and simple learned baselines first.
MistakeChanging several things in one experiment.
InsteadChange one factor and hold others fixed.
MistakeTuning the new model but not the baseline.
InsteadGive baselines fair tuning.
MistakeReporting single-run differences smaller than seed variation.
InsteadReport means, spreads and confidence intervals.
MistakeNot recording configurations and versions.
InsteadTrack every run and pin environments.
Summary and key terms
- Baselines set the floor, catch bugs and give context.
- Use trivial, heuristic, simple learned and off-the-shelf baselines.
- Experiments answer one question with a pre-stated decision rule.
- Ablations measure the contribution of each component.
- Random search and Bayesian optimization tune hyperparameters efficiently.
- Paired bootstrap intervals and multiple seeds show whether differences are real.
- Track experiments and make results reproducible from scratch.
- Baseline
- Simple reference model or rule.
- Majority-class baseline
- Always predicting the most common class.
- Ablation
- Removing a component to measure its effect.
- Hyperparameter
- Setting chosen before training.
- Random search
- Sampling hyperparameter combinations.
- Bayesian optimization
- Using past results to choose new settings.
- Paired bootstrap
- Resampling test items to estimate uncertainty in a difference.
- Random seed
- Value controlling random number generation.
- Experiment tracking
- Recording configurations and results of runs.
- Reproducibility
- Ability to obtain the same results again.
Practice problems
Work each problem on paper first, then reveal the answer to check.
Name three kinds of baseline.
Show answer
Trivial, heuristic or rule-based, simple learned, off-the-shelf pretrained.
Why run baselines through the same evaluation code?
Show answer
So comparisons are valid and bugs are caught.
What should be written before an experiment?
Show answer
Question, hypothesis, fixed and varied factors, metric, decision rule.
What does an ablation reveal?
Show answer
Each component's contribution.
Why is random search often better than grid search?
Show answer
Few hyperparameters matter, so sampling explores them more.
What does a paired bootstrap estimate?
Show answer
A confidence interval for the difference between models.
Why run several seeds?
Show answer
To measure run-to-run variation.
Name four things to record for each run.
Show answer
Code version, data version, configuration, seed, environment, metrics.
What is a fresh clone test?
Show answer
Reproducing results from documentation alone.
Why limit validation design iterations?
Show answer
To avoid overfitting the validation set.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.