
ROB-410 · Lesson 11 of 12 · 30 min
Foundation models and vision-language-action policies
In language and vision, a single large model pretrained on vast data and then adapted to many tasks, a foundation model, has replaced most narrow task-specific models. Robotics is attempting the same shift. Since 2022 a series of systems has trained large policies on demonstrations from many robots and tasks, often starting from vision-language models pretrained on internet data, so that one network can follow natural-language instructions such as 'put the apple in the drawer' across many scenes. These are called vision-language-action models, or VLAs. This lesson explains how they are built, surveys the main systems at the time of writing (October 2026), and, just as importantly, teaches how to evaluate their claims critically. The field moves very quickly; treat specific model names and numbers as a snapshot and the principles as the lasting content.
From task policies to generalist policies
The policies of lessons 8 to 10 are specialists: one task, one robot, one lab, typically tens to hundreds of demonstrations. A generalist policy aims to handle many tasks, objects and scenes, conditioned on an instruction, and ideally more than one robot body. Three ideas make this plausible. Scale: pooling data from many tasks lets common skills, such as reaching and grasping, be learned once. Transfer from the internet: vision-language models already know what an apple or a drawer looks like and what 'put in' means. Shared action interfaces: if actions from different robots can be expressed in a common form, data from one robot can help another.
| System (year) | Developer | Key idea | Openness |
|---|---|---|---|
| RT-1 (2022) | Transformer policy trained on about 130,000 real demonstrations across 700+ tasks | Paper; code released | |
| RT-2 (2023) | Google DeepMind | Vision-language model fine-tuned to output actions as text tokens | Paper only |
| Open X-Embodiment and RT-X (2023) | Collaboration of over 20 institutions | Pooled dataset of over 1 million episodes from 22 robot types | Dataset released |
| Octo (2024) | Academic collaboration | Transformer with diffusion action head trained on Open X-Embodiment data | Open weights |
| OpenVLA (2024) | Academic collaboration | 7-billion-parameter VLA built on a Llama 2 language model | Open weights |
| π0 and successors (2024 onward) | Physical Intelligence | VLM backbone with a flow-matching action expert for dexterous control | Some models released through openpi |
| GR00T N1 (2025) | NVIDIA | Foundation model aimed at humanoid robots | Open weights |
| Gemini Robotics (2025) | Google DeepMind | VLA built on the Gemini model family | Limited access |
Anatomy of a vision-language-action model
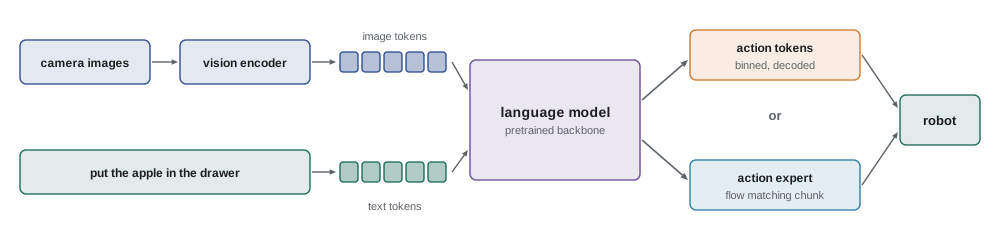
Most VLAs share a common structure. A vision encoder, often a pretrained model such as SigLIP or DINOv2, turns camera images into a sequence of visual tokens. A language model backbone, pretrained on internet text and image-text pairs, processes the visual tokens together with the instruction's text tokens. An action output component turns the backbone's final representations into robot actions. The output component is where designs differ most.
The first approach, used by RT-2 and OpenVLA, treats actions as language. Each continuous action dimension is discretized into a fixed number of bins, often 256, and each bin is mapped to a token in the language model's vocabulary. The model then predicts actions exactly as it predicts words, with the same next-token training objective. This reuses the language model unchanged but limits precision to the bin width and produces one action at a time slowly.
# Action tokenization: map continuous actions to 256 bins and back
import numpy as np
rng = np.random.default_rng(11)
low, high, bins = -1.0, 1.0, 256
edges = np.linspace(low, high, bins + 1)
centers = 0.5 * (edges[:-1] + edges[1:])
def tokenize(a):
    return np.clip(np.digitize(a, edges) - 1, 0, bins - 1)
def detokenize(tok):
    return centers[tok]
actions = rng.uniform(-1, 1, size=(1000, 7))         # 7-D arm actions, normalized
tokens = tokenize(actions)
recon = detokenize(tokens)
err = np.abs(recon - actions)
print("example action :", np.round(actions[0], 3))
print("tokens         :", tokens[0])
print("reconstructed  :", np.round(recon[0], 3))
print(f"bin width {(high - low) / bins:.4f}, max error {err.max():.4f}, mean error {err.mean():.4f}")example action : [-0.743 -0.001 0.203 -0.943 -0.704 0.856 -0.859] tokens : [ 32 127 153 7 37 237 18] reconstructed : [-0.746 -0.004 0.199 -0.941 -0.707 0.855 -0.855] bin width 0.0078, max error 0.0039, mean error 0.0020
The second approach attaches a continuous action head. Octo uses a small diffusion head; the π0 family adds a separate action expert network trained with flow matching, a close relative of the diffusion objective in lesson 9, which outputs chunks of continuous actions at high rates suitable for dexterous tasks such as folding laundry. Continuous heads give finer precision and smoother motion, and they combine the semantic knowledge of the backbone with the multimodal action modelling of generative policies.
Worked problem
Precision of binned actions
An arm's end-effector translation per step is normalized so that \( [-1, 1] \) corresponds to \( \pm 2 \) cm. With 256 bins, what is the worst-case quantization error per step in millimetres? Is it acceptable for inserting a peg with 0.5 mm clearance?
Show solution
- Range is 4 cm = 40 mm across 256 bins, so a bin is \( 40 / 256 \approx 0.156 \) mm wide.
- Worst-case error is half a bin, about 0.078 mm per step.
- Errors per step can accumulate or be corrected by feedback; the quantization alone is small relative to 0.5 mm, but sensing and calibration errors usually dominate.
Answer: About 0.08 mm per step, small compared with the clearance; quantization is rarely the limiting factor, though slow token-by-token decoding can be.
Data: Open X-Embodiment and cross-embodiment learning
Foundation models need foundation-scale data, and robot data is scarce compared with internet text. The Open X-Embodiment project, announced in 2023, pooled existing datasets from many labs into a common format, reporting over a million episodes from 22 robot embodiments. Models trained on the mixture, called RT-X, performed better on several robots than models trained only on each robot's own data, which was early evidence that cross-embodiment pooling helps. Other large collections followed, such as DROID, gathered with a common platform across many institutions and scenes, and companies building generalist policies now collect large proprietary datasets, often thousands of hours of teleoperation.
Cross-embodiment learning is hard because robots differ in kinematics, grippers, camera placement, control rates and action spaces. Common strategies include normalizing actions per dataset, expressing actions in the end-effector frame, padding to a maximum action dimension with masks, using separate output heads per embodiment, and weighting datasets to prevent the largest from dominating. Data quality varies widely across pooled datasets, and careful curation often matters as much as volume.
Worked problem
Weighting a data mixture
A pretraining mixture has three datasets: A with 600,000 episodes from one robot in one lab, B with 80,000 episodes across 50 scenes, and C with 20,000 episodes of dexterous bimanual tasks. Sampling proportionally to size, what fraction of training samples comes from each? Why might a team reweight?
Show solution
- Total 700,000 episodes: A is 85.7 %, B 11.4 %, C 2.9 %.
- The model would mostly see one lab's robot and scenes, which limits diversity.
- Teams often upweight diverse or rare-skill data, for example to 50 %, 30 % and 20 %, and check that performance on A does not collapse.
Answer: Proportional sampling gives about 86 %, 11 % and 3 %; reweighting improves diversity and coverage of rare skills.
Adapting foundation models
Even the strongest generalist policies, at the time of writing, rarely work out of the box on a new robot or task at the reliability a deployment needs. The usual workflow is to fine-tune: collect tens to hundreds of demonstrations on the target robot and task, and continue training the pretrained model on them, sometimes alongside some of the pretraining mixture to avoid forgetting. Parameter-efficient methods such as low-rank adaptation, LoRA, train small added matrices rather than all weights, which cuts memory and lets one base model support many adapted versions. The promise of foundation models in practice is often that they need fewer task demonstrations and generalize better to new objects and scenes than a policy trained from scratch, rather than that they need no task data at all.
# Fine-tuning an open VLA with LoRA (listing only; library APIs change often)
from transformers import AutoModelForVision2Seq, AutoProcessor
from peft import LoraConfig, get_peft_model
model = AutoModelForVision2Seq.from_pretrained("openvla/openvla-7b", torch_dtype="bfloat16")
processor = AutoProcessor.from_pretrained("openvla/openvla-7b")
lora = LoraConfig(r=32, lora_alpha=16, target_modules="all-linear", lora_dropout=0.0)
model = get_peft_model(model, lora)
model.print_trainable_parameters()       # a small fraction of the 7B weights
for batch in loader:                      # images, instruction text, tokenized actions
    out = model(**batch)                 # next-token loss over action tokens
out.loss.backward(); optimizer.step(); optimizer.zero_grad()| Choice | Option A | Option B | Considerations |
|---|---|---|---|
| Action output | Discrete tokens | Continuous head (diffusion or flow) | Precision, speed, multimodality |
| Adaptation | Full fine-tuning | LoRA or adapters | Compute, memory, number of task variants |
| Deployment compute | On-robot GPU | Remote server | Latency, network reliability, privacy |
| Model size | Large backbone, billions of parameters | Small specialist policy | Generalization against speed and cost |
| Control rate | Low rate with chunking | High-rate low-level controller beneath | Smoothness and safety |
Evaluating claims critically
Robot foundation models are announced with impressive videos and headline success rates. A careful engineer reads them the way a scientist reads any experimental claim. Several questions help.
First, how many trials, and what are the confidence intervals? A success rate of 90 % from 20 trials has a 95 % interval running from about 70 % to 97 %, so differences of a few points between models are often meaningless; lesson 12 shows how to compute this. Second, what was held out? Performance on objects, scenes and instructions seen in training says little about generalization; look for explicit unseen-object, unseen-scene and unseen-instruction splits. Third, who ran the evaluation, and were baselines given equal effort in tuning and data? Fourth, are the videos representative, or selected best runs? Fifth, what are the failure modes, and how does the policy behave when it fails: does it stop, retry or do something dangerous? Sixth, what are the compute and latency requirements, and can the model run on the target robot? Finally, can the result be reproduced: are weights, code and evaluation protocols available?
Standardized evaluation is an active research topic. Simulated benchmarks such as LIBERO and SIMPLER give reproducible comparisons but do not fully predict real performance. Real-world evaluation across labs, with shared protocols and blind comparisons, is more convincing and much more expensive. At the time of writing, there is no agreed benchmark that settles which generalist policy is best, and claims of general-purpose capability should be read as claims about specific tested conditions.
Worked problem
Reading a model announcement
A company reports that its new model achieves 94 % success on household tasks, compared with 81 % for a competitor, with a highlight video. The fine print says 50 trials per model on tasks drawn from the training distribution, evaluated by the company. List the main questions you would ask before relying on this.
Show solution
- Uncertainty: with 50 trials, the 95 % intervals are roughly 84 % to 98 % and 68 % to 89 %; the difference is likely real but its size is uncertain.
- Generalization: the tasks come from the training distribution, so the result says little about new homes, objects or instructions.
- Fairness: was the competitor fine-tuned on the same data and tuned with equal effort by the same team?
- Representativeness and failures: what happened in the failed trials, and are videos typical runs?
- Practicality and reproducibility: compute needs, latency, availability of weights and protocols.
Answer: Treat the result as evidence of in-distribution improvement under the company's conditions; seek held-out, independent and reproducible evaluation before relying on it.
Limits and open problems
Despite rapid progress, robot foundation models at the time of writing face real limits. Data is still orders of magnitude smaller than for language models, and collecting it is slow and expensive. Precision and reliability lag behind what industrial deployment requires: a success rate of 90 % is impressive in research but unacceptable for a production line that needs 99.9 %. Long-horizon tasks, tasks needing memory and contact-rich assembly remain difficult. Large models are slow and power-hungry for on-robot use. Language understanding can create a false impression of general competence. And safety assurance for a large learned policy, whose behaviour cannot be exhaustively specified or verified, is unsolved; lesson 12 discusses practical layers of protection. Treat foundation models as a powerful new tool for building robot behaviour, especially for perception and flexible manipulation, combined with classical control and safety engineering rather than replacing them.
Common mistakes
MistakeBelieving a VLA works on any robot and task out of the box.
InsteadExpect to fine-tune on target-robot demonstrations and verify performance on the real task.
MistakeComparing models by headline success rates from small trial counts.
InsteadCompute confidence intervals and check whether the tasks were held out.
MistakeJudging capability from highlight videos.
InsteadAsk for failure rates, failure modes and representative, unedited runs.
MistakePooling datasets without normalization or weighting.
InsteadNormalize actions per dataset, align frames and reweight to balance diversity.
MistakeLetting a large model command motors directly without safeguards.
InsteadRun it above a low-level controller with limits, monitoring and a safety layer.
Summary and key terms
- Foundation models pretrain one large model on broad data and adapt it to many tasks.
- VLAs combine a vision encoder, a pretrained language backbone and an action output.
- Actions are output either as discrete tokens or by a continuous diffusion or flow head.
- Open X-Embodiment pooled data from many robots and showed cross-embodiment benefits.
- Fine-tuning, often with LoRA, adapts a generalist model to a specific robot and task.
- Claims should be judged by trial counts, intervals, held-out splits, fairness and reproducibility.
- Data scale, reliability, speed and safety assurance remain open problems at the time of writing.
- Foundation model
- A large model pretrained on broad data and adapted to many tasks.
- Vision-language-action model
- A policy that maps images and language instructions to robot actions.
- Generalist policy
- A policy intended to handle many tasks, objects and scenes.
- Action tokenization
- Discretizing continuous actions into bins represented as tokens.
- Action expert
- A separate network that produces continuous actions from backbone features.
- Flow matching
- A generative training method that learns a velocity field from noise to data.
- Cross-embodiment learning
- Training one policy on data from robots with different bodies.
- Open X-Embodiment
- A pooled multi-robot dataset assembled by a collaboration of labs.
- LoRA
- Low-rank adaptation, fine-tuning small added matrices instead of all weights.
- Held-out evaluation
- Testing on objects, scenes or instructions not seen in training.
Practice problems
Work each problem on paper first, then reveal the answer to check.
What are the three main parts of a typical VLA?
Show answer
Vision encoder, language model backbone and action output.
With 256 bins over \( [-1,1] \), what is the bin width?
Show answer
\( 2/256 \approx 0.0078 \).
Name one advantage of a continuous action head over tokens.
Show answer
Finer precision, smoother motion or multimodal chunks at high rate.
What did RT-X results suggest about pooling data?
Show answer
Cross-embodiment data can improve performance over single-robot data.
Why reweight a pretraining mixture?
Show answer
To keep large, narrow datasets from dominating and to cover rare skills.
What does LoRA train?
Show answer
Small low-rank matrices added to the frozen weights.
Why are in-distribution test results weak evidence of generality?
Show answer
The model may have seen very similar tasks and scenes.
Give two questions to ask about a highlight video.
Show answer
Is it representative? How often does it fail and how?
Why is 90 % success insufficient for many factories?
Show answer
Production often needs reliability like 99.9 %.
Where should a VLA sit relative to safety systems?
Show answer
Above a low-level controller and an independent safety layer.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.