
MSAZ-301 · Lesson 3 of 12 · 21 min
Generating embeddings
▶ Video coming soon A video version of this lesson is on the way.
A vector column is only useful once it holds vectors, and vectors come from an embedding model. Hana's first decision was which model to use and where it would run. Her second was what text to send it, because an embedding can only capture what it is given. Her third, which took longest, was how to keep embeddings current when product descriptions change every week.
Choosing an embedding model
The DP-800 outline asks candidates to evaluate external models, including multimodal, multilanguage, size and structured-output capabilities. For embeddings, the main questions are these. Which languages must it understand? Harrow & Finch's guides are in English, but the Canadian stores also serve customers who type in other languages, and a multilingual model maps a question in one language near a passage in another. How many dimensions does it return, and can that be reduced? How long an input does it accept, measured in tokens, the word pieces models work with? Where does it run: a hosted service such as Azure OpenAI in Microsoft Foundry, another provider, or a local runtime? And what does it cost per million tokens?
| Option | Where it runs | Strengths | Trade-offs |
|---|---|---|---|
| Azure OpenAI embedding model in Foundry | Azure region chosen by the company | Strong quality, managed identity, regional deployment | Per-token cost; network call for each request |
| OpenAI API | OpenAI's service | Same model family, simple key setup | Data leaves Azure; API keys rather than managed identity |
| Ollama | A server the company runs | No per-token charge; data stays on premises | Company runs and secures the server; quality depends on model |
| ONNX Runtime, local (SQL Server 2025) | On the SQL Server machine, Windows only | No network call; data never leaves the server | Preview feature; uses server CPU; only trusted model files |
Hana chose an Azure OpenAI deployment of text-embedding-3-small in Microsoft Foundry, in Canada East, with 1,536 dimensions. Carmen Ortiz approved it on condition that the deployment be a regional Standard deployment, which processes requests in the chosen region, rather than a Global deployment, which may process them in any Azure region; for product text it mattered little, but the team wanted one rule for all data. Nikolai also tested a multilingual open model on a small Ollama server; it was free per call but noticeably weaker on hardware terms, and the team decided running another server was not worth it.
Registering the model
SQL Server 2025 and Azure SQL call embedding models through an external model, a database object created with CREATE EXTERNAL MODEL. It records the endpoint location, the API format, the model type, the model name, the credential to use and any extra parameters. The model type is currently always EMBEDDINGS. The API format is one of Azure OpenAI, OpenAI, Ollama or ONNX Runtime. Only HTTPS endpoints are accepted.
CREATE EXTERNAL MODEL CatalogEmbedder
AUTHORIZATION catalog_owner
WITH (
    LOCATION   = 'https://hf-aoai-cat.openai.azure.com/openai/deployments/te3-small/embeddings?api-version=2024-10-21',
    API_FORMAT = 'Azure OpenAI',
    MODEL_TYPE = EMBEDDINGS,
    MODEL      = 'text-embedding-3-small',
    CREDENTIAL = [https://hf-aoai-cat.openai.azure.com/],
    PARAMETERS = '{"dimensions": 1536, "sql_rest_options": {"retry_count": 3}}'
);

GRANT EXECUTE ON EXTERNAL MODEL::CatalogEmbedder TO role_embedding_writer;
Creating or changing a model needs the CREATE EXTERNAL MODEL or ALTER ANY EXTERNAL MODEL permission; using it needs EXECUTE on the model. That separation lets the DBA team own model definitions while application roles only call them. The sql_rest_options retry count, from 0 to 10, makes the engine retry temporary HTTP failures such as throttling. On SQL Server 2025, outbound REST calls are off until an administrator enables the external rest endpoint enabled option with sp_configure; Azure SQL Database and Fabric have it on by default. The sys.external_models catalog view lists the models a user can see.
Calling AI_GENERATE_EMBEDDINGS
AI_GENERATE_EMBEDDINGS takes a text expression and the name of an external model and returns the embedding as a JSON array, which converts to the vector type. It can be used in a SELECT, an UPDATE, an INSERT ... SELECT or a variable assignment. A PARAMETERS clause can override model-level settings for one call.
-- One value
DECLARE @q vector(1536) = AI_GENERATE_EMBEDDINGS(N'stop the bathroom mirror fogging' USE MODEL CatalogEmbedder);

-- Fill embeddings for products that do not have one yet
INSERT INTO catalog.ProductEmbedding (ProductId, ModelName, EmbeddedAt, SourceHash, Embedding)
SELECT TOP (500) p.ProductId, 'text-embedding-3-small', SYSUTCDATETIME(),
       HASHBYTES('SHA2_256', p.EmbeddingText),
       AI_GENERATE_EMBEDDINGS(p.EmbeddingText USE MODEL CatalogEmbedder)
FROM catalog.vProductForEmbedding AS p
WHERE NOT EXISTS (SELECT 1 FROM catalog.ProductEmbedding AS e WHERE e.ProductId = p.ProductId);
Each row in that INSERT calls the model once, so 18,400 products mean 18,400 HTTPS calls. Hana ran the load in batches of 500 in a loop with a short pause between batches, which kept the deployment's tokens-per-minute quota from throttling the job, and made the load restartable: if it stopped, the next run picked up the rows without embeddings. The extended events ai_generate_embeddings_summary and external_rest_endpoint_summary recorded status codes and errors for each call, which is how she spotted that a dozen products with empty descriptions were returning errors.
What to embed
The DP-800 outline asks which columns to include in embeddings. Embedding the product name alone produced weak results, because names like Pro Series 2 are short and say little. Embedding everything, including SKU, price and stock, made results worse, because numbers and codes add noise to a vector that represents meaning, and prices change daily, which would force constant re-embedding. Hana settled on a view that builds one text per product from the fields that describe what it is and what it is for.
CREATE VIEW catalog.vProductForEmbedding AS
SELECT p.ProductId,
       CONCAT(p.ProductName, N'. Category: ', c.CategoryPath,
              N'. ', p.ShortDescription,
              N' Uses: ', p.UsageNotes,
              N' Features: ', p.FeatureList) AS EmbeddingText
FROM catalog.Product AS p
JOIN catalog.Category AS c ON c.CategoryId = p.CategoryId
WHERE p.IsActive = 1
  AND p.ShortDescription IS NOT NULL;
The principle is to embed what a user might mean and filter or join on what a user might specify. Store, price range, stock and brand are better as ordinary columns used in WHERE clauses, which vector search can apply during the search, as lesson 6 shows. Hana also stored a hash of the embedded text, so a nightly check can find products whose descriptive text changed and only re-embed those.
Chunking long text
Guides are long: the average is about 8,600 characters, and the longest, a 40-page deck-building guide, is over 90,000. An embedding of a whole guide blurs many topics into one vector, and the model also has an input limit. The usual answer is to split documents into chunks of a few hundred to a thousand or so characters, embed each chunk, and search chunks. AI_GENERATE_CHUNKS does the splitting in T-SQL. It currently supports one chunk type, FIXED, which cuts the text into pieces of CHUNK_SIZE characters, with an optional OVERLAP from 0 to 50, the share of the chunk size, out of 100, repeated from the end of the preceding chunk so that a sentence cut at a boundary still appears whole in one chunk. It needs database compatibility level 170.
INSERT INTO guide.GuideChunk (GuideId, ChunkOrder, ChunkText, Embedding)
SELECT g.GuideId, c.chunk_order, c.chunk,
       AI_GENERATE_EMBEDDINGS(c.chunk USE MODEL CatalogEmbedder)
FROM guide.Guide AS g
CROSS APPLY AI_GENERATE_CHUNKS(SOURCE = g.BodyText, CHUNK_TYPE = FIXED,
                               CHUNK_SIZE = 1000, OVERLAP = 10) AS c
WHERE g.GuideId BETWEEN @first AND @last;
Fixed-size chunks are simple but blind to structure: a chunk can start mid-sentence or merge the end of one section with the start of the next. Hana improved results by chunking each guide section separately, using the headings the guides already have, so a chunk never crosses from cutting tiles to grouting. She also prefixed each chunk with its guide and section title before embedding, so a chunk that says apply two coats still carries the context of which job it belongs to.
def fixed_chunks(text, size, overlap):
    """Mimic FIXED chunking: each chunk after the first starts `overlap` parts in 100 of `size` earlier."""
    step = size - size * overlap // 100
    chunks, start = [], 0
    while start < len(text):
        chunks.append(text[start:start + size])
        if start + size >= len(text):
            break
        start += step
    return chunks

guide = "x" * 8_600            # an average guide of 8,600 characters
for size, overlap in [(1000, 0), (1000, 10), (500, 20)]:
    c = fixed_chunks(guide, size, overlap)
    total = sum(len(s) for s in c)
print(f"size {size}, overlap {overlap}: {len(c)} chunks, {total:,} characters embedded")size 1000, overlap 0: 9 chunks, 8,600 characters embedded size 1000, overlap 10: 10 chunks, 9,500 characters embedded size 500, overlap 20: 22 chunks, 10,700 characters embedded
What this code does
The program cuts a text of 8,600 characters into fixed-size pieces, stepping back by the overlap each time, the way fixed chunking does. It counts the chunks and the total characters sent to the model for three settings. The output shows that 1,000-character chunks with no overlap give 9 chunks, adding overlap gives 10, and 500-character chunks with 20 in 100 overlap give 22 chunks and about a quarter more text to embed and pay for than the original.
Smaller chunks give more precise matches but more vectors, more model calls and less context in each passage handed to a language model later. Larger chunks carry more context but blur topics. Hana tried 500, 1,000 and 1,500 characters on the 60 test questions; 1,000 characters with 10 in 100 overlap, chunked per section, gave the best mix, and produced 10,416 chunks from the 1,240 guides.
Keeping embeddings current
Products are added and descriptions edited every week. An embedding generated from old text silently returns wrong matches, so the team needed a maintenance method. The DP-800 outline lists several, and each fits a different need.
| Method | How it works | Fits when |
|---|---|---|
| Table trigger | A trigger calls the model when a row changes | Very low change volume; but model calls inside the user's transaction slow writes and can fail them |
| Change tracking plus a scheduled job | A job reads changed keys since the last run and re-embeds them | Changes can wait minutes or hours; simple and reliable |
| Azure Functions with SQL trigger binding | A function runs when rows change, calls the model and writes back | Near-real-time updates outside the user transaction |
| Azure Logic Apps | A low-code workflow reacts to changes or a schedule | Teams that prefer workflows over code |
| Change data capture | Reads full change history from the log | The old and new values are needed, or many consumers |
| Change event streaming | The engine streams changes to Azure Event Hubs | Event-driven architectures with several downstream services |
| Pipelines in Microsoft Foundry | A managed ingestion pipeline chunks, embeds and writes back | Large document collections and managed orchestration |
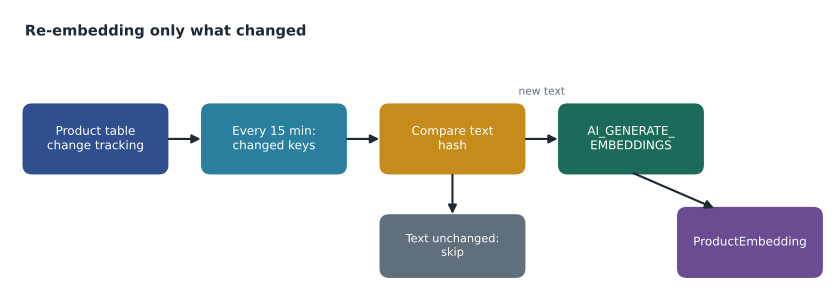
A trigger was ruled out quickly: a model call can take a few hundred milliseconds and can fail, and putting it inside the transaction that saves a product would make editing slower and occasionally impossible. Hana chose change tracking with a job that runs every 15 minutes, compares the stored hash with the hash of the current embedding text, and re-embeds only rows whose descriptive text changed. A price change, which touches the Product table but not the embedding text, costs nothing. For the pilot, Elena moved the job to an elastic job agent, as MSAZ-282 described for other scheduled work.
Worked problem
Estimating a full re-embedding
Nikolai wants to know how long a full re-embedding would take if the team changed models. The catalogue has 18,400 products averaging 520 characters of embedding text and 10,416 guide chunks of about 1,000 characters. Assume about 4 characters per token and a deployment quota of 350,000 tokens a minute. How many tokens, and roughly how many minutes at the quota?
Show solution
- \[18{,}400 \times 520 = 9{,}568{,}000 \text{ characters}\]
- \[10{,}416 \times 1{,}000 = 10{,}416{,}000 \text{ characters}\]
- Total: 19,984,000 characters, about 4,996,000 tokens at 4 characters per token.
- \[4{,}996{,}000 \div 350{,}000 \approx 14.3 \text{ minutes}\]
- In practice the request rate limit and the batch pauses stretch this, so Hana planned for about an hour.
Answer: About 5 million tokens, around 15 minutes at the full quota, planned as an hour with batching. At an illustrative price of 0.02 US dollars per million tokens for a small embedding model, the model charge is about 10 cents.
Common mistakes
MistakeEmbed every column, including SKU and price, for the richest vectors.
InsteadEmbed descriptive text; filter and join on codes, prices and stock as ordinary columns.
MistakeGenerate embeddings in a trigger so they are always current.
InsteadModel calls in a trigger slow and can fail user transactions; re-embed asynchronously.
MistakeOne embedding per document is enough.
InsteadLong documents are chunked so each vector represents one topic and fits the model's input limit.
MistakeAI_GENERATE_CHUNKS can split by sentence or heading.
InsteadIt currently supports FIXED chunks of a set number of characters, with optional overlap.
Summary and key terms
- Choose an embedding model on language support, dimensions, input length, hosting location and cost.
- CREATE EXTERNAL MODEL registers an endpoint with its API format (Azure OpenAI, OpenAI, Ollama or ONNX Runtime), model type EMBEDDINGS, model name, credential and parameters.
- AI_GENERATE_EMBEDDINGS returns an embedding for a text value using a registered model; load in restartable batches.
- Embed descriptive text only; keep codes, prices and stock as filterable columns.
- AI_GENERATE_CHUNKS splits text into FIXED chunks with an overlap from 0 to 50 and needs compatibility level 170.
- Keep embeddings current asynchronously, for example with change tracking and a stored hash of the embedded text.
- Token
- A word piece that models use to measure and process text, roughly four characters of English on average.
- Chunk
- A piece of a longer text that is embedded and searched on its own.
- Chunk overlap
- Text repeated from the end of one chunk at the start of the next, so boundary sentences stay whole.
- AI_GENERATE_EMBEDDINGS
- A T-SQL function that calls a registered embedding model and returns the vector.
- AI_GENERATE_CHUNKS
- A T-SQL table-valued function that splits text into fixed-size chunks.
- Embedding maintenance
- The process of regenerating embeddings when their source text changes.
Practice problems
Work each problem on paper first, then reveal the answer to check.
Why did Hana leave prices out of the embedding text?
Show answer
Prices are numbers that add noise to meaning and change often, which would force constant re-embedding; they are filtered as ordinary columns instead.
What permission does a role need to use an external model in AI_GENERATE_EMBEDDINGS?
Show answer
EXECUTE on the external model.
What range of values does the OVERLAP argument of AI_GENERATE_CHUNKS accept?
Show answer
0 to 50, a share of the chunk size out of 100.
Why is a trigger a poor way to generate embeddings?
Show answer
The model call runs inside the user's transaction, slowing writes and failing them when the call fails.
How did the team avoid re-embedding products after a price change?
Show answer
They compared a stored hash of the embedding text with the current text and re-embedded only changed text.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.