
CMPUT-474 · Lesson 2 of 12 · 33 min
Finite automata and nondeterminism
The simplest machine worth studying has no memory except its current state. It reads its input once, from left to right, one symbol at a time, and at each step moves to a new state determined only by its current state and the symbol it has just read. When the input ends, it accepts or rejects according to the state it is in. This is a finite automaton. Despite the extreme limitation, finite automata are everywhere: in the lexical analysers of compilers, in network packet filters, in text search tools such as grep, in hardware controllers, in protocol specifications and in the input validators of web forms. This lesson defines them precisely, shows how to design them, introduces nondeterminism and proves that nondeterminism adds convenience but not power.
Deterministic finite automata
A deterministic finite automaton (DFA) is a 5-tuple \(M = (Q, \Sigma, \delta, q_0, F)\), where Q is a finite set of states, \(\Sigma\) is the input alphabet, \(\delta : Q \times \Sigma \to Q\) is the transition function, \(q_0 \in Q\) is the start state and \(F \subseteq Q\) is the set of accepting states. The word deterministic refers to \(\delta\) being a function: from each state, each symbol leads to exactly one next state. To describe what M does on a whole string we extend \(\delta\) to strings by induction: \(\hat\delta(q, \varepsilon) = q\) and \(\hat\delta(q, wa) = \delta(\hat\delta(q, w), a)\). M accepts w if \(\hat\delta(q_0, w) \in F\), and the language of M is \(L(M) = \{w : \hat\delta(q_0, w) \in F\}\). A language is regular if some DFA recognizes it.
Two things in that definition deserve attention. First, \(\delta\) must be total: every state needs a transition on every symbol. In diagrams we often omit transitions to a dead state, a non-accepting state that loops to itself on every symbol, but it is still part of the machine. Second, a DFA always halts after exactly \(|w|\) steps, so it decides its language; there is no looping and no distinction between recognizing and deciding. Running a DFA takes linear time and constant memory, which is why automata are the workhorse of fast text processing.
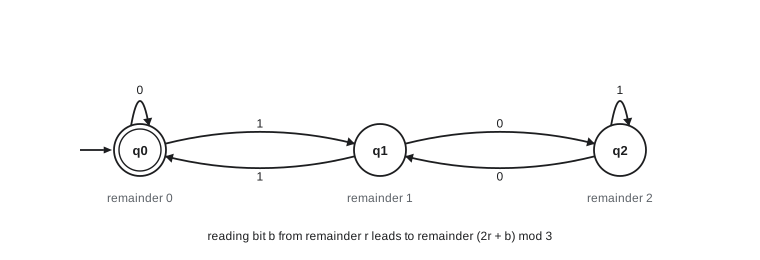
The figure shows a classic DFA. It reads a binary number from the most significant bit and accepts if the number is divisible by 3. The key design insight is to ask what the machine must remember. It does not need the whole number, only the number modulo 3, because appending a bit b to a number v gives \(2v + b\), and \((2v + b) \bmod 3\) depends only on \(v \bmod 3\). So three states suffice, one per remainder, with \(\delta(q_r, b) = q_{(2r + b) \bmod 3}\). The program below builds exactly this machine, traces several inputs, and checks it against ordinary arithmetic on every binary string up to length 12.
# A DFA for binary numbers divisible by 3. States remember the value read so far, mod 3.
# Reading bit b from state r moves to (2r + b) mod 3, because appending b doubles the value and adds b.
DELTA = {(r, b): (2 * r + int(b)) % 3 for r in range(3) for b in "01"}
START, ACCEPT = 0, {0}

def run(w):
    q, trace = START, [START]
    for c in w:
        q = DELTA[(q, c)]
        trace.append(q)
    return q in ACCEPT, trace

for r in range(3):
    print(f"delta(q{r}, 0) = q{DELTA[(r, '0')]}   delta(q{r}, 1) = q{DELTA[(r, '1')]}")
for w in ["0", "11", "110", "1001", "10101", "111111", "1000000"]:
    ok, trace = run(w)
    print(f"{w:>8} = {int(w, 2):3d}  states {' '.join('q%d' % s for s in trace):28s} {'accept' if ok else 'reject'}")
# exhaustive check against arithmetic for every string up to length 12
from itertools import product
bad = sum(run("".join(t))[0] != (int("".join(t), 2) % 3 == 0)
          for n in range(1, 13) for t in product("01", repeat=n))
print("mismatches on all 8190 strings of length 1..12:", bad)delta(q0, 0) = q0 delta(q0, 1) = q1
delta(q1, 0) = q2 delta(q1, 1) = q0
delta(q2, 0) = q1 delta(q2, 1) = q2
0 = 0 states q0 q0 accept
11 = 3 states q0 q1 q0 accept
110 = 6 states q0 q1 q0 q0 accept
1001 = 9 states q0 q1 q2 q1 q0 accept
10101 = 21 states q0 q1 q2 q2 q1 q0 accept
111111 = 63 states q0 q1 q0 q1 q0 q1 q0 accept
1000000 = 64 states q0 q1 q2 q1 q2 q1 q2 q1 reject
mismatches on all 8190 strings of length 1..12: 0Designing automata
Designing a DFA is mostly a matter of deciding what finite information about the prefix read so far determines the answer for every possible continuation. For 'contains the substring 101' the machine must remember how much of 101 it has matched at the end of the prefix: nothing, 1, or 10, plus a fourth state for 'already seen 101', which is accepting and absorbing. For 'the number of 0s is even and the number of 1s is odd' it must remember two parities, giving four states. For 'the last symbol is 1' it must remember only the last symbol. If the answer depends on an unbounded quantity, such as the difference between the number of as and bs read so far, no finite set of states can remember it, and the language is not regular. Lesson 4 turns that intuition into proofs.
Automata are often designed for formats. Input validation is a natural example: a form field accepts a string only if it has the right shape. The program below implements a DFA as a table-driven loop for a postal code format. Each state counts how many characters have matched so far, and any wrong character sends the machine to a dead state. Real validation would add more rules, such as letters that are never used, but each such rule can be handled by more states or by intersecting with another regular language, which lesson 3 shows is always possible.
# A DFA, written as a table, for Canadian postal codes such as T2P 1J9:
# letter digit letter, a space, digit letter digit. (Real codes also exclude some letters;
# this DFA keeps only the format.) State i means "the first i characters were correct".
PATTERN = ["L", "D", "L", " ", "D", "L", "D"]
def kind(c):
    if c.isascii() and c.isupper(): return "L"
    if c.isdigit(): return "D"
    return c if c == " " else "other"

def accepts(w):
    q = 0                                   # states 0..7 plus a dead state "dead"
    for c in w:
        if q == "dead" or q == len(PATTERN) or kind(c) != PATTERN[q]:
            q = "dead"
        else:
            q += 1
    return q == len(PATTERN)

for w in ["T2P 1J9", "H3Z 2Y7", "K1A 0B1", "T2P1J9", "t2p 1j9", "T2P 1J99", "22P 1J9"]:
    print(f"{w!r:12} {'accept' if accepts(w) else 'reject'}")
print("states used:", len(PATTERN) + 2, "(7 progress states, 1 accepting, 1 dead)")'T2P 1J9' accept 'H3Z 2Y7' accept 'K1A 0B1' accept 'T2P1J9' reject 't2p 1j9' reject 'T2P 1J99' reject '22P 1J9' reject states used: 9 (7 progress states, 1 accepting, 1 dead)
Nondeterministic finite automata
A nondeterministic finite automaton (NFA) relaxes the requirement that each state and symbol determine a unique next state. Formally an NFA is \(N = (Q, \Sigma, \delta, q_0, F)\) with \(\delta : Q \times \Sigma_\varepsilon \to \mathcal{P}(Q)\), where \(\Sigma_\varepsilon = \Sigma \cup \{\varepsilon\}\). From a state, a symbol may lead to several states, to one, or to none, and \(\varepsilon\)-transitions let the machine change state without reading anything. N accepts w if some sequence of choices consumes w and ends in an accepting state. Rejection requires that every possible path either gets stuck or ends in a non-accepting state.
There are two useful ways to picture nondeterminism. In the guessing view, the machine guesses the right choice at each step, and it accepts if any guess succeeds. In the parallel view, the machine follows all choices at once, keeping track of the set of states it could be in; it accepts if that set contains an accepting state when the input ends. The second view is the one an implementation uses, and it is also the idea behind the proof that NFAs are no more powerful than DFAs. Nondeterminism is not a physical capability; it is a descriptive device that often makes machines much smaller and much easier to design.
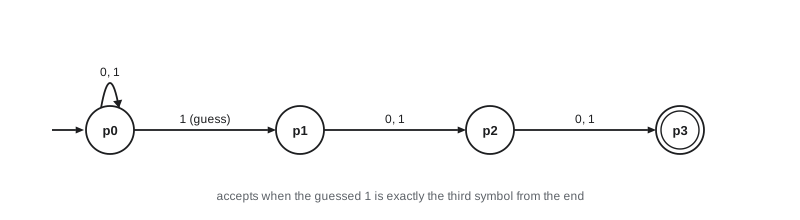
The figure shows an NFA for \(L_3\), the binary strings whose third symbol from the end is 1. The start state loops on every symbol, and on reading a 1 it may also guess that this 1 is the third symbol from the end and move along a chain of three more states. The guess is right exactly when the input ends as the chain reaches the accepting state. Generalizing, \(L_n\) has an NFA with \(n + 1\) states. A DFA for \(L_n\) is much harder to write by hand: it must remember the last n symbols read, because any of them might turn out to be the n-th from the end.
Equivalence of NFAs and DFAs
Theorem (Rabin and Scott, 1959). For every NFA N there is a DFA M with \(L(M) = L(N)\). The proof is the subset construction, which CMPUT-415 used to build scanners; here we state it precisely and say why it is correct. First handle \(\varepsilon\)-moves: for a set of states S, let \(E(S)\) be its \(\varepsilon\)-closure, the states reachable from S using only \(\varepsilon\)-transitions. Define M with state set \(\mathcal{P}(Q)\), start state \(E(\{q_0\})\), transition \(\delta_M(S, a) = E\bigl(\bigcup_{q \in S} \delta(q, a)\bigr)\), and accepting states all sets that contain at least one state of F.
Correctness is an induction on the length of the input. The claim is that \(\hat\delta_M(E(\{q_0\}), w)\) is exactly the set of states N can be in after reading w. For \(w = \varepsilon\) that set is \(E(\{q_0\})\) by definition. If the claim holds for w, then after reading one more symbol a, the states N can reach are those reachable from the current set by an a-transition followed by \(\varepsilon\)-moves, which is exactly \(\delta_M\) applied to the current set. So M tracks N's possible states perfectly, and M accepts w if and only if one of N's possible states at the end is accepting, which is the definition of N accepting w.
The construction can create up to \(2^{|Q|}\) states, and in practice one builds only the subsets reachable from the start. Is the exponential worst case real? Yes. The program below applies the construction to the NFA for \(L_n\) and finds exactly \(2^n\) reachable subsets for every n tested. That count is not an accident of the construction. Any DFA for \(L_n\) needs at least \(2^n\) states, because any two distinct strings x and y of length n differ in some position, say position i from the end; appending \(n - i\) arbitrary symbols puts that position exactly n from the end, so one extension is in \(L_n\) and the other is not. A DFA that confused x and y by ending in the same state would give both extensions the same answer. With \(2^n\) pairwise distinguishable strings, the DFA needs \(2^n\) states. Lesson 4 turns this idea into the Myhill–Nerode theorem.
# L_n = binary strings whose n-th symbol from the end is 1.
# An NFA with n + 1 states guesses where that 1 is. The subset construction
# (CMPUT-415 lesson 2) produces a DFA; count its reachable states.
def nfa(n):
    # states 0..n; 0 loops on 0/1 and on 1 may also move to 1; i -> i+1 on 0/1; n accepts
    d = {}
    for c in "01":
        d[(0, c)] = {0, 1} if c == "1" else {0}
        for i in range(1, n):
            d[(i, c)] = {i + 1}
        d[(n, c)] = set()
    return d

def subset_construction(n):
    d = nfa(n)
    start = frozenset({0})
    seen, todo = {start}, [start]
    while todo:
        S = todo.pop()
        for c in "01":
            T = frozenset(q for s in S for q in d[(s, c)])
            if T not in seen:
                seen.add(T); todo.append(T)
    return seen

for n in range(1, 11):
    states = subset_construction(n)
print(f"n = {n:2d}: NFA states {n + 1:2d}, reachable DFA states {len(states):5d} = 2^{n}: {len(states) == 2 ** n}")n = 1: NFA states 2, reachable DFA states 2 = 2^1: True n = 2: NFA states 3, reachable DFA states 4 = 2^2: True n = 3: NFA states 4, reachable DFA states 8 = 2^3: True n = 4: NFA states 5, reachable DFA states 16 = 2^4: True n = 5: NFA states 6, reachable DFA states 32 = 2^5: True n = 6: NFA states 7, reachable DFA states 64 = 2^6: True n = 7: NFA states 8, reachable DFA states 128 = 2^7: True n = 8: NFA states 9, reachable DFA states 256 = 2^8: True n = 9: NFA states 10, reachable DFA states 512 = 2^9: True n = 10: NFA states 11, reachable DFA states 1024 = 2^10: True
| Property | DFA | NFA |
|---|---|---|
| Transitions from a state on a symbol | Exactly one | Zero, one or many; epsilon-moves allowed |
| Acceptance | The unique run ends in F | Some run ends in F |
| Languages recognized | Regular languages | Regular languages (same class) |
| Size for L_n | At least 2^n states | n + 1 states |
| Simulation cost per symbol | Constant | Proportional to the number of states, tracking a set |
| Complement | Swap accepting and non-accepting states | Convert to a DFA first; swapping fails |
| Typical use | Fast matching, hardware, final scanners | Design, regex compilation, proofs |
What equivalence buys us
Because NFAs and DFAs recognize the same class of languages, we can use whichever is more convenient in each situation. Proofs of closure properties often build an NFA, because nondeterminism lets a machine guess where one part of the input ends and the next begins. Implementations often prefer DFAs, because their running time per symbol is constant, or simulate NFAs directly with the set-of-states method when the DFA would be too large; this is the trade-off made by regular expression engines that guarantee linear-time matching, such as RE2 and Rust's regex crate. One operation does not transfer for free: complementation. Swapping accepting and non-accepting states complements a DFA, but in an NFA it gives the language of strings with some rejecting run, which is not the complement. To complement an NFA, convert it to a DFA first.
The equivalence also shows something conceptual. Nondeterminism does not change the power of finite automata. We will see that it does change the power of pushdown automata, whose deterministic version recognizes strictly fewer languages, and that whether it changes the power of time-bounded Turing machines is exactly the P versus NP question. Finite automata are the one level at which the question has a simple, completely understood answer, and the price of removing nondeterminism, an exponential increase in states in the worst case, is known exactly.
Worked examples
Worked problem
Design a DFA
Design a DFA over {a, b} for strings that contain the substring aba.
Show solution
- States record the longest suffix of the input that is a prefix of aba: s0 (none), s1 (a), s2 (ab), s3 (aba seen, accepting).
- From s0: a goes to s1, b stays in s0. From s1: a stays in s1 (the suffix a is still a prefix), b goes to s2.
- From s2: a goes to s3; b goes to s0, because the suffix abb ends with no prefix of aba.
- s3 loops on both symbols, since once aba has appeared the string is in the language.
Answer: Four states s0 to s3 with start s0 and accepting state s3, transitions as above.
Worked problem
Subset construction by hand
Convert the NFA with states {p, q}, start p, accepting q, transitions p on a to {p, q}, p on b to {p}, q on a or b to the empty set, into a DFA.
Show solution
- Start state {p}. On a: {p, q}. On b: {p}.
- State {p, q}. On a: {p, q} together with nothing from q, so {p, q}. On b: {p}.
- No other subsets are reachable. Accepting subsets are those containing q: only {p, q}.
Answer: A two-state DFA: {p} (start) and {p, q} (accepting); a moves to {p, q}, b moves to {p}. It accepts strings ending in a.
Worked problem
A lower bound by distinguishable strings
Show that any DFA for L_2 (second symbol from the end is 1) has at least 4 states.
Show solution
- Take the four strings 00, 01, 10, 11.
- 10 and 00 differ in the second position from the end: 10 is in L_2 and 00 is not, so they must reach different states.
- 01 and 00 differ in the last position: append one symbol, say 0, giving 010 (in L_2) and 000 (not).
- Checking all six pairs the same way shows every pair is distinguishable, so the DFA needs 4 distinct states.
Answer: Four pairwise distinguishable strings force at least 4 states, which matches the subset construction.
Common mistakes
MistakeLeave out transitions in a DFA and call it complete.
InsteadA DFA needs a transition from every state on every symbol; missing ones go to an explicit or implied dead state.
MistakeComplement an NFA by swapping its accepting states.
InsteadThat accepts strings with some rejecting run; convert to a DFA first, then swap.
MistakeBelieve NFAs recognize more languages than DFAs.
InsteadThey recognize exactly the regular languages; they are only more compact.
MistakeThink an NFA rejects if one run rejects.
InsteadAn NFA accepts if any run accepts; it rejects only if every run fails.
MistakeAssume the subset construction always blows up.
InsteadOften few subsets are reachable; the 2^n worst case occurs for languages such as L_n.
Summary and key terms
- A DFA \((Q, \Sigma, \delta, q_0, F)\) has exactly one transition per state and symbol and accepts if its run ends in F.
- A language is regular if some DFA recognizes it; DFAs always halt, so they decide their languages.
- Designing a DFA means choosing finite information about the prefix that determines the answer for every continuation.
- NFAs allow several or no transitions and epsilon-moves, and accept if some run accepts.
- The subset construction converts any NFA into an equivalent DFA, so NFAs recognize exactly the regular languages.
- The blowup can be exponential: L_n has an (n + 1)-state NFA but needs 2^n DFA states.
- Distinguishable strings give lower bounds on DFA size.
- DFA
- A finite automaton with exactly one transition from each state on each symbol.
- NFA
- A finite automaton that may have several or no transitions on a symbol, and epsilon-transitions.
- Transition function
- The map from a state and symbol to the next state (or set of states).
- Extended transition function
- The transition function extended to whole strings by induction.
- Regular language
- A language recognized by some DFA.
- Dead state
- A non-accepting state that every transition leads back to itself.
- Epsilon-closure
- The set of states reachable from a set using only epsilon-transitions.
- Subset construction
- Converting an NFA into a DFA whose states are sets of NFA states.
- Distinguishable strings
- Two strings for which some extension is in the language for one but not the other.
Practice problems
Work each problem on paper first, then reveal the answer to check.
How many states does a DFA need for "the number of 1s is divisible by 4"?
Show answer
Four, one for each count modulo 4.
Give the transition rule for the divisible-by-5 DFA on binary input.
Show answer
From remainder r on bit b go to \((2r + b) \bmod 5\).
Why does a DFA always decide its language?
Show answer
It halts after reading the input, in exactly |w| steps.
What does an NFA do when it has no transition on the current symbol?
Show answer
That run dies; the NFA still accepts if another run succeeds.
What is the start state of the DFA built by the subset construction?
Show answer
The epsilon-closure of the NFA start state.
How many states can the subset construction produce from a 6-state NFA, at most?
Show answer
2^6 = 64.
Why can't you complement an NFA by swapping accepting states?
Show answer
Acceptance means some run accepts, so the swapped machine accepts strings with any rejecting run.
Give two strings distinguishable for the language of strings ending in 1.
Show answer
For example 0 and 1: with the empty extension, 1 is in the language and 0 is not.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.