
AI-499 · Lesson 3 of 12 · 25 min
Data: sourcing, permissions, quality and documentation
Data determines what a model can learn, and in most capstone projects it consumes more time than modelling. Finding suitable data, confirming that you are allowed to use it, cleaning and labelling it, and documenting what it contains are skilled tasks with legal, ethical and technical dimensions. Problems that are not caught early, such as missing permissions, biased sampling, label noise or duplicated records, can invalidate every result that follows. This lesson covers sources of data, licences and consent, privacy law and research ethics, data quality auditing, labelling and annotation, and documenting datasets with datasheets.
Sources of data
Capstone data typically comes from one or more of the following: data provided by a project partner, such as records, documents or images from its operations; public datasets from repositories such as government open data portals, research archives and benchmark collections; data the team collects, through surveys, sensors, photography or web forms; data obtained through public interfaces, such as application programming interfaces (APIs); and synthetic data generated by simulation or models. Each source has advantages and pitfalls. Partner data is realistic but may be messy, sensitive and slow to obtain. Public benchmarks are convenient but may not represent the real use case and are often already "solved". Collected data fits the need but is expensive. Synthetic data is cheap but may not reflect real-world variation, and models trained on it may fail on real inputs.
Licences and terms of use
Data is rarely free of conditions. Public datasets carry licences, such as Creative Commons licences, open government licences or custom research licences, that may restrict commercial use, require attribution, prohibit redistribution or forbid particular uses. Websites have terms of service that may prohibit automated collection, and copyright protects much text, imagery and audio. Partner data comes with contractual restrictions on use, storage and sharing. Before using any dataset, record its source, licence or agreement, permitted uses and obligations, and check that the capstone's intended uses, including public demonstration and publication, are allowed. When in doubt, ask the program's legal or research office.
Privacy and personal information
Data about identifiable people is regulated, and capstone teams must handle it lawfully and carefully.
In Canada, the Personal Information Protection and Electronic Documents Act (PIPEDA) governs personal information in private-sector commercial activities, provinces such as Quebec, Alberta and British Columbia have their own private-sector laws, and Quebec's Law 25 adds requirements such as privacy impact assessments and transparency about automated decisions. Public institutions, including many universities and colleges, are covered by provincial public-sector privacy laws. Research involving human participants follows the Tri-Council Policy Statement: Ethical Conduct for Research Involving Humans (TCPS 2), which requires review by a research ethics board (REB) for many projects. Health information has additional provincial laws.
Practical steps for any project using personal data include collecting only what is necessary; removing direct identifiers such as names, addresses and identification numbers, while recognizing that de-identified data can sometimes be re-identified by combining fields; storing data securely with access limited to the team; avoiding the upload of personal data to external services, including commercial AI APIs, unless the agreement and law permit it; and planning for deletion at the end of the project. Programs often require teams to complete an ethics or data management form before accessing sensitive data.
Auditing data quality
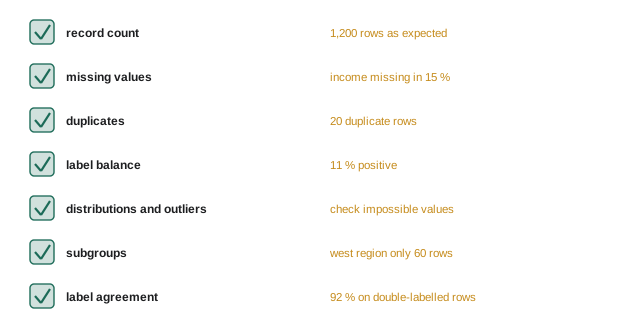
Every dataset should be audited before modelling. A basic audit checks: the number of records and whether it matches expectations; missing values in each field and whether missingness is random or patterned; duplicates, which inflate apparent performance if they cross train and test splits; label distribution and class balance; distributions of key features, looking for impossible values, outliers and unit errors; representation of important subgroups, such as regions, devices or demographic groups; and label quality, estimated by having a sample labelled twice and measuring agreement.
import numpy as np
# A quick data audit: missing values, duplicates, label balance and label noise
rng = np.random.default_rng(1)
n = 1200
age = rng.normal(45, 15, n).round(); age[rng.random(n) < 0.06] = np.nan
income = rng.lognormal(10.8, 0.5, n); income[rng.random(n) < 0.15] = np.nan
region = rng.choice(["north", "south", "east", "west"], n, p=[0.55, 0.25, 0.15, 0.05])
label = rng.random(n) < 0.12
dup_idx = rng.choice(n, 40, replace=False)
customer = rng.integers(10**8, 10**9, n)        # customer identifier
rows = np.column_stack([customer, np.nan_to_num(age, nan=-1), np.nan_to_num(income, nan=-1)])
rows[dup_idx[20:]] = rows[dup_idx[:20]]          # inject 20 exact duplicates
print(f"rows: {n}")
for name, col in [("age", age), ("income", income)]:
    print(f"missing {name}: {np.mean(np.isnan(col)):.1%}")
_, counts = np.unique(rows, axis=0, return_counts=True)
print(f"duplicate rows: {int(np.sum(counts[counts > 1] - 1))}")
print(f"positive labels: {label.mean():.1%}")
for r in ["north", "south", "east", "west"]:
    m = region == r
    print(f"  region {r:5s}: {m.sum():4d} rows, positives {label[m].mean():.1%}")
# Label noise estimate from a double-labeled sample
a = label[:200].copy(); b = a.copy(); flip = rng.random(200) < 0.07; b[flip] = ~b[flip]
print(f"annotator agreement on 200 double-labeled rows: {np.mean(a == b):.1%}")rows: 1200 missing age: 6.8% missing income: 15.5% duplicate rows: 20 positive labels: 11.0% region north: 628 rows, positives 10.0% region south: 321 rows, positives 11.5% region east : 191 rows, positives 14.7% region west : 60 rows, positives 6.7% annotator agreement on 200 double-labeled rows: 93.5%
The audit reveals issues that would shape every later step. Income is missing for about 15 % of rows, which must be handled deliberately rather than by silently dropping rows. Twenty duplicate rows must be removed or kept within a single split. The western region has only 60 rows, so any results for it will be very uncertain. Annotators agree on about 92 % of double-labelled rows, implying that around 8 % of labels may be wrong or ambiguous; a model cannot be expected to exceed this level of agreement by much, and the labelling guidelines may need clarification.
Labelling and annotation
Many projects need labels that do not yet exist. Good annotation starts with written guidelines that define each label, give examples and counter-examples, and explain how to handle ambiguous cases. Annotators should be trained on the guidelines, then label a shared pilot set so that disagreements can be discussed and guidelines refined. Inter-annotator agreement, measured by simple agreement or chance-corrected statistics such as Cohen's kappa, indicates whether the task is well defined. Annotation tools, such as open-source labelling platforms, speed the work. Where labels are expensive, active learning, which selects the most informative examples for labelling, and weak supervision, which combines noisy heuristic labels, can reduce effort. Annotators should be treated fairly: if the program uses paid annotators or crowd workers, pay and working conditions matter, and annotators of distressing content need support.
| Kappa value | Common interpretation |
|---|---|
| Below 0.20 | Slight agreement: the task or guidelines need major revision |
| 0.21–0.40 | Fair agreement |
| 0.41–0.60 | Moderate agreement |
| 0.61–0.80 | Substantial agreement |
| Above 0.80 | Almost perfect agreement |
Worked problem
Computing Cohen's kappa
Two annotators label 200 documents as relevant or not. They agree on 170 documents. Annotator A labels 40 % of documents relevant and annotator B labels 45 %. What is Cohen's kappa?
Show solution
- Observed agreement: \(p_o = 170 / 200 = 0.85\).
- Expected agreement by chance: \(p_e = 0.40 \times 0.45 + 0.60 \times 0.55 = 0.18 + 0.33 = 0.51\).
- Kappa: \(\kappa = (p_o - p_e)/(1 - p_e) = (0.85 - 0.51)/0.49 \approx 0.69\).
Answer: κ ≈ 0.69, substantial agreement; raw agreement of 85 % overstates reliability because half of it would occur by chance.
Documenting datasets
Datasets should be documented so that others, and your future selves, know what they contain and how they may be used. Gebru and colleagues proposed datasheets for datasets in 2018, a set of questions covering motivation (why was the dataset created?), composition (what does it contain, and what is missing?), collection process (how, when and by whom was it collected, with what consent?), preprocessing and labelling, uses (what is it suitable and unsuitable for?), distribution and maintenance. Similar formats include data cards and data statements for language data. A short datasheet is a required part of the capstone data report, and writing it often reveals gaps, such as unknown collection dates or unclear consent, that need to be resolved.
Handling missing data and outliers
Missing values and outliers must be handled deliberately. Options for missing values include removing rows (acceptable only when few are missing and missingness is unrelated to the outcome), imputing values with simple statistics or models, adding indicator features that flag missingness, which lets the model learn whether missingness itself is informative, and using models that handle missing values natively. Outliers may be errors to correct or remove, or genuine rare cases that matter most, such as large fraudulent transactions; domain experts can tell which. Every such decision should be applied identically to training and evaluation data, fitted only on the training split (Lesson 4), and recorded.
Synthetic data and data generated by models
Synthetic data, whether from simulation or from generative models, can supplement scarce real data, protect privacy and create examples of rare cases. It has risks: generated examples may lack the diversity and messiness of real inputs, may encode the generating model's biases, and can make evaluation misleading if test sets are synthetic too. A sound approach uses synthetic data mainly for training augmentation, always evaluates on real data, measures whether adding synthetic data actually improves real-data performance, and documents how synthetic examples were created. Labels produced by large language models can speed annotation, but their accuracy must be checked against human labels on a sample, as with any annotator.
Data management during the project
Data must be managed throughout the term, not only at the start. Keep raw data unchanged in a protected location and derive cleaned versions with scripts, so that every processing step can be repeated. Version datasets, for example with dated folders or data versioning tools, and record which version each experiment used. Restrict access to sensitive data to team members who need it, avoid copies on personal laptops and in email, and use the storage provided by the program or partner. At the end of the project, return or delete data as agreed, and record that this was done.
Representativeness
A dataset can be large and clean yet unrepresentative of the people or situations where the system will be used. Ask how the data was collected, who or what is missing, and whether conditions at deployment differ, such as different cameras, languages, regions or time periods. Compare the dataset's composition with the target population where possible, and plan slice evaluations (Lesson 6) for groups that are under-represented. Unrepresentative data is one of the main sources of unfair performance and of models that fail when deployed.
Data agreements in practice
When a partner provides data, a data sharing agreement usually specifies what data is shared, for what purpose, who may access it, where it must be stored, whether it may leave the country or be processed by third-party services, how long it may be kept, how it must be destroyed, and what happens in case of a breach. Read the agreement carefully before planning the technical approach, because a restriction such as "data may not be sent to external services" rules out commercial AI APIs and may require self-hosted models.
Finally, keep a short data log alongside the datasheet, recording each change to the data, such as relabelling rounds, removed duplicates, new collection batches and corrected errors, with dates and reasons. When results change unexpectedly, the data log is often where the explanation is found, and it allows reviewers to see exactly which version of the data supports each reported result.
Common mistakes
MistakeAssuming public data is free to use for anything.
InsteadCheck licences, terms and permitted uses.
MistakeUploading personal data to external AI services.
InsteadOnly where agreements and law permit.
MistakeSkipping the data audit.
InsteadCheck missingness, duplicates, balance, subgroups and labels first.
MistakeLabelling without written guidelines.
InsteadWrite guidelines, pilot, measure agreement and refine.
MistakeLeaving the dataset undocumented.
InsteadWrite a datasheet covering composition, collection and uses.
Summary and key terms
- Data may come from partners, public sources, collection, APIs or synthesis.
- Licences, terms and agreements govern permitted uses.
- Personal data is regulated; research with people may need ethics review.
- Audit missingness, duplicates, balance, distributions, subgroups and label quality.
- Annotation needs guidelines, pilots and agreement measures such as kappa.
- Datasheets document motivation, composition, collection and uses.
- Handle missing data and outliers deliberately and consistently.
- Licence
- Terms under which data may be used.
- Personal information
- Information about an identifiable individual.
- De-identification
- Removing identifiers from data.
- Re-identification
- Linking de-identified data back to people.
- Data audit
- Systematic check of data quality.
- Inter-annotator agreement
- Consistency between labellers.
- Cohen's kappa
- Chance-corrected agreement statistic.
- Active learning
- Choosing informative examples to label.
- Datasheet
- Structured documentation of a dataset.
- Imputation
- Filling in missing values.
Practice problems
Work each problem on paper first, then reveal the answer to check.
Name a pitfall of public benchmarks.
Show answer
They may not represent the real use case.
What must be checked before using a dataset?
Show answer
Its licence or agreement and permitted uses.
Why can de-identified data still be risky?
Show answer
It can sometimes be re-identified by combining fields.
Why do duplicates matter?
Show answer
Across splits they inflate apparent performance.
What does low annotator agreement suggest?
Show answer
Unclear guidelines or an ambiguous task.
Kappa for p_o = 0.90 and p_e = 0.60?
Show answer
0.30 / 0.40 = 0.75.
What does active learning do?
Show answer
Selects the most informative examples for labelling.
Name four datasheet sections.
Show answer
Motivation, composition, collection, preprocessing, uses, distribution, maintenance.
Why add missingness indicator features?
Show answer
Missingness itself may be informative.
Who can tell whether an outlier is an error?
Show answer
Domain experts.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.