
CMPUT-379 · Lesson 9 of 12 · 34 min
Memory management II: virtual memory, page replacement and allocation
Lesson 8 showed how page tables translate addresses and protect processes. Virtual memory goes one step further: a process's pages need not all be in physical memory at once. Pages can live on disk until they are needed, be loaded on demand, and be evicted when memory runs short. This lets programs use more memory than the machine has, lets many programs share memory flexibly, and makes starting a program fast, because nothing is loaded until it is used. The cost is that when a page is not in memory, an access takes milliseconds rather than nanoseconds, so the choices the kernel makes about which pages to keep matter enormously.
This lesson covers demand paging and page faults, page replacement algorithms, the working-set model and thrashing, and how the kernel allocates memory for itself. CMPUT-229 introduced virtual memory hardware; here we focus on the kernel's policies.
Demand paging and page faults
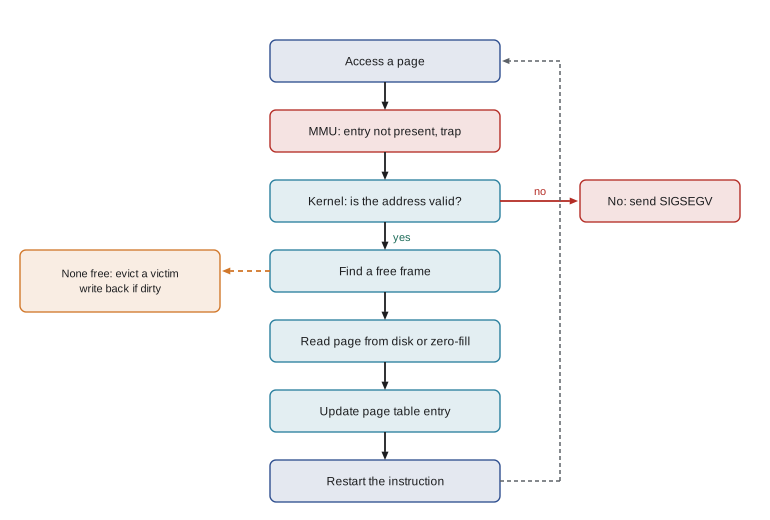
With demand paging, the kernel does not load a page until the program first touches it. When a program accesses a page whose page-table entry is not present, the MMU raises a page fault. The kernel's fault handler checks whether the address is valid for this process. If it is not (a null pointer, say), the process receives SIGSEGV. If it is valid, the kernel finds a free frame, fills it (with zeros for a new anonymous page, or with data read from a file or swap space), updates the page-table entry to present and restarts the faulting instruction, which now succeeds. The program never knows anything happened, except for the delay.
Faults come in two kinds. A minor (soft) fault needs no disk input or output: the page is new and only needs a zeroed frame, or it is already in memory in the page cache or shared with another process. A major (hard) fault must read from disk. A minor fault costs around a microsecond; a major fault costs about 100 microseconds on a fast SSD and around 10 milliseconds on a spinning disk, 10,000 to a million times more than a memory access. The program below shows demand paging directly: mapping 10 MiB costs no faults, the first touch of each page costs one minor fault, and later touches cost none.
#include <stdio.h>
#include <sys/mman.h>
#include <sys/resource.h>

static long minor_faults(void) {
    struct rusage r;
    getrusage(RUSAGE_SELF, &r);
    return r.ru_minflt;                    /* page faults served without disk I/O */
}

int main(void) {
    size_t pages = 2560, size = pages * 4096;            /* 10 MiB */
    long f0 = minor_faults();
    char *p = mmap(NULL, size, PROT_READ | PROT_WRITE, MAP_PRIVATE | MAP_ANONYMOUS, -1, 0);
    if (p == MAP_FAILED) { perror("mmap"); return 1; }
    long f1 = minor_faults();
    for (size_t i = 0; i < size; i += 4096) p[i] = 1;    /* first touch of each page */
    long f2 = minor_faults();
    for (size_t i = 0; i < size; i += 4096) p[i] = 2;    /* second touch */
    long f3 = minor_faults();
    printf("faults during mmap of %zu pages: %ld\n", pages, f1 - f0);
    printf("faults on first touch:          %ld\n", f2 - f1);
    printf("faults on second touch:         %ld\n", f3 - f2);
    munmap(p, size);
    return 0;
}$ gcc -O0 -Wall -g toy.c -o toy $ ./toy faults during mmap of 2560 pages: 0 faults on first touch: 2560 faults on second touch: 0
Demand paging also explains why Linux can promise more memory than it has, overcommit. A program can mmap many gigabytes, and the kernel only needs frames for the pages actually touched. If touched memory exceeds physical memory plus swap, the kernel's out-of-memory (OOM) killer chooses a process to terminate, preferring large, recently started, low-priority ones. Containers use memory cgroups to set per-group limits, so a runaway container is killed without affecting others (Lesson 12).
Page replacement
When a fault occurs and no frame is free, the kernel must evict a page, the victim. If the victim is dirty (modified since loading), it must first be written back to its file or to swap space; a clean page can simply be dropped and read again later. A good replacement algorithm evicts pages that will not be needed soon, minimizing future faults. Algorithms are compared by running them on a reference string, the sequence of pages a program accesses.
The optimal algorithm (OPT, also called MIN or Belady's algorithm) evicts the page whose next use is furthest in the future. It is provably the best possible but needs knowledge of the future, so it serves only as a yardstick. First-in, first-out (FIFO) evicts the page loaded longest ago, regardless of use; it is simple and poor. Least recently used (LRU) evicts the page whose last use is furthest in the past, using the past as a predictor of the future, which works well because of locality. Exact LRU needs to update a timestamp or list on every memory access, which is far too expensive, so kernels approximate it.
# Page replacement: FIFO, LRU, OPT and Clock on the same reference string
from collections import OrderedDict, deque
refs = [7, 0, 1, 2, 0, 3, 0, 4, 2, 3, 0, 3, 2, 1, 2, 0, 1, 7, 0, 1]
def fifo(refs, n):
    frames, q, faults = set(), deque(), 0
    for r in refs:
        if r not in frames:
            faults += 1
            if len(frames) == n: frames.discard(q.popleft())
            frames.add(r); q.append(r)
    return faults
def lru(refs, n):
    frames, faults = OrderedDict(), 0
    for r in refs:
        if r in frames: frames.move_to_end(r)
        else:
            faults += 1
            if len(frames) == n: frames.popitem(last=False)
            frames[r] = True
    return faults
def opt(refs, n):
    frames, faults = set(), 0
    for i, r in enumerate(refs):
        if r in frames: continue
        faults += 1
        if len(frames) == n:
            future = refs[i + 1:]
            victim = max(frames, key=lambda p: future.index(p) if p in future else 10**9)
            frames.discard(victim)
        frames.add(r)
    return faults
def clock(refs, n):
    frames, refbit, hand, faults = [None] * n, [0] * n, 0, 0
    for r in refs:
        if r in frames:
            refbit[frames.index(r)] = 1; continue
        faults += 1
        while refbit[hand]:                 # give a second chance to recently used pages
            refbit[hand] = 0; hand = (hand + 1) % n
        frames[hand], refbit[hand] = r, 1
        hand = (hand + 1) % n
    return faults
print(f"{len(refs)} references, 3 frames")
for name, f in (("FIFO", fifo), ("LRU", lru), ("Clock", clock), ("OPT", opt)):
print(f" {name:<5} {f(refs, 3):>2} page faults")20 references, 3 frames FIFO 15 page faults LRU 12 page faults Clock 14 page faults OPT 9 page faults
The Clock algorithm (second chance) is the classic LRU approximation. Frames sit in a circle with a pointer, the clock hand. Each frame has a reference bit that the hardware sets when the page is accessed (the accessed bit from Lesson 8). To find a victim, the kernel looks at the frame under the hand: if its reference bit is 1, the page was used recently, so the kernel clears the bit and moves on, giving it a second chance; if the bit is 0, the page becomes the victim. An enhanced version also prefers clean pages over dirty ones, since evicting a clean page costs no write.
FIFO has a strange flaw discovered by László Belady in 1969: for some reference strings, giving it more frames causes more faults. LRU and OPT are stack algorithms, for which the set of pages in memory with n frames is always a subset of the set with n + 1 frames, so they can never suffer this anomaly.
# Belady's anomaly: with FIFO, more frames can cause MORE faults
from collections import deque
def fifo(refs, n):
    frames, q, faults = set(), deque(), 0
    for r in refs:
        if r not in frames:
            faults += 1
            if len(frames) == n: frames.discard(q.popleft())
            frames.add(r); q.append(r)
    return faults
refs = [1, 2, 3, 4, 1, 2, 5, 1, 2, 3, 4, 5]
for n in (1, 2, 3, 4, 5):
print(f"FIFO with {n} frames: {fifo(refs, n):>2} faults")FIFO with 1 frames: 12 faults FIFO with 2 frames: 12 faults FIFO with 3 frames: 9 faults FIFO with 4 frames: 10 faults FIFO with 5 frames: 5 faults
Real kernels use refined versions of these ideas. Linux keeps active and inactive lists of pages and, since kernel 6.1, offers the multi-generational LRU (MGLRU), which groups pages into several age generations using accessed bits scanned periodically, improving decisions under memory pressure; Android and ChromeOS adopted it early. Linux also distinguishes file-backed pages, which can be dropped and re-read from their files, from anonymous pages (heap and stack), which must go to swap space. The tunable vm.swappiness sets the balance between the two.
Locality, working sets and thrashing
Virtual memory works because programs exhibit locality: at any time, a program uses only a small part of its address space intensively, such as the current function's code, its stack frame and the data structures it is working on. Peter Denning's working-set model makes this precise: the working set of a process is the set of pages it referenced in the last Δ references (or time window). If every running process's working set fits in memory, faults are rare. If the total working sets exceed memory, processes keep evicting each other's pages and spend most of their time waiting for the disk. This is thrashing: processor utilization collapses even though the system is very busy.
# Working sets and thrashing: total demand vs available frames
import random
random.seed(379)
procs = {"browser": 220, "IDE": 180, "compiler": 140, "database": 300, "video call": 160}   # working sets (MiB)
ram = 900
running = []
for name, ws in procs.items():
    running.append(name)
    demand = sum(procs[p] for p in running)
    status = "fits" if demand <= ram else "THRASHING: suspend or swap out a process"
    print(f"+ {name:<10} working sets total {demand:>4} MiB of {ram} MiB -> {status}")
# CPU utilization model: as demand exceeds RAM, time goes to paging instead of computing
print()
for over in (0.8, 1.0, 1.1, 1.3, 1.6):
    util = 0.95 if over <= 1 else max(0.05, 0.95 / (1 + 12 * (over - 1)))
print(f"demand {over:.0%} of RAM -> CPU doing useful work about {util:.0%} of the time")+ browser working sets total 220 MiB of 900 MiB -> fits + IDE working sets total 400 MiB of 900 MiB -> fits + compiler working sets total 540 MiB of 900 MiB -> fits + database working sets total 840 MiB of 900 MiB -> fits + video call working sets total 1000 MiB of 900 MiB -> THRASHING: suspend or swap out a process demand 80% of RAM -> CPU doing useful work about 95% of the time demand 100% of RAM -> CPU doing useful work about 95% of the time demand 110% of RAM -> CPU doing useful work about 43% of the time demand 130% of RAM -> CPU doing useful work about 21% of the time demand 160% of RAM -> CPU doing useful work about 12% of the time
Classic batch systems sometimes made thrashing worse: seeing low processor utilization, they admitted more jobs, which increased faults further. The cure is the opposite: reduce the number of active processes until their working sets fit, by suspending or swapping out whole processes, or by adding memory. Kernels watch fault rates and memory pressure to detect this. Linux exposes pressure stall information (PSI) in /proc/pressure/memory, which reports the share of time tasks stall waiting for memory and which tools such as systemd-oomd use to act before the system becomes unusable.
Memory-mapped files and the page cache
The same machinery that pages a process's memory to and from disk also serves files. The kernel caches recently used file data in the page cache, using otherwise free memory, so reading a file a second time usually comes from memory. A program can also map a file directly into its address space with mmap; reading the mapped memory faults in file pages on demand, and writes to a shared mapping eventually go back to the file. This is how the dynamic loader maps shared libraries and how databases such as LMDB access their data. On Linux, free memory reported by tools often looks small because the page cache uses it; that memory is instantly reclaimable when programs need it.
Allocating kernel memory
The kernel needs memory for its own data structures: process control blocks, page tables, file objects and network buffers. It cannot page most of this memory out, and many structures need physically contiguous memory (for example buffers for devices that use direct memory access). Linux's buddy allocator manages physical memory in power-of-two blocks of pages. A request is rounded up to a power of two; a larger free block is repeatedly split in half until the size fits; when a block is freed, it merges with its buddy (the other half of the block it was split from) if the buddy is also free. Splitting and merging are fast, and the buddy's address is found with a single exclusive-or, but rounding up wastes memory internally.
# A buddy allocator over 1 MiB: blocks split in halves; freed buddies merge back
SIZE = 1024                     # KiB
free = {SIZE: [0]}               # block size -> list of offsets
def alloc(kib):
    size = 1
    while size < kib: size *= 2
    s = size
    while s <= SIZE and not free.get(s): s *= 2
    if s > SIZE: return None
    off = free[s].pop(0)
    while s > size:                          # split until the block fits
        s //= 2; free.setdefault(s, []).append(off + s)
    return off, size
def release(off, size):
    while size < SIZE:
        buddy = off ^ size                   # the buddy's address differs in one bit
        if buddy in free.get(size, []):
            free[size].remove(buddy); off = min(off, buddy); size *= 2
        else: break
    free.setdefault(size, []).append(off)
a = alloc(100); b = alloc(240); c = alloc(64)
print("A wants 100 KiB ->", a, "| B wants 240 KiB ->", b, "| C wants 64 KiB ->", c)
print("internal waste:", (a[1] - 100) + (b[1] - 240) + (c[1] - 64), "KiB")
print("free lists:", {k: sorted(v) for k, v in sorted(free.items()) if v})
release(*a); release(*c); release(*b)
print("after freeing all three:", {k: sorted(v) for k, v in sorted(free.items()) if v})A wants 100 KiB -> (0, 128) | B wants 240 KiB -> (256, 256) | C wants 64 KiB -> (128, 64)
internal waste: 44 KiB
free lists: {64: [192], 512: [512]}
after freeing all three: {1024: [0]}For the many small objects of fixed types, Linux uses slab allocation on top of the buddy allocator (the current implementation is called SLUB). A slab is one or more pages carved into objects of one type, such as task_struct or inode. Freed objects stay in their slab ready for reuse, already the right size and often still in the processor cache, so allocation is fast and fragmentation is low. User-space allocators such as glibc's malloc, jemalloc and tcmalloc apply similar ideas: size classes, per-thread caches and large allocations served directly with mmap.
Worked examples
Worked problem
Effective access time with page faults
Memory access takes 100 ns and a major page fault takes 8 ms. What fault rate keeps the slowdown under 10 percent?
Show solution
- EAT = (1 - p) x 100 ns + p x 8,000,000 ns.
- For at most a 10 percent slowdown, EAT must be at most 110 ns.
- 100 + p x (8,000,000 - 100) at most 110 gives p at most 10 / 7,999,900, about 1.25 x 10^-6.
- Fewer than one access in 800,000 may cause a major fault, which is why locality and enough memory matter so much.
Answer: Fewer than about 1 fault in 800,000 accesses.
Worked problem
Tracing LRU by hand
Trace LRU with 3 frames on 1, 2, 3, 4, 1, 2, 5, 1, 2, 3, 4, 5 and count the faults.
Show solution
- 1, 2, 3 fault (3); 4 faults and evicts 1 (4); 1 faults and evicts 2 (5); 2 faults and evicts 3 (6).
- 5 faults and evicts 4 (7); 1 and 2 hit.
- 3 faults and evicts 5 (8); 4 faults and evicts 1 (9); 5 faults and evicts 2 (10).
- LRU makes 10 faults here; with 4 frames it makes 8, never more, because it is a stack algorithm.
Answer: 10 faults with 3 frames.
Worked problem
Diagnosing a slow server
A server becomes very slow after a new service is deployed. vmstat shows high si and so (swap in and out) columns, processor time mostly waiting on input and output, and little idle memory. What is happening and what are the options?
Show solution
- Heavy swap traffic with processors waiting on input and output is the signature of thrashing: total working sets exceed memory.
- Options: add memory, move the new service to another machine, reduce caches or limits in the services, or set memory cgroup limits so one service cannot push others out.
- Check the PSI memory pressure figures to confirm and to monitor the fix.
Answer: Thrashing; reduce total working sets or add memory, and confirm with PSI.
Common mistakes
MistakeA page fault means the program has a bug.
InsteadMost page faults are normal demand paging handled invisibly by the kernel; only invalid addresses cause SIGSEGV.
MistakeMore frames always mean fewer faults.
InsteadFIFO can suffer Belady's anomaly; LRU and OPT cannot.
MistakeReal kernels implement exact LRU.
InsteadExact LRU is too costly; kernels approximate it with reference bits, Clock and generational lists.
MistakeLow processor utilization means the system needs more processes.
InsteadIf it is caused by thrashing, adding processes makes it worse; reduce the load.
MistakeLittle free memory means the system is short of memory.
InsteadLinux uses spare memory for the page cache, which is reclaimed instantly; look at available memory and pressure stalls.
Summary and key terms
- Demand paging loads pages only when first touched; page faults are handled by the kernel and the instruction restarts.
- Minor faults need no disk access; major faults read from disk and cost thousands of times more.
- Replacement algorithms choose victims: OPT is ideal, FIFO is poor and suffers Belady's anomaly, and LRU is approximated by Clock and generational lists.
- Dirty pages must be written back before eviction; clean pages can be dropped.
- Locality makes virtual memory work; when total working sets exceed memory, the system thrashes.
- The page cache and memory-mapped files use the same paging machinery for file data.
- The kernel allocates physical memory with the buddy allocator and small objects with slab allocation.
- Virtual memory
- Separating a process's address space from physical memory so pages can reside on disk.
- Demand paging
- Loading a page only when it is first accessed.
- Page fault
- A trap caused by accessing a page that is not present or not permitted.
- Major fault
- A page fault that requires reading from disk.
- Victim page
- The page chosen for eviction.
- LRU
- Least recently used replacement.
- Clock algorithm
- An LRU approximation that gives referenced pages a second chance.
- Belady's anomaly
- More frames causing more page faults under FIFO.
- Working set
- The pages a process has used in a recent window.
- Thrashing
- Excessive paging that leaves little time for useful work.
Practice problems
Work each problem on paper first, then reveal the answer to check.
What happens to the faulting instruction after the kernel handles a valid page fault?
Show answer
It is restarted and now succeeds.
Why did mmap of 10 MiB cause no page faults?
Show answer
Demand paging: mmap only reserves address space; frames are assigned on first touch.
What is the difference between a minor and a major fault?
Show answer
A minor fault needs no disk access; a major fault reads the page from disk.
Which algorithm is optimal, and why is it not used?
Show answer
OPT; it requires knowing future references.
How does the Clock algorithm approximate LRU?
Show answer
It skips pages whose reference bit is set, clearing the bit, and evicts the first page found with the bit clear.
In the simulation, how many faults did FIFO, LRU and OPT make?
Show answer
FIFO 15, LRU 12 and OPT 9, with Clock 14.
What is Belady's anomaly?
Show answer
For FIFO, adding frames can increase the number of page faults.
What is thrashing and how is it fixed?
Show answer
Excessive paging when working sets exceed memory; fix by reducing active processes or adding memory.
Why can a clean page be evicted faster than a dirty one?
Show answer
A clean page matches its copy on disk, so it can be dropped without writing.
How does the buddy allocator find a block's buddy?
Show answer
By flipping the bit of the address corresponding to the block size (exclusive-or with the size).
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.