
CMPUT-229 · Lesson 2 of 12 · 30 min
Data representation I: integers and arithmetic
Inside a computer, everything is a pattern of bits. Whether a 32-bit pattern means a positive count, a negative temperature, four characters of text or an instruction depends entirely on how the program interprets it. CMPUT-174 lesson 2 introduced binary, hexadecimal and the two's complement representation of negative numbers. This lesson goes further, looking at integers the way the hardware does: fixed widths, the arithmetic that wraps around at the ends of the range, the difference between carry and overflow, sign and zero extension, shifts and masks, and how multiplication and division are carried out. Along the way you will see how RISC-V handles these questions, which in some respects differs from the x86-64 and Arm processors you may have read about.
Fixed-width integers
Python integers grow as large as they need to, but hardware integers have a fixed number of bits. RISC-V RV32I registers hold 32 bits; memory can be read and written in units of 8 bits (a byte), 16 bits (a halfword) and 32 bits (a word). With \(n\) bits there are \(2^n\) distinct patterns. Interpreted as unsigned integers, they represent 0 to \(2^n - 1\). For 8 bits that is 0 to 255; for 32 bits it is 0 to 4,294,967,295.
Hexadecimal is the natural notation for bit patterns because each hexadecimal digit stands for exactly four bits. The 32-bit pattern 1101 1110 1010 1101 1011 1110 1110 1111 is much easier to read and type as 0xDEADBEEF. Assemblers, debuggers and this course write hexadecimal with the prefix 0x. Converting between binary and hexadecimal is just a matter of grouping bits in fours from the right; converting either to decimal means summing powers of two, \(\sum b_i 2^i\).
Two's complement, and why it works
Nearly every computer represents signed integers in two's complement. In an \(n\)-bit two's complement number, the most significant bit has weight \(-2^{n-1}\) instead of \(+2^{n-1}\); all other bits keep their positive weights. So the 8-bit pattern 1111 1011 is \(-128 + 64 + 32 + 16 + 8 + 2 + 1 = -5\). The range is \(-2^{n-1}\) to \(2^{n-1} - 1\): for 32 bits, −2,147,483,648 to 2,147,483,647. There is exactly one zero, and there is one more negative value than positive values, so negating the most negative number gives back the same number.
The reason two's complement won is that addition and subtraction work identically for signed and unsigned numbers. Arithmetic on \(n\) bits is arithmetic modulo \(2^n\): the result keeps only the low \(n\) bits. In that modular world, \(-x\) and \(2^n - x\) are the same number, and two's complement simply chooses to call the upper half of the patterns negative. The same adder circuit therefore serves both kinds of number, and the hardware never needs to know which one the programmer meant. Negation is computed by inverting every bit and adding 1, because \(x + \overline{x} = 2^n - 1\), so \(\overline{x} + 1 = 2^n - x \equiv -x\).
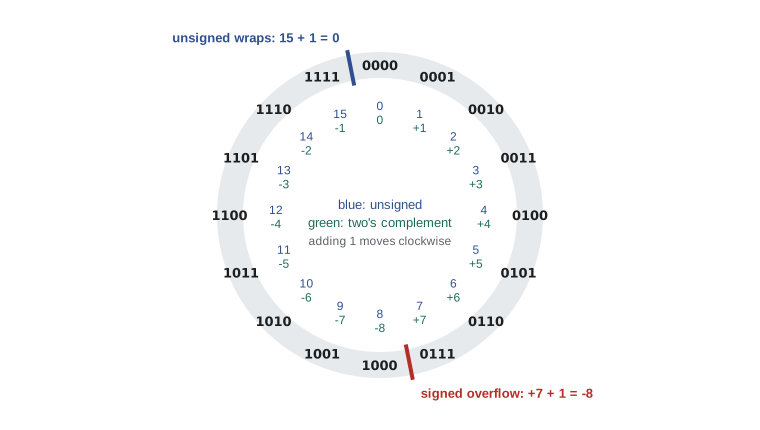
The wheel in the figure makes the modular nature visible. Adding 1 moves one step clockwise. Unsigned values wrap from 15 back to 0 at the bottom of the circle; signed values jump from +7 to −8 at the top. These two places are where the two kinds of arithmetic go wrong, and they are different places, which is why the hardware distinguishes two separate error conditions.
Carry and overflow are different
When an unsigned addition produces a result that does not fit, a carry comes out of the most significant bit; the true sum is the stored result plus \(2^n\). When a signed addition produces a result outside the signed range, we call it overflow, and the stored result has the wrong sign. Overflow in signed addition can only happen when both operands have the same sign, and it is detected exactly when the result's sign differs from theirs. Adding a positive and a negative number can never overflow.
Many processors record these conditions in a flags register after every arithmetic instruction. x86-64 has a carry flag (CF), an overflow flag (OF), a sign flag (SF) and a zero flag (ZF); Arm calls the same four flags C, V, N and Z. Conditional branches then test the flags. The following simulation computes the four flags for 8-bit additions, as an x86-64 or Arm processor would.
def add8(a, b):
    """Add two 8-bit patterns; return the result and the four condition flags."""
    total = a + b
    r = total & 0xFF
    c = total > 0xFF                       # carry out: unsigned result wrapped
    sa, sb, sr = a >> 7, b >> 7, r >> 7    # sign bits
    v = sa == sb and sr != sa              # overflow: signed result wrapped
    return r, dict(C=int(c), V=int(v), N=sr, Z=int(r == 0))

def signed(x):
    return x - 256 if x & 0x80 else x

for a, b in [(100, 27), (100, 28), (200, 100), (0xF0, 0x10), (0x90, 0x90)]:
    r, f = add8(a, b)
    print(f'{a:3d}+{b:3d} -> {r:3d} (0x{r:02X})  unsigned {a + b:3d}->{r:3d}  '
f'signed {signed(a):4d}+{signed(b):4d} -> {signed(r):4d} {f}')100+ 27 -> 127 (0x7F) unsigned 127->127 signed 100+ 27 -> 127 {'C': 0, 'V': 0, 'N': 0, 'Z': 0}
100+ 28 -> 128 (0x80) unsigned 128->128 signed 100+ 28 -> -128 {'C': 0, 'V': 1, 'N': 1, 'Z': 0}
200+100 -> 44 (0x2C) unsigned 300-> 44 signed -56+ 100 -> 44 {'C': 1, 'V': 0, 'N': 0, 'Z': 0}
240+ 16 -> 0 (0x00) unsigned 256-> 0 signed -16+ 16 -> 0 {'C': 1, 'V': 0, 'N': 0, 'Z': 1}
144+144 -> 32 (0x20) unsigned 288-> 32 signed -112+-112 -> 32 {'C': 1, 'V': 1, 'N': 0, 'Z': 0}Read the rows carefully. 100 + 28 sets V but not C: as unsigned numbers the result 128 is correct, but as signed numbers +100 plus +28 has produced −128. 200 + 100 sets C but not V: as signed numbers it is −56 + 100 = 44, which is correct, but the unsigned result has wrapped. 0xF0 + 0x10 sets C and Z: unsigned 240 + 16 wraps to 0, while as signed numbers −16 + 16 = 0 is right. 0x90 + 0x90 sets both C and V. The hardware cannot know which interpretation you meant, so it reports both.
RISC-V takes a different approach: it has no flags register at all. Arithmetic instructions never trap and never record carry or overflow. Instead, programs that need to detect these conditions compute them explicitly with comparison instructions. This keeps the processor simpler, especially in fast out-of-order designs where a single shared flags register creates dependencies between otherwise unrelated instructions. The RISC-V specification gives short instruction sequences for the common checks. For unsigned addition, a carry occurred exactly when the sum is less than either operand. For signed addition, overflow occurred when the sign of the second operand disagrees with whether the sum is less than the first operand.
    .data
nl: .asciz "\n"
    .text
    .globl main
main:
    li   s0, 0x7FFFFFF0      # a large positive signed value
    li   s1, 0x20            # 32
    add  s2, s0, s1          # wraps to a negative number
    # signed overflow check from the RISC-V specification:
    slti t0, s1, 0           # t0 = (s1 < 0)
    slt  t1, s2, s0          # t1 = (sum < s0)
    xor  s3, t0, t1          # s3 = 1 if signed overflow
    li   s4, 0xFFFFFFF0      # 4294967280 as unsigned
    add  s5, s4, s1          # unsigned wrap to 16
    sltu s6, s5, s4          # s6 = 1 if unsigned carry out
    mv   a0, s2
    li   a7, 1               # print the signed sum
    ecall
    la   a0, nl
    li   a7, 4
    ecall
    li   a7, 10
ecall-2147483632 s2 = -2147483632 (0x80000010) s3 = 1 (0x00000001) s5 = 16 (0x00000010) s6 = 1 (0x00000001)
The register dump after the program shows the wrapped signed sum in s2, the overflow indicator 1 in s3, the wrapped unsigned sum 16 in s5 and the carry indicator 1 in s6. Each check costs two or three extra instructions, which compilers add only when the source language requires the check.
Programming languages handle overflow in different ways. In C, unsigned arithmetic is defined to wrap modulo \(2^n\), but signed overflow is undefined behavior, which lets compilers assume it never happens and optimize accordingly; CMPUT-201 lesson 3 showed the sanitizer catching it. Java wraps signed integers silently. Rust checks for overflow in debug builds and wraps in release builds unless you ask otherwise, and Python avoids the issue by using arbitrary-precision integers. The famous failure of the first Ariane 5 rocket in 1996 began with an unhandled overflow when a 64-bit floating-point value was converted to a 16-bit signed integer.
Extension: making numbers wider
When a narrow value is loaded into a wide register, the upper bits must be filled in. For unsigned values, zero extension fills them with zeros. For signed values, sign extension copies the sign bit into every new position, which preserves the value: the 8-bit pattern 1111 1011 (−5) becomes the 32-bit pattern 0xFFFFFFFB, still −5. RISC-V provides both kinds of load for sub-word data: lb and lh sign-extend a byte or halfword, while lbu and lhu zero-extend. Choosing the wrong one is a classic bug: reading a byte holding 0xF0 with lb gives −16, while lbu gives 240.
    .data
val: .byte 0xF0, 0x7F
    .text
    .globl main
main:
    la   t0, val
    lb   s0, 0(t0)        # sign-extend 0xF0
    lbu  s1, 0(t0)        # zero-extend 0xF0
    lb   s2, 1(t0)        # 0x7F has sign bit 0: both give 127
    lbu  s3, 1(t0)
    li   a7, 10
ecalls0 = -16 (0xfffffff0) s1 = 240 (0x000000f0) s2 = 127 (0x0000007f) s3 = 127 (0x0000007f)
Immediates are sign-extended too. A RISC-V I-type instruction carries a 12-bit immediate, which the hardware sign-extends to 32 bits before use, so addi can add any constant from −2,048 to 2,047. Lesson 5 shows how larger constants are built from two instructions.
Shifts, masks and bit fields
Shifting a binary number left by \(k\) places multiplies it by \(2^k\), and shifting right divides it. RISC-V provides three shifts: sll (shift left logical), srl (shift right logical, filling with zeros) and sra (shift right arithmetic, filling with copies of the sign bit), each with an immediate form: slli, srli and srai. Logical right shift is the right choice for unsigned values; arithmetic right shift preserves the sign of two's complement values. There is a subtlety: an arithmetic right shift rounds toward negative infinity, so −7 shifted right by 1 gives −4, while integer division in C, Java and RISC-V's div instruction rounds toward zero, giving −3. A compiler that turns x / 2 into a shift must add a correction for negative x.
int half(int x) {
    return x / 2;          /* signed division rounds toward zero */
}

unsigned uhalf(unsigned x) {
    return x / 2;          /* unsigned: a plain logical shift */
}$ clang --target=riscv32 -march=rv32im -O1 -S half.c -o -
half:
srli a1, a0, 31
add a0, a0, a1
srai a0, a0, 1
ret
uhalf:
srli a0, a0, 1
retThe unsigned version is a single srli. The signed version extracts the sign bit with srli by 31, adds it to x, and only then shifts arithmetically. For negative x this adds 1 before the shift, which converts rounding toward negative infinity into rounding toward zero. Compilers know dozens of such tricks, which is why it is rarely worth replacing division by a constant with a shift yourself: the compiler already does it, correctly.
Bitwise operations, and, or, xor and not, operate on each bit position independently. Combined with shifts, they let you pack several small fields into one word and pull them out again. To extract bits 4 to 7 of a value, shift right by 4 and and with the mask 0xF. To set those bits to a new value v, clear them with and ~(0xF << 4), then or in (v << 4). Instruction encodings, network packet headers, file formats and hardware device registers all use bit fields, and lesson 5 decodes RISC-V instructions this way.
def get_field(word, lo, width):
    """Return the unsigned value of bits lo .. lo+width-1."""
    return (word >> lo) & ((1 << width) - 1)

def set_field(word, lo, width, value):
    mask = ((1 << width) - 1) << lo
    return (word & ~mask) | ((value << lo) & mask)

# A 16-bit pixel in RGB565 format: 5 bits red, 6 green, 5 blue
pixel = 0b11111_101000_00011
r, g, b = get_field(pixel, 11, 5), get_field(pixel, 5, 6), get_field(pixel, 0, 5)
print(f'pixel 0x{pixel:04X}: red {r}/31, green {g}/63, blue {b}/31')
pixel = set_field(pixel, 5, 6, 0)          # remove the green component
print(f'after clearing green: 0x{pixel:04X} = {pixel:016b}')pixel 0xFD03: red 31/31, green 40/63, blue 3/31 after clearing green: 0xF803 = 1111100000000011
Multiplication
Multiplying two \(n\)-bit numbers can produce a result of up to \(2n\) bits. The simplest hardware algorithm mirrors long multiplication by hand, but in binary each partial product is either zero or a shifted copy of the multiplicand, so multiplication becomes a sequence of shifts and additions. A simple sequential multiplier takes one cycle per bit; modern processors build a tree of adders that sums all the partial products in parallel and finish a 32-bit multiply in three or four cycles.
def shift_add_multiply(a, b, bits=8):
    """Unsigned multiplication by shifting and adding, as a simple multiplier does."""
    product, steps = 0, 0
    for i in range(bits):
        if (b >> i) & 1:               # this bit of the multiplier is 1
            product += a << i          # add the shifted multiplicand
            steps += 1
    return product, steps

for a, b in [(13, 11), (200, 255), (7, 1)]:
    p, adds = shift_add_multiply(a, b)
    print(f'{a} x {b} = {p} ({adds} additions, fits in 8 bits: {p < 256}, '
f'needs {max(p.bit_length(), 1)} bits)')13 x 11 = 143 (3 additions, fits in 8 bits: True, needs 8 bits) 200 x 255 = 51000 (8 additions, fits in 8 bits: False, needs 16 bits) 7 x 1 = 7 (1 additions, fits in 8 bits: True, needs 3 bits)
Because the full product needs twice as many bits, the RISC-V M extension splits multiplication into separate instructions. mul returns the low 32 bits of the product, which is the same for signed and unsigned operands. mulh, mulhu and mulhsu return the high 32 bits, treating the operands as both signed, both unsigned, or signed by unsigned. To get the full 64-bit product, a program uses mulh and mul on the same operands, and processors are encouraged to recognize the pair and compute it once. Multiplication by a constant is often replaced by shifts and adds: x × 10 is (x << 3) + (x << 1).
Division
Division is the slowest integer operation, typically taking 10 to 40 cycles even on fast processors, because each quotient bit depends on the previous ones. RISC-V offers div and divu for the quotient and rem and remu for the remainder. Signed division rounds toward zero, and the remainder has the sign of the dividend, so −7 / 2 = −3 with remainder −1, matching C. RISC-V never traps on division: dividing by zero returns a quotient with every bit set and leaves the dividend as the remainder, and the one overflowing case, the most negative number divided by −1, returns the dividend. Software must check for these cases if it cares about them; C compilers do not insert the checks, because C makes division by zero undefined.
    .text
    .globl main
main:
    li   t0, -7
    li   t1, 2
    div  s0, t0, t1       # rounds toward zero
    rem  s1, t0, t1       # remainder has the sign of the dividend
    srai s2, t0, 1        # arithmetic shift rounds toward minus infinity
    li   t2, 0
    div  s3, t0, t2       # division by zero does not trap
    rem  s4, t0, t2
    li   a7, 10
ecalls0 = -3 (0xfffffffd) s1 = -1 (0xffffffff) s2 = -4 (0xfffffffc) s3 = -1 (0xffffffff) s4 = -7 (0xfffffff9)
Worked problem
Checking a remainder by hand
Verify the RISC-V results for −7 / 2 and for division by zero shown above.
Show solution
- Rounding −3.5 toward zero gives −3, which matches s0.
- The remainder satisfies dividend = divisor × quotient + remainder: −7 = 2 × (−3) + r, so r = −1, matching s1.
- srai by 1 computes floor(−7 / 2) = floor(−3.5) = −4, matching s2.
- For division by zero the specification fixes the quotient as all ones, which reads as −1 in two's complement, and the remainder as the dividend, −7.
Answer: All five register values agree with the definitions: −3, −1, −4, −1 (0xFFFFFFFF) and −7.
| Instruction | Operation | Notes |
|---|---|---|
| add, sub | Sum and difference modulo 2³² | Same instruction for signed and unsigned; no flags, no traps |
| slt, sltu | Set to 1 if less than (signed, unsigned) | Used to detect overflow and carry |
| sll, srl, sra | Shift left, right logical, right arithmetic | Shift amount is the low 5 bits of rs2 |
| and, or, xor | Bitwise operations | No not instruction: xori rd, rs, -1 inverts all bits |
| mul, mulh, mulhu, mulhsu | Low and high halves of the 64-bit product | M extension |
| div, divu, rem, remu | Quotient and remainder | M extension; division by zero returns −1 and the dividend |
| lb, lbu, lh, lhu | Load byte or halfword with sign or zero extension | lw loads a full word |
Why this matters for programmers
These details are not only for compiler writers. Binary search implementations around the world contained a bug for decades because they computed the midpoint as (low + high) / 2, which overflows when low + high exceeds the largest signed int; the fix is low + (high − low) / 2. Comparisons that mix signed and unsigned values in C convert the signed one to unsigned, so −1 < 1u is false. Hash functions and checksums deliberately rely on wraparound. Network protocols send multi-byte integers in a defined byte order, a subject for lesson 3. Knowing the representation lets you predict all of these behaviors rather than discover them in production.
Common mistakes
MistakeThinking the carry flag indicates signed overflow.
InsteadCarry means the unsigned result wrapped; overflow means the signed result wrapped. Either can occur without the other.
MistakeLoading a signed byte with lbu or an unsigned byte with lb.
InsteadUse lb or lh for signed data, which sign-extends, and lbu or lhu for unsigned data, which zero-extends.
MistakeReplacing x / 2 with x >> 1 for signed integers.
InsteadAn arithmetic shift rounds toward negative infinity; division rounds toward zero. Let the compiler do it, with its correction.
MistakeExpecting RISC-V to trap on overflow or division by zero.
InsteadRISC-V never traps on integer arithmetic; software must test for these conditions with explicit instructions.
MistakeComputing a midpoint as (low + high) / 2 with fixed-width integers.
InsteadUse low + (high − low) / 2, which cannot overflow when 0 ≤ low ≤ high.
Summary and key terms
- n bits give 2ⁿ patterns: 0 to 2ⁿ − 1 unsigned, or −2ⁿ⁻¹ to 2ⁿ⁻¹ − 1 in two's complement.
- Two's complement gives the top bit weight −2ⁿ⁻¹, so the same adder serves signed and unsigned arithmetic modulo 2ⁿ.
- Carry signals unsigned wraparound; overflow signals signed wraparound and occurs only when adding operands of the same sign.
- RISC-V has no flags register and never traps on integer arithmetic; overflow and carry are detected with slt and sltu.
- Sign extension copies the sign bit; zero extension fills with zeros; lb and lh sign-extend, lbu and lhu zero-extend.
- Logical shifts fill with zeros, arithmetic right shifts copy the sign bit and round toward negative infinity.
- A full product needs 2n bits, so RISC-V separates the low half (mul) from the high half (mulh, mulhu, mulhsu); division is slow and rounds toward zero.
- Two's complement
- The signed integer representation in which the most significant bit has weight −2ⁿ⁻¹.
- Carry
- A bit out of the most significant position, meaning an unsigned result did not fit.
- Overflow
- A signed result outside the representable range, detected by a sign change when adding same-sign operands.
- Flags register
- A register on x86-64 and Arm holding condition bits such as carry, overflow, sign and zero; RISC-V has none.
- Sign extension
- Widening a two's complement value by copying its sign bit into the new high bits.
- Zero extension
- Widening an unsigned value by filling the new high bits with zeros.
- Logical shift
- A shift that fills vacated bits with zeros.
- Arithmetic shift
- A right shift that fills vacated bits with copies of the sign bit.
- Mask
- A bit pattern used with and, or or xor to select, clear or flip particular bits.
- Halfword
- A 16-bit unit of data in RISC-V terminology; a word is 32 bits.
Practice problems
Work each problem on paper first, then reveal the answer to check.
What is the 8-bit two's complement pattern for −20?
Show answer
20 = 0001 0100; invert to 1110 1011 and add 1: 1110 1100 (0xEC).
What range of values can a 16-bit two's complement integer hold?
Show answer
−32,768 to 32,767.
Add the 8-bit patterns 0x7F and 0x01. Which of carry and overflow are set?
Show answer
The result is 0x80; overflow is set (127 + 1 gave −128) and carry is clear.
Add 0xFF and 0x01 in 8 bits. Which flags are set?
Show answer
The result is 0x00: carry and zero are set, overflow is clear (−1 + 1 = 0).
Sign-extend the 12-bit immediate 0x800 to 32 bits.
Show answer
0xFFFFF800, which is −2,048.
What does srai give for −9 shifted right by 2, and what does −9 / 4 give in C?
Show answer
srai gives floor(−2.25) = −3; C division gives −2, rounding toward zero.
Write a mask that selects bits 8 to 15 of a word.
Show answer
0x0000FF00, or equivalently 0xFF << 8.
Write RISC-V instructions to compute t0 = t1 × 9 without mul.
Show answer
slli t0, t1, 3 then add t0, t0, t1.
What does RISC-V divu return when dividing 100 by 0?
Show answer
The quotient 0xFFFFFFFF (all ones); remu would return the dividend 100.
Why can adding a positive and a negative number never overflow?
Show answer
The result lies between the two operands, so it is always inside the range they came from.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.