
AWS-112 · Lesson 10 of 12 · 18 min
Cost, latency and model selection trade-offs
▶ Video coming soon A video version of this lesson is on the way.
Lorraine Beaudry had waited nine lessons for her number. "What will the overnight summaries cost, and could a cheaper model do the job?" she asked as the tenth AI hour began. Dr. Kaur had a different number in mind: how long the summaries would take to appear. Gwen wanted to know whether the service would be available if one data center had a bad night.
Noor said all three questions belonged together, because cost, speed, quality and availability trade against each other in every generative AI decision. This lesson explains how token-based pricing works and what drives the bill, how latency is measured, the consumption options AWS offers for Amazon Bedrock and their trade-offs, and a structured way to choose a model using the selection factors in the exam guide: model type, performance requirements, capabilities, constraints, compliance, cost, latency and complexity.
How token-based pricing works
Most foundation model services, including on-demand use of Amazon Bedrock, charge per token, as lesson 2 introduced. Four facts about the pricing model explain most bills.
- Input and output are priced separately. Every token you send, including instructions, examples, retrieved documents and conversation history, is an input token. Every token the model writes is an output token. Output tokens usually cost several times as much as input tokens.
- Prices differ widely between models. A small, fast model can cost a small fraction of what the largest model from the same provider costs per token.
- Prices are quoted per thousand or per million tokens, so the arithmetic needs care with units.
- Other features add charges. Knowledge Bases storage and retrieval, Guardrails checks, embeddings, model customization and hosting of custom models all have their own prices.
Because input includes everything in the context, the biggest savings often come from context engineering rather than from bargaining over price: sending three relevant chunks instead of thirty pages, trimming instructions, and asking for concise output.
# Monthly cost estimate for overnight call summaries. All prices are ILLUSTRATIVE.
summaries_per_month = 3000
in_tokens = 250 + 150 + 500      # instructions + two examples + the call note
out_tokens = 180

models = {   # (input, output) USD per 1,000 tokens, illustrative only
    "small model": (0.00006, 0.00024),
    "mid-size model": (0.0008, 0.0032),
    "large model": (0.003, 0.015),
}
for name, (p_in, p_out) in models.items():
    per_call = in_tokens / 1000 * p_in + out_tokens / 1000 * p_out
print(f"{name:15} per summary {per_call:.5f} USD, per month {per_call * summaries_per_month:.2f} USD")small model per summary 0.00010 USD, per month 0.29 USD mid-size model per summary 0.00130 USD, per month 3.89 USD large model per summary 0.00540 USD, per month 16.20 USD
What this code does
It estimates the monthly cost of producing 3,000 call summaries by adding up the tokens sent to the model (instructions, examples and the call note) and the tokens it writes back. Each model's illustrative price per thousand tokens gives a cost per summary, which is multiplied by the monthly volume. The printout shows even the large model costs only a few dollars a month for this job.
Lorraine was surprised by how small the numbers were at the group's volume. Noor pointed out the two ways such costs grow unnoticed: volume, if every clinic starts using a tool for everything, and context, if someone adds an entire medical history to every request. Lorraine asked for a monthly budget alert on the account, which Gwen set up with AWS Budgets and cost allocation tags for the AI project.
Latency
Latency is how long a user waits. For generative models it has two parts that are worth separating.
- Time to first token: how long until the response starts appearing. It depends on the model, the load, and how much input must be processed first, so long contexts increase it.
- Output speed: how many tokens per second the model produces once it starts. Since output is generated one token at a time, a long answer takes proportionally longer.
Streaming sends tokens to the user as they are generated, so people see the answer start quickly even if it takes several seconds to finish. Chat interfaces almost always stream. The overnight summaries do not need streaming at all, because nobody is waiting for them in real time; they need to be ready by the morning handover.
# Rough response time = time to first token + output tokens / output speed. Illustrative values.
cases = [("small model", 0.3, 150), ("mid-size model", 0.6, 90), ("large model", 1.2, 50)]
for out_tokens in (60, 400):
    for name, ttft, tok_per_s in cases:
        total = ttft + out_tokens / tok_per_s
print(f"{out_tokens:3} tokens, {name:15}: about {total:.1f} s")60 tokens, small model : about 0.7 s 60 tokens, mid-size model : about 1.3 s 60 tokens, large model : about 2.4 s 400 tokens, small model : about 3.0 s 400 tokens, mid-size model : about 5.0 s 400 tokens, large model : about 9.2 s
What this code does
It estimates response time as the time to the first token plus the number of output tokens divided by the model's output speed, using illustrative values for small, mid-size and large models. It prints the estimate for short and long answers. Larger models are slower to respond, and the gap grows with longer answers.
Consumption options in Amazon Bedrock
Bedrock offers several ways to pay for and run inference. Each trades cost against responsiveness, guaranteed capacity or flexibility.
| Option | How it works | Best for |
|---|---|---|
| On-demand | Pay per token with no commitment, using shared capacity | Most applications, especially with uneven or modest volume |
| Batch inference | Submit many requests as a job; results arrive later, at about half the on-demand price for supported models | Work that is not urgent, such as end-of-shift summaries |
| Service tiers | Standard, Priority and Flex tiers trade price against speed and priority; a Reserved tier is arranged with AWS | Matching urgency to price within on-demand use |
| Provisioned Throughput | Buy dedicated model units by the hour, with or without a 1-month or 6-month commitment | Steady high volume, guaranteed capacity, or hosting a customized model |
| Cross-Region inference | Route requests across a defined set of Regions for higher throughput and resilience | Absorbing bursts and surviving a Regional capacity shortfall, where data residency allows |
For the overnight summaries, batch inference was the natural fit: the notes accumulate overnight, and a batch job at the end of the shift can produce all the summaries before handover at a lower price. For the clinic managers' manual questions, on-demand with streaming suits people who are waiting at a screen. Provisioned Throughput would make sense only at much higher volume, or if the group fine-tuned a model, because customized models typically need dedicated capacity to run.
Gwen's availability question had an answer in the same table. Cross-Region inference spreads requests over several Regions, which improves resilience and throughput, but it sends processing to the Regions in the chosen profile. For Cascade Ridge, a US-only profile keeps the group's promise that client information stays in the United States.
Other cost levers
- Choose the smallest model that meets the bar. Test a small model first and move up only if it fails the evaluation.
- Reuse repeated context. Bedrock supports prompt caching for supported models, which reduces the cost and latency of sending the same long instructions or documents repeatedly.
- Route by difficulty. Intelligent prompt routing in Bedrock can send each request to a cheaper or more capable model in the same family depending on the request; a team can also route simple tasks to a small model in its own code.
- Limit output. A maximum output length and a request for concise answers cut the most expensive tokens.
- Customize carefully. Fine-tuning and distillation can let a smaller model do a specialized job well, but training and hosting add their own costs.
Choosing a model
The exam guide lists the factors to weigh when selecting a generative AI model. Noor turned them into questions for the summaries.
| Factor | Question for the overnight summaries |
|---|---|
| Model type and capabilities | Text in, text out; good at summarization and following a fixed format? |
| Performance requirements | Does it pass the evaluation set: every medication listed, hedges kept? |
| Constraints | Does the longest note fit the context window? Is it available in our Region? |
| Compliance | Do data handling terms and Region meet our privacy commitments? |
| Cost | What is the monthly cost at expected volume, with batch pricing? |
| Latency | Are summaries ready before handover? |
| Model complexity | Is a large model needed, or does a smaller one suffice and run faster? |
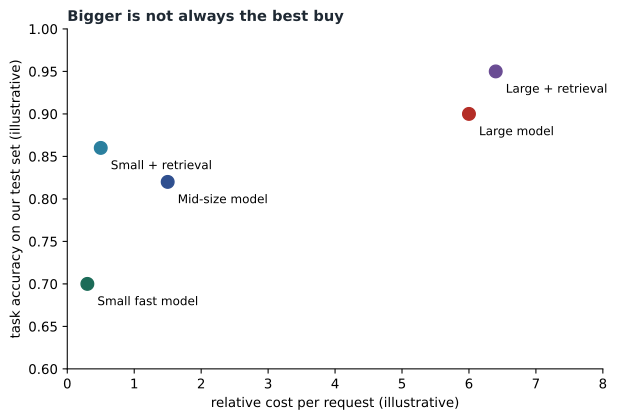
The illustrative chart makes a point the team found in its own tests: the gap between models often shrinks when the context is good. A small model with clear instructions and the right retrieved passages may meet the bar that a large model meets without them, at a fraction of the cost.
# Pick the cheapest model that passes every hard requirement. Illustrative test results.
candidates = [
    # name, eval score (of 50), monthly cost USD, in our Region, ready by handover
    ("small model", 41, 1.2, True, True),
    ("mid-size model", 47, 12.0, True, True),
    ("large model", 49, 55.0, False, True),
]
required_score = 46
ok = [c for c in candidates if c[1] >= required_score and c[3] and c[4]]
best = min(ok, key=lambda c: c[2])
print("passing:", [c[0] for c in ok])
print("choose:", best[0], "at about", best[2], "USD a month")passing: ['mid-size model'] choose: mid-size model at about 12.0 USD a month
What this code does
It filters candidate models by hard requirements: an evaluation score of at least 46 out of 50, availability in the required Region and readiness by the deadline. From the models that pass, it picks the one with the lowest monthly cost. Only the mid-size model meets every requirement, so it is chosen even though the large model scored higher.
In the illustrative results, the large model scored highest but was not offered in the group's Region, so it failed a hard constraint before cost was even considered. The mid-size model passed every requirement at modest cost. Noor reminded Jonah that the choice is provisional: the evaluation is re-run when new models or versions appear, and the group can switch with little work because Bedrock uses one API.
Common mistakes
MistakeCounting only the user's question as input tokens.
InsteadInstructions, examples, retrieved documents and history are all input tokens.
MistakeChoosing the largest model by default.
InsteadChoose the cheapest model that passes your evaluation and constraints.
MistakeUsing real-time on-demand calls for work nobody is waiting for.
InsteadBatch inference suits non-urgent work at a lower price.
MistakeTurning on cross-Region inference without checking where requests may go.
InsteadChoose an inference profile whose Regions match data residency commitments.
Watching costs after launch
Estimates are only the start. Once a tool is live, Gwen's standard AWS cost practices apply to generative AI as to anything else. Cost allocation tags on every Bedrock resource and application let Lorraine see the AI project's spending separately in Cost Explorer. AWS Budgets sends an alert when monthly spending passes a threshold, and Cost Anomaly Detection flags unusual jumps, such as a looping script calling a model thousands of times overnight. Bedrock invocation metrics in Amazon CloudWatch show the number of requests and tokens, so a cost change can be traced to its cause: more users, longer contexts, or longer answers.
Jonah added a simple efficiency metric to his weekly report: average input tokens and output tokens per request. If the average input grows, someone has probably added material to the context; if output grows, the length limit or the instructions may have drifted. Both are cheap to fix once noticed. Noor called this the generative AI version of checking the electricity meter: nobody needs to watch it every day, but everyone should know where it is and what normal looks like.
Balancing all four
Cost, latency, quality and availability rarely all improve together. A larger model raises quality and cost and usually latency. Batch processing lowers cost and removes any real-time response. Cross-Region inference raises availability but may conflict with data residency. Streaming improves perceived latency without changing cost. Good decisions start from the task's requirements, treat some of them, such as quality thresholds and data residency, as fixed, and then optimize the rest. For the overnight summaries, the fixed requirements were the clinical quality bar, the Region and readiness by handover; cost was then minimized within those limits.
Worked problem
Estimating a monthly bill
A manual question tool will handle 4,000 questions a month. Each request sends 1,200 input tokens and receives 250 output tokens. Illustrative prices are 0.0008 USD per 1,000 input tokens and 0.0032 USD per 1,000 output tokens. What is the monthly model cost?
Show solution
- Input per request: 1,200 / 1,000 x 0.0008 = 0.00096 USD.
- Output per request: 250 / 1,000 x 0.0032 = 0.0008 USD.
- Per request: 0.00176 USD.
- Per month: 4,000 x 0.00176 = 7.04 USD, plus any retrieval and guardrail charges.
Answer: About 7.04 US dollars a month for model tokens, before Knowledge Bases and Guardrails charges.
Summary and key terms
- Foundation model services usually charge per input and output token, with output tokens costing more and prices varying widely between models; retrieval, guardrails, embeddings and customization add their own charges.
- Context engineering and concise output are major cost levers.
- Latency combines time to first token and output speed, and streaming improves perceived responsiveness.
- Amazon Bedrock offers on-demand inference, batch inference at a lower price for non-urgent work, service tiers, Provisioned Throughput for steady high volume and custom models, and cross-Region inference for throughput and resilience within data residency limits.
- Prompt caching, routing and output limits reduce cost further.
- Model selection weighs model type and capabilities, performance on your own evaluation, constraints such as context window and Region, compliance, cost, latency and complexity; the usual choice is the cheapest model that meets every requirement, re-evaluated as models change.
- Input tokens
- Tokens sent to a model, including instructions, documents and history.
- Output tokens
- Tokens the model generates; usually priced higher than input.
- Time to first token
- The delay before a response begins to appear.
- Batch inference
- Processing many requests as an asynchronous job, usually at lower cost.
- Provisioned Throughput
- Dedicated model capacity bought by the hour in Amazon Bedrock.
- Prompt caching
- Reusing processed repeated context to reduce cost and latency.
Practice problems
Work each problem on paper first, then reveal the answer to check.
Why can trimming retrieved documents cut cost?
Show answer
Retrieved documents are input tokens, which are billed.
Which Bedrock option suits end-of-shift summaries?
Show answer
Batch inference.
When does Provisioned Throughput make sense?
Show answer
For steady high volume, guaranteed capacity, or running a customized model.
Lesson quiz · 5 questions
Score 60% or more to complete this lesson.
Create a free account to save your progress, take quizzes and earn a certificate.